
NLP 学习笔记 / NLP007
大语言模型:token、注意力、提示与推理
这一期把前几期的知识串起来:token 来自文本处理,概率来自简单语言模型,向量、权重和反向传播来自神经语言模型。大语言模型(LLM)把它们都用上了。它本质上仍是一个预测下一个 token 的神经语言模型,只是规模大得多,并在三个地方做了改进。训练好之后,我们通过提示(prompt)来使用它,还可以引导它一步步推理。
Large Language Models: Tokens, Attention, Prompting and Reasoning
This note brings the earlier notes together. Tokens came from text processing, probability from simple language models, and vectors, weights and backpropagation from neural language models. A large language model (LLM) uses all of them. It is still a neural language model that predicts the next token, made much larger and improved in three ways. Once it is trained, we use it by prompting, and we can prompt it to reason step by step.
- 章节 / section
- 关键概念 / key term
- 阅读提示 / reading note
 ELLE · 阅读向导 / READING COMPANION
把概念连起来,再往下读 / Take a moment to connect the ideas
和 Elle 一起理清基础概念 / A few foundations, with Elle
点开概念理清区别,再试三道小题;选错后可以重新选择。 / Tap a concept to explore it, then try three short questions. You can change any answer.
token / Token
模型当作一个单位来读的一串字符:整词、词的一部分或标点。unhappy 会切成 un + happy,所以没见过的词也能用见过的片段拼出来。 / A chunk of characters the model reads as one unit: a whole word, part of a word or punctuation. unhappy becomes un + happy, so even an unseen word can be built from known pieces.
上下文嵌入 / Contextual embedding
为某个 token 的这一次出现计算的向量,取决于它周围的 token。键盘旁的 mouse 和被猫追的 mouse 得到不同的向量;静态嵌入则会给它们同一个向量。 / A vector for one occurrence of a token, computed from the tokens around it. mouse next to keyboard and mouse chased by a cat get different vectors; a static embedding would give them the same one.
注意力机制 / Attention
Transformer 里的一个部件:学习每个 token 应该在多大程度上影响另一个 token,再按这些权重组合。在 “…models is that they” 里,they 主要取自 models。 / The part of the Transformer that learns how strongly each token should influence another, then combines them by those weights. In "…models is that they", they draws mostly on models.
上下文学习 / In-context learning
在提示里放几个做好的示例,让模型在回答时看懂任务。不重新训练,权重完全不变。 / Putting a few solved examples in the prompt so the model picks up the task while answering. No retraining: the weights stay exactly the same.
思维链 / Chain-of-thought
提示模型在给答案之前写出推理步骤:可以给带步骤的示例,也可以只加一句 “Let's think step by step”。DeepSeek-R1 这类推理模型则被训练成自己先推理。 / Prompting the model to write out its reasoning steps before the answer, either with worked examples or with "Let's think step by step". Reasoning models such as DeepSeek-R1 are trained to do this on their own.
全景图:从 token 到推理
从左上角开始。第一块是 LLM 对简单神经语言模型的三点改进:输入是 token 而不是整词(紫色几行是分词、token 和嵌入的定义)、更长的前文,以及动态语境;注意力机制负责算出每个 token 应该在多大程度上影响其他 token。下面是提示与上下文学习,也就是日常使用 LLM 的方式。右边是 Transformer 和课程里的两大模型家族(GPT 与 Llama),再往下是思维链。最下面一排是专门训练来推理的模型(以 DeepSeek-R1 为例)、课上提到的两个挑战,右下角是我的重点。
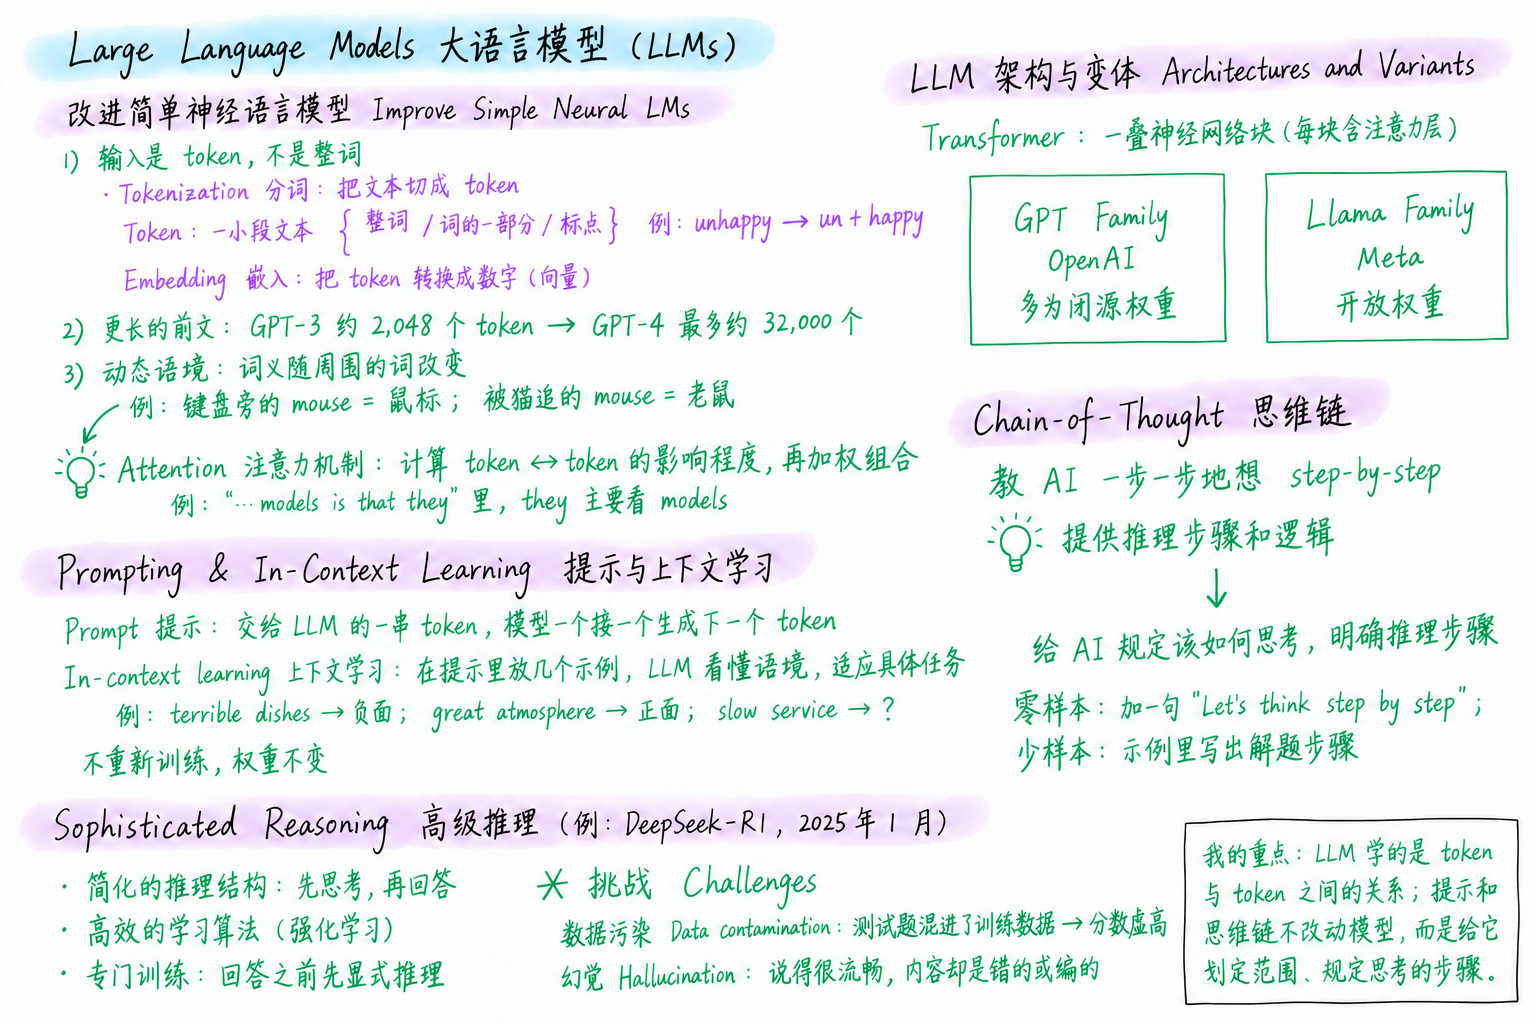
根据我的手写笔记整理,修正了几处术语,并补充了简短的例子。
The big picture: from tokens to reasoning
Start at the top left. The first block lists the three ways an LLM improves on a simple neural language model: tokens instead of words (the violet lines define tokenization, tokens and embeddings), a much longer preceding context, and a dynamic context, where attention works out how much each token should influence the others. Below it are prompting and in-context learning, the everyday way of using an LLM. On the right, the Transformer and the two model families from the course (GPT and Llama), then chain-of-thought. Along the bottom, models trained to reason (DeepSeek-R1 as the example), the two challenges named in the lecture, and my takeaway at the bottom right.
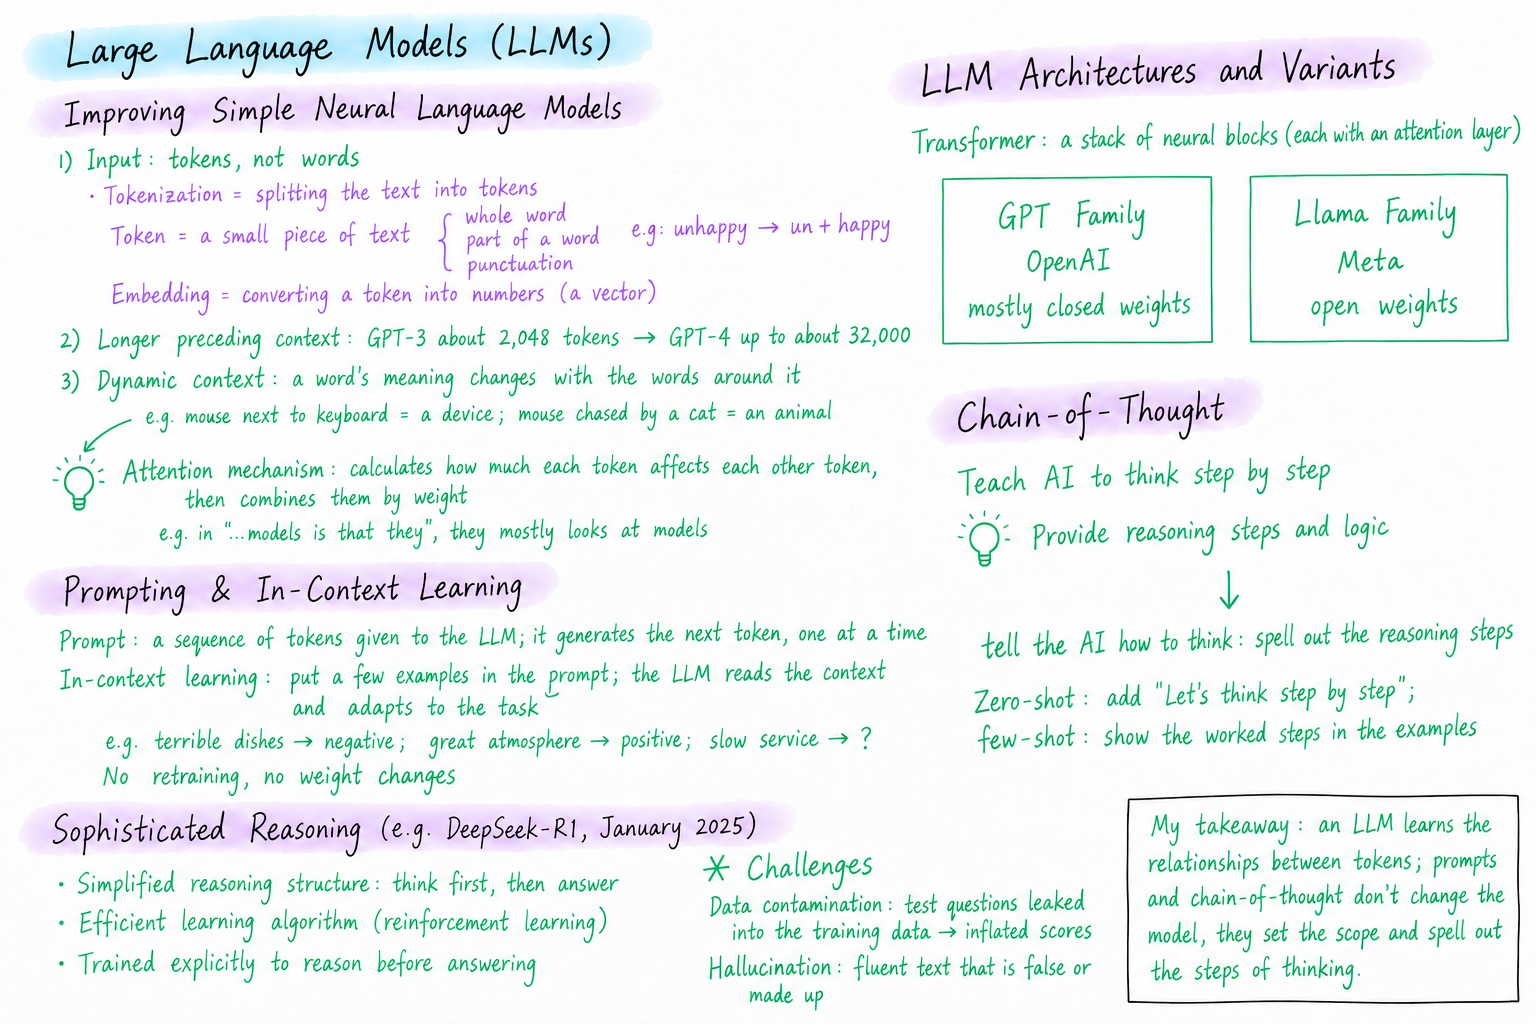
Tidied up from my handwritten page, with a few terms corrected and short examples added.
什么是大语言模型
大语言模型是用海量文本训练、用来预测下一个 token 的神经语言模型。它以 Transformer 为架构,权重数以十亿计,有的超过一万亿。它的基本工作和上一期一样:拿到前面的 token,算出下一个 token 的概率分布,选一个,再重复。变的是规模和设计:更多的权重和多得多的训练数据,让它学到更丰富的语言规律。于是同一个模型,只要用自然语言提出要求,就能回答问题、写总结、翻译和分类,不再需要每个任务单独训练一个模型。
课程里说的“大”,指两件事:权重(参数)的数量,以及模型能处理的上下文长度。
What a large language model is
A large language model is a neural language model trained on a very large amount of text to predict the next token. Built on the Transformer architecture, it has billions of weights, sometimes more than a trillion. The basic job has not changed since the last note: take the tokens so far, compute a probability distribution for the next one, pick one, and repeat. What changed is scale and design. More weights and far more training data let it learn much richer patterns of language, so one model can answer questions, summarize, translate and classify when asked in plain language, without a separate model for each task.
"Large" refers to two things in the course: the number of weights (parameters), and the length of context the model can handle.
改进一:用 token,不用整词
简单神经语言模型的输入是整词,LLM 的输入是 token。token 是经常一起出现的一串字符:可以是整词、词的一部分,也可以是标点。分词(tokenization) 把文本切成 token,每个 token 再变成一个向量,也就是它的嵌入(embedding)。
| 原文 | 切成的 token(课程例子) |
|---|---|
| The | The |
| siblings | sibling + s |
| unhappy | un + happy |
| ? | ? |
GPT-3 的词表有 50,257 个 token:既有 love、are 这样的常见词,也有 dis 这样的词缀,还有标点。按子词切分有两个好处:没见过的词也能用见过的片段拼出来;un 这样的片段本身就带着意义。这正是前面文本处理那几期讲过的分词,如今成了模型真正的输入。
Improvement 1: tokens instead of words
A simple neural language model takes whole words as input. An LLM takes tokens. A token is a chunk of characters that often occurs together: a whole word, part of a word, or punctuation. Tokenization splits the text into tokens, and each token is then turned into a vector, its embedding.
| Text | Tokens (course example) |
|---|---|
| The | The |
| siblings | sibling + s |
| unhappy | un + happy |
| ? | ? |
GPT-3's vocabulary has 50,257 tokens: frequent words such as love and are, affixes such as dis, and punctuation. Sub-word tokens have two advantages. An unknown word can still be built from known pieces, and pieces such as un carry meaning of their own. This is the tokenization from the text-processing notes, now as the actual input of the model.
改进二:更长的前文
上一期的简单神经语言模型只看前三个词。让它续写 “The promise of large language models is that they…”,它只看得到 “is that they”,几乎看不出话题是什么。LLM 能把前面成千上万个 token 都考虑进去。
| 模型 | 最多能看的前文 | 大约相当于 |
|---|---|---|
| 简单神经语言模型(上一期) | 3 个词 | 一个短语 |
| GPT-3 | 2,048 个 token | 一篇杂志长文 |
| GPT-4(大版本,2023 年) | 约 32,000 个 token | 一部短篇小说 |
能看到的前文越多,下一个词就越能和前文保持一致、连贯。上下文长度一直是推动 LLM 进步的主要因素之一。
Improvement 2: a much longer context
The simple neural language model in the last note looked at only the previous three words. Asked to continue "The promise of large language models is that they…", it would see only "is that they", which says almost nothing about the topic. An LLM can take thousands of preceding tokens into account.
| Model | Maximum context | About the length of |
|---|---|---|
| Simple neural LM (last note) | 3 words | A short phrase |
| GPT-3 | 2,048 tokens | A long magazine article |
| GPT-4 (larger version, 2023) | About 32,000 tokens | A short novel |
The more context the model can see, the more consistent and coherent its next word can be. Context length has been one of the main drivers of improvement.
改进三:上下文嵌入与注意力机制
在简单神经语言模型里,每个词只有一个静态嵌入。“I'm using both the keyboard and the mouse” 里的 mouse(鼠标),和 “the cat chased away the mouse” 里的 mouse(老鼠),用的是同一个向量,电脑配件和动物的特征被混在了一起。
LLM 则为每一次出现计算一个上下文嵌入(contextual embedding):一个 token 的向量取决于它周围的 token。旁边是 keyboard,mouse 就偏向鼠标;旁边是 chased 和 cat,就偏向老鼠。对代词这类本身几乎没有意义的词,这一点更重要。在 “The promise of large language models is that they…” 里,they 的意思要等知道它指的是 models 才清楚。
完成这件事的部件叫注意力机制(attention mechanism)。它学习语境中每个 token 应该在多大程度上影响另一个 token 的表示,再按这些权重组合起来。课程的例子里,they 的含义大约 75% 来自 models。注意力是 Transformer 的核心思想(Vaswani 等,2017)。
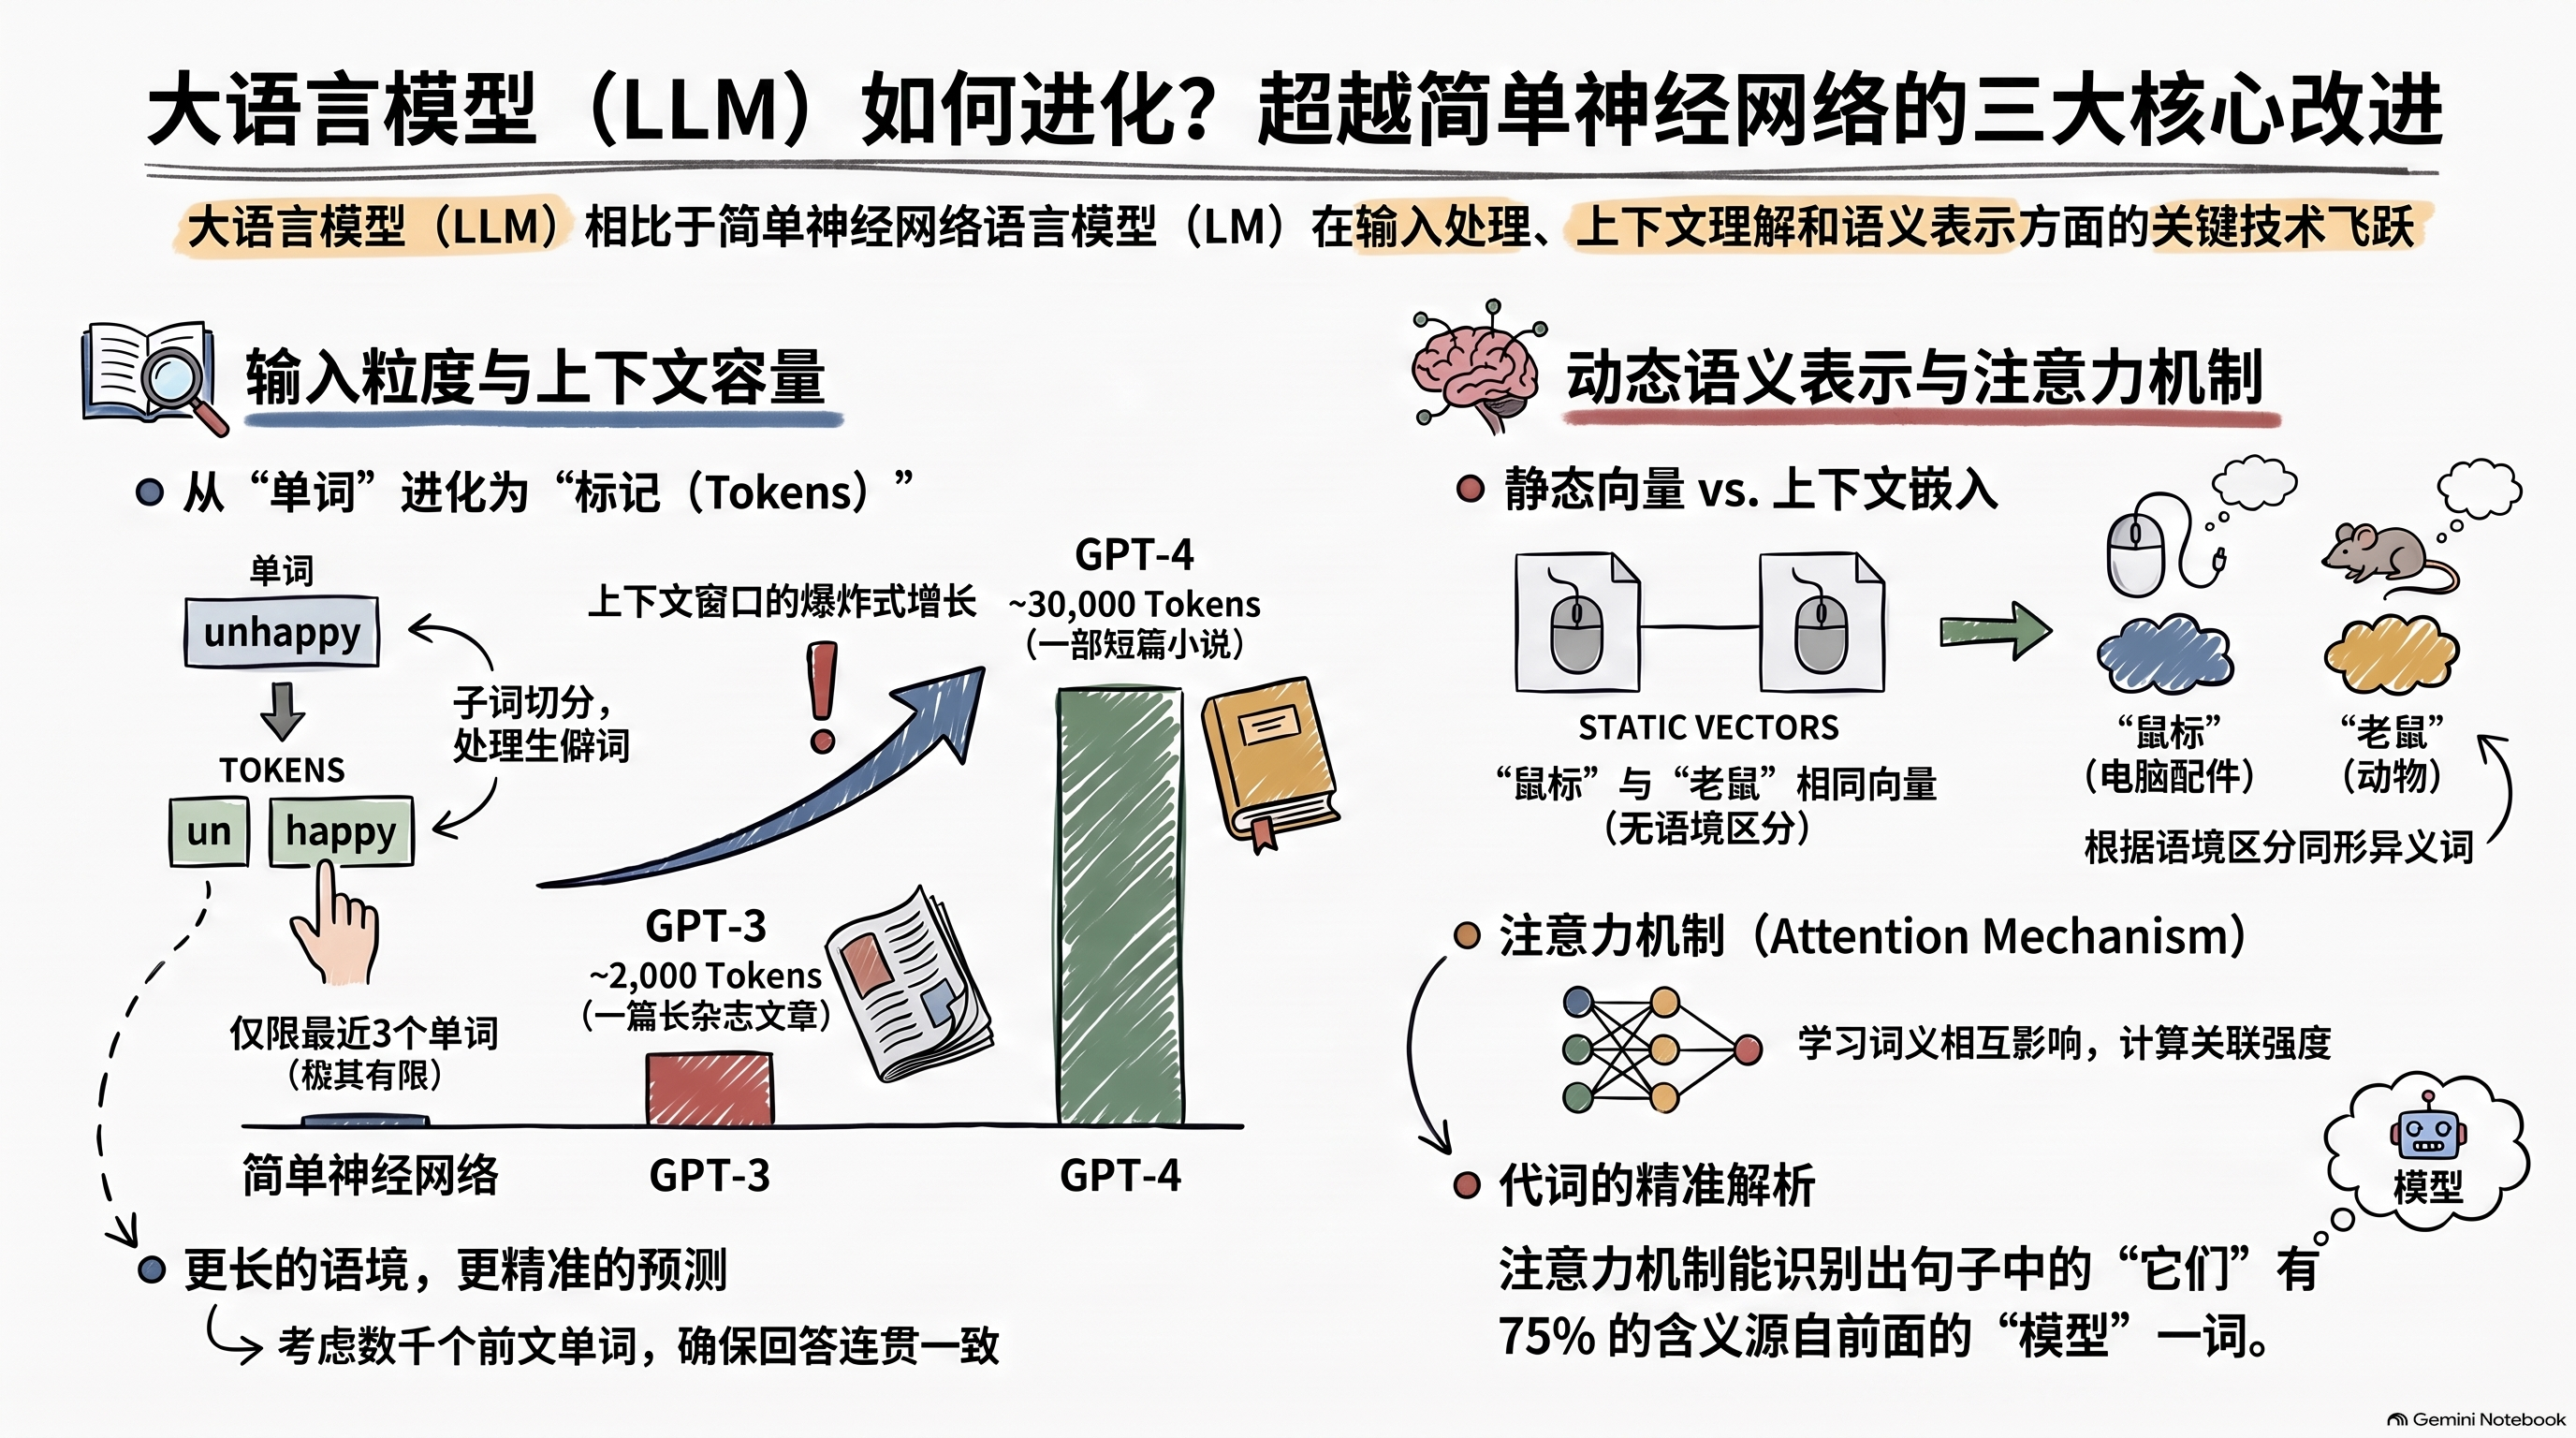
阅读提示:75% 是课程用来说明注意力的示意,不是固定的数值;不同模型、不同层的注意力分布都不一样。GPT-4 发布时有 8,192 和 32,768 个 token 两个版本,图中约 30,000 指的是大版本。
Improvement 3: contextual embeddings and attention
In a simple neural language model, every word has a single static embedding. The mouse in "I'm using both the keyboard and the mouse" and the mouse in "the cat chased away the mouse" get the same vector, which mixes features of a computer device with features of an animal.
An LLM computes a contextual embedding for each occurrence instead: the vector for a token depends on the tokens around it. Next to keyboard, mouse leans toward the device; next to chased and cat, it leans toward the animal. This matters even more for words with little meaning on their own, such as pronouns. In "The promise of large language models is that they…", they means nothing until we know it refers to models.
The part of the network that does this is the attention mechanism. It learns how strongly each token in the context should influence the representation of another token, and combines them by those weights. In the course example, about 75% of the meaning of they comes from models. Attention is the key idea of the Transformer (Vaswani et al., 2017).
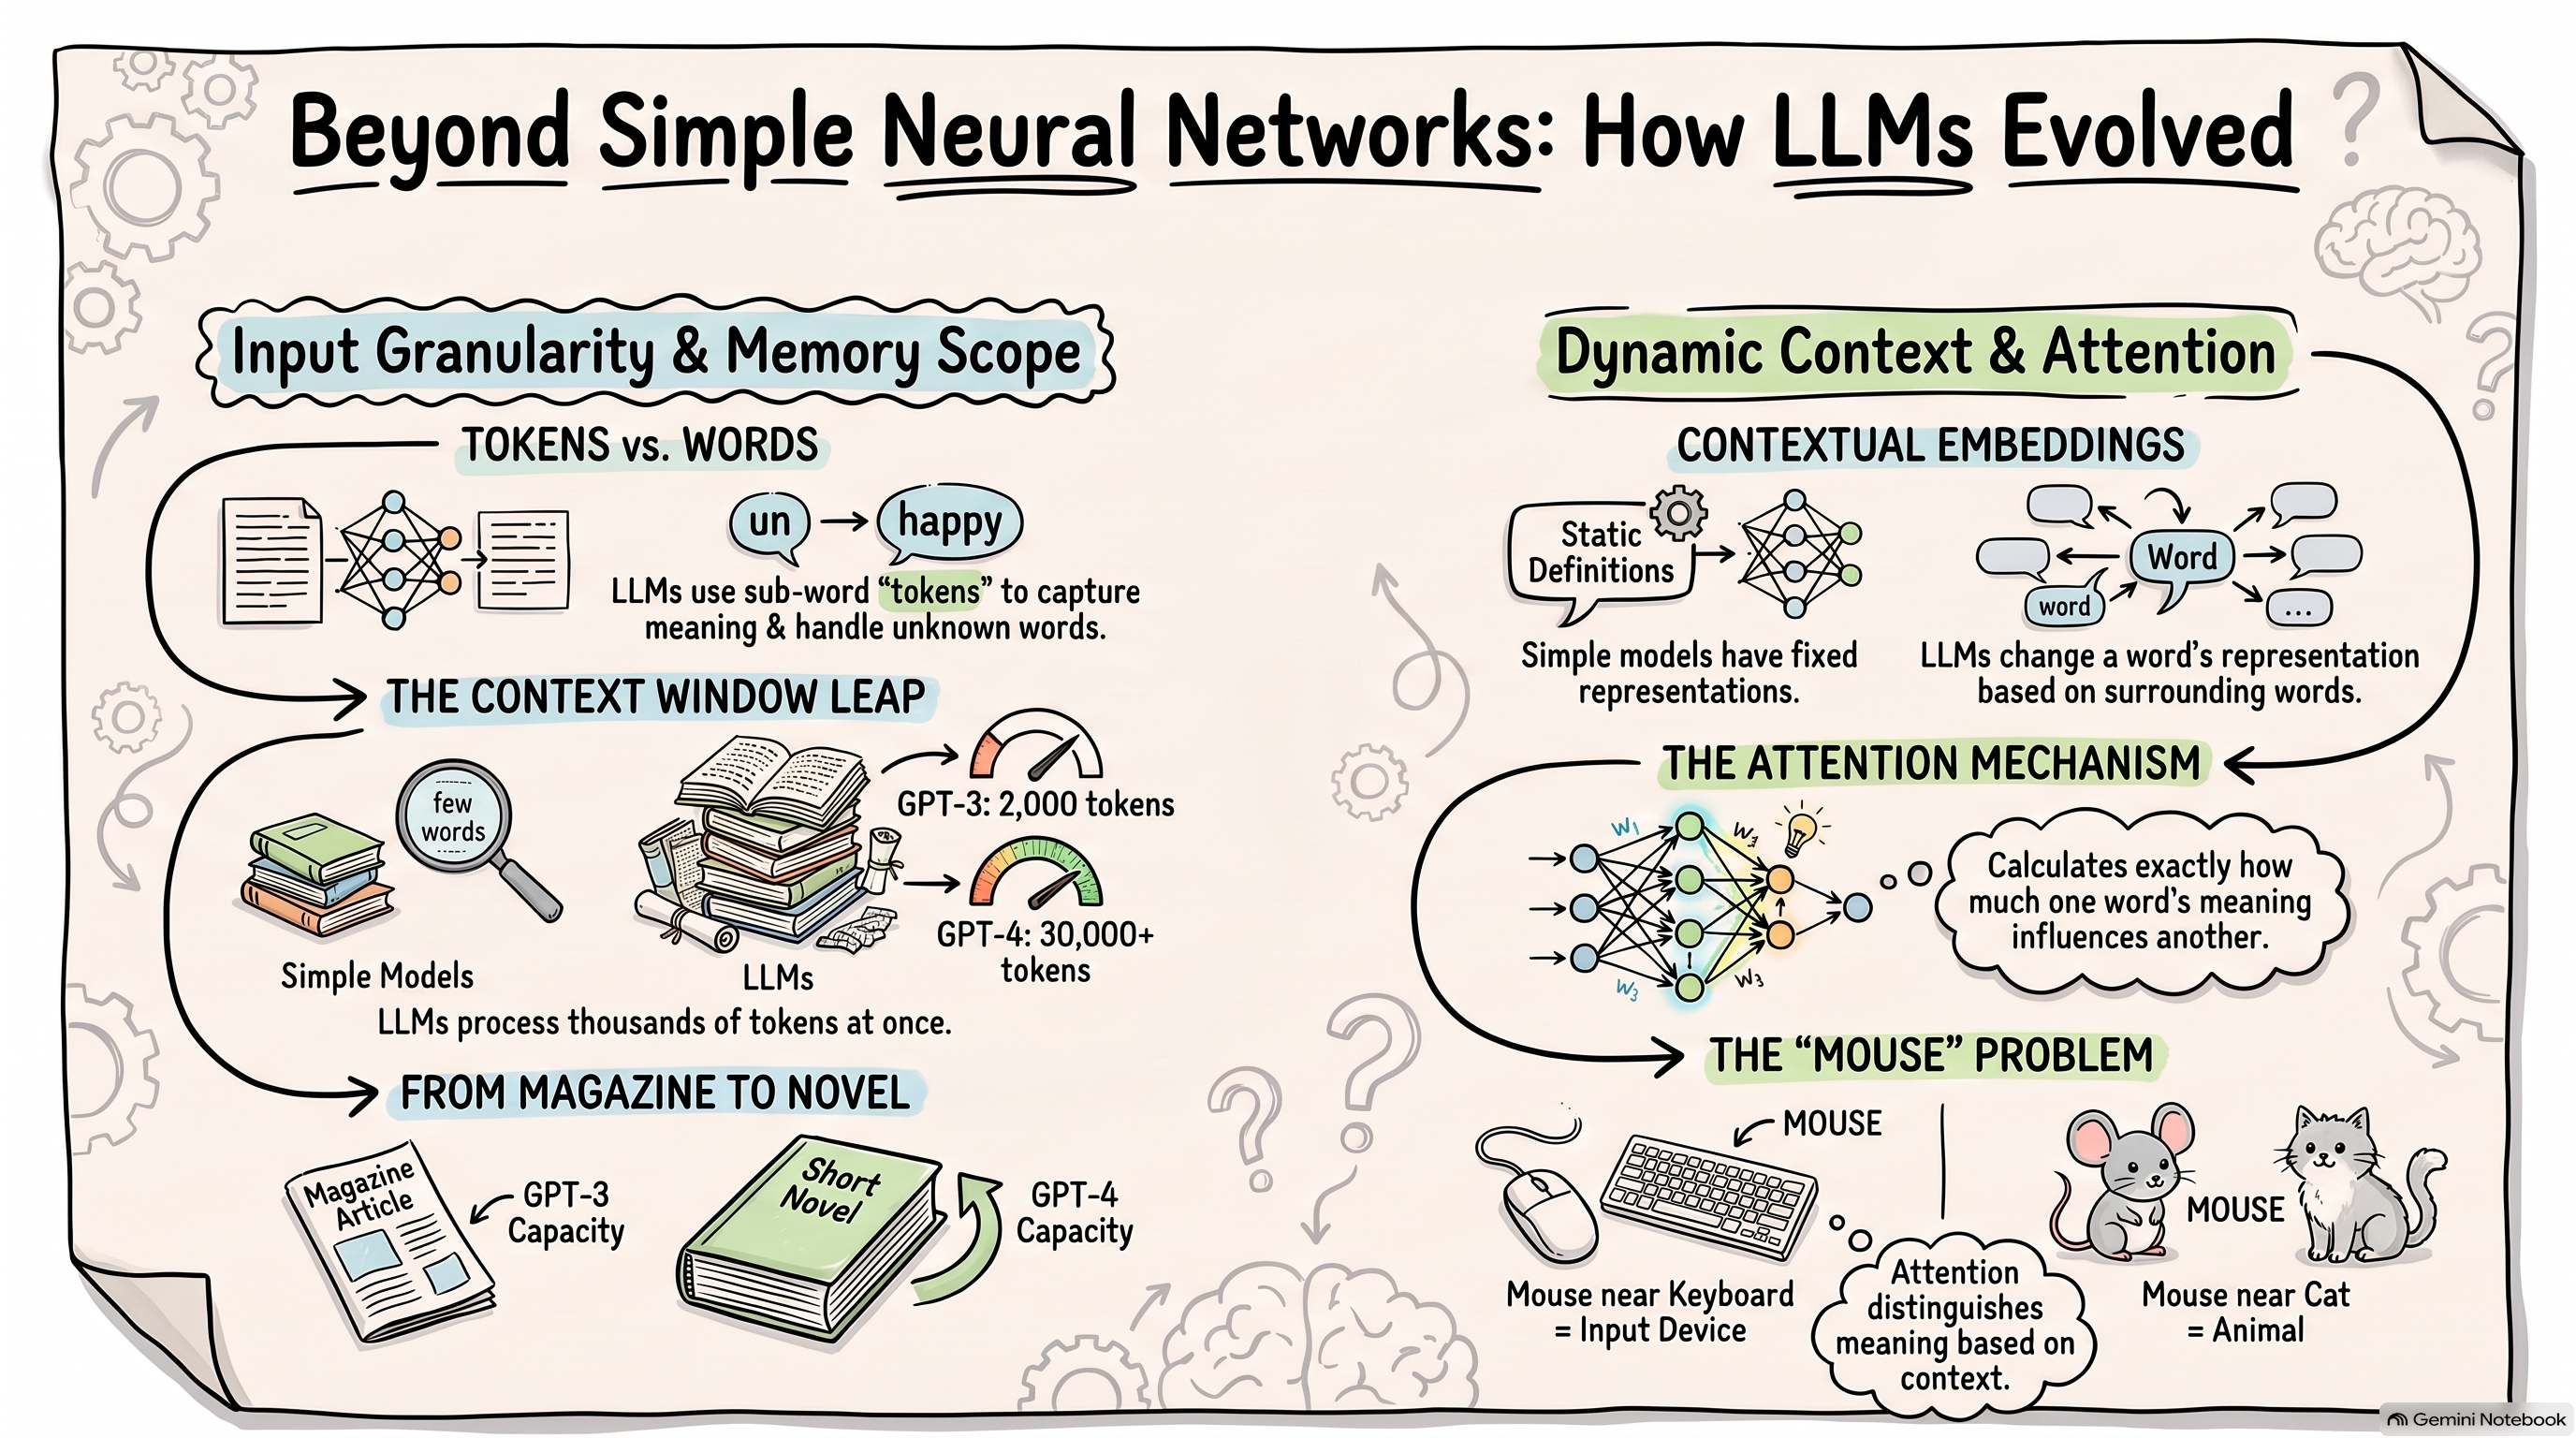
Reading note: attention weights are learned scores, not an exact measure of how much one word's meaning influences another. GPT-4 was released in an 8,192-token version and a 32,768-token version; the 30,000+ figure refers to the larger one.
Transformer 与两大模型家族
从结构上看,LLM 是一个叫 Transformer 的巨型神经网络,由一个个“块”叠起来。每个块里有一个注意力层,负责构建上下文嵌入,还有几层前馈网络,作用和上一期的简单神经网络差不多。各个块结构相同,但权重各不相同。输入文本变成嵌入后,一层层往上流过这些块,最上面输出下一个 token。
训练方式和之前一样:在海量文本(常常是整个网络规模的文本)上预测下一个词或被遮住的词,算出误差,再用反向传播修正权重。
课程介绍了两个常见的模型家族:
| GPT 家族 | Llama 家族 | |
|---|---|---|
| 开发者 | OpenAI | Meta |
| 最出名的应用 | ChatGPT | 大量基于 Llama 的模型,针对特定任务和领域做了调整 |
| 权重 | 多为闭源:通过 OpenAI 的应用和 API 使用 | 开放:可按 Meta 的许可协议下载 |
| 规模 | 数十亿权重乃至更多 | 约 10 亿到 4,050 亿个权重(Llama 3 系列) |
这里的“开放”指开放权重(open weights):可以下载训练好的模型,自己运行或微调。Llama 用的是 Meta 自己的许可协议,例如月活跃用户超过 7 亿的公司需要另向 Meta 申请。OpenAI 在 2025 年也发布了两个开放权重的 gpt-oss 模型,但它的旗舰 GPT 模型仍是闭源的。其他常见的家族还有 Claude、Gemini、Qwen(通义千问)和 DeepSeek。它们大多以 Transformer 为基础,区别在于规模、训练数据、训练方法和开放程度。
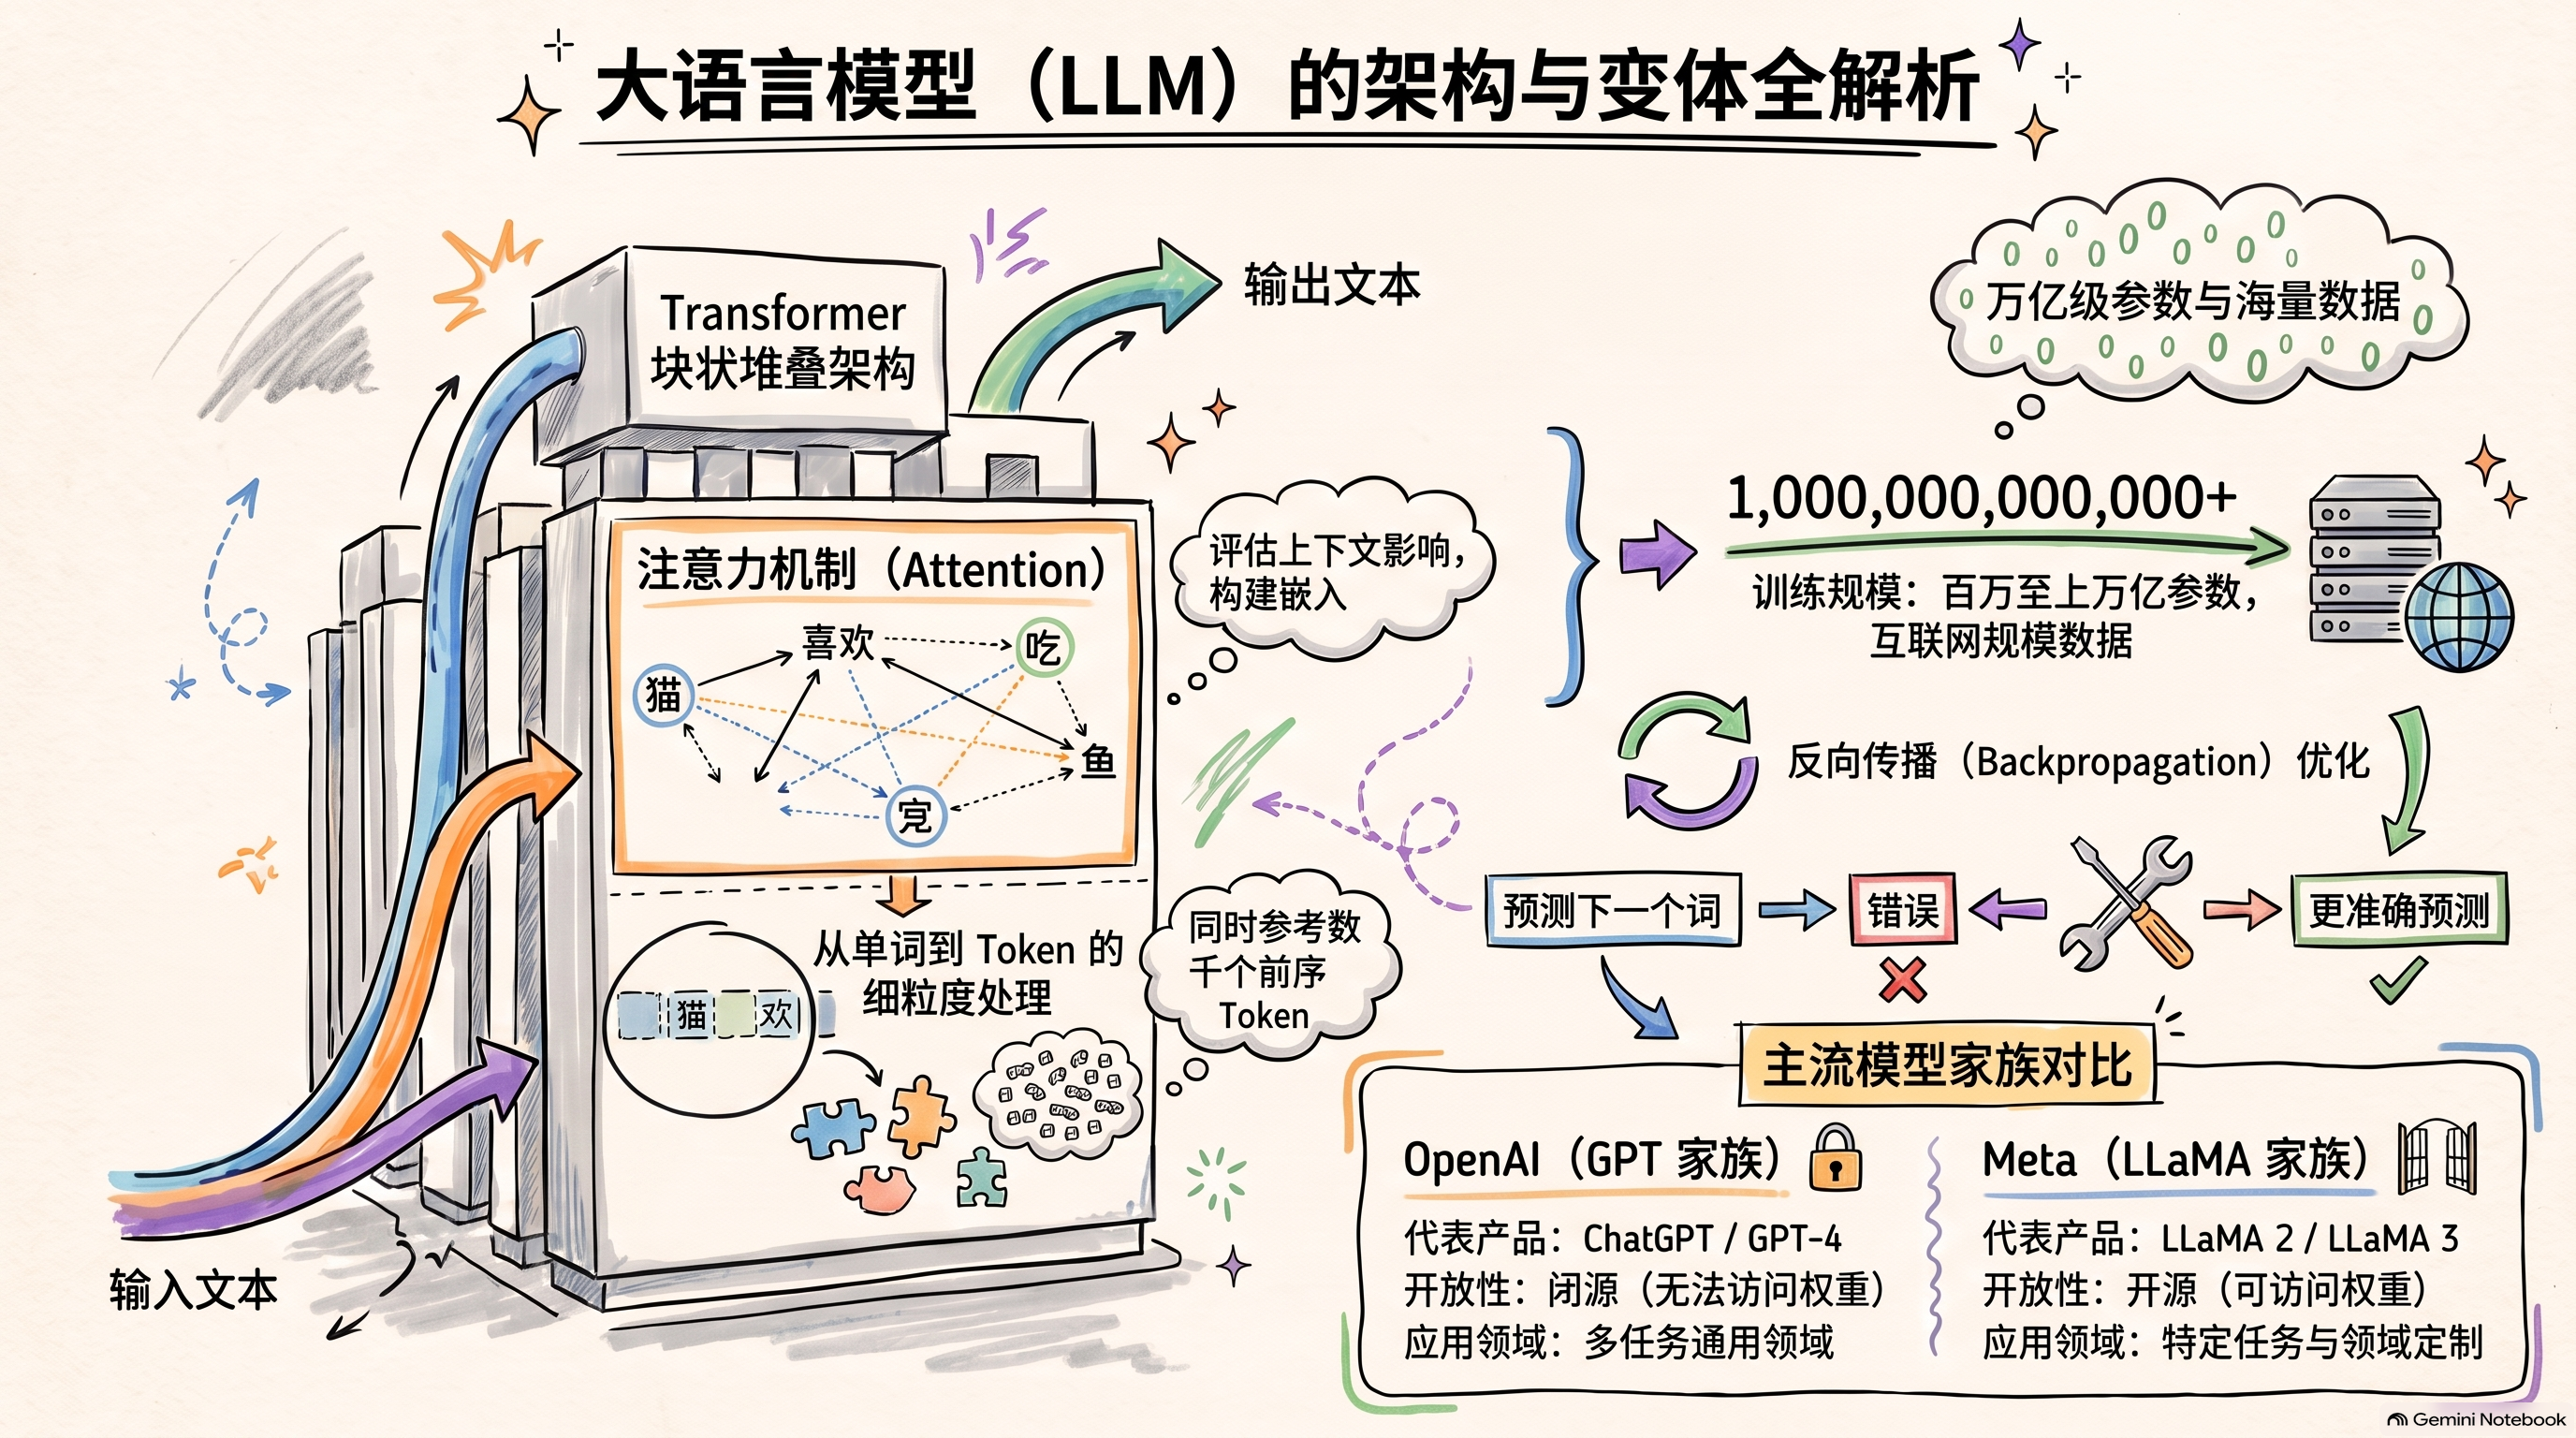
阅读提示:图中把 Llama 的应用领域写成“特定任务与领域定制”、GPT 写成“多任务通用”,这并不是两者真正的区别;两者都是通用模型,开放权重让 Llama 更方便被别人拿去针对特定领域微调。可靠的区别是权重是否开放。现在的写法是 Llama。
The Transformer and two model families
Architecturally, an LLM is a huge neural network called the Transformer, built as a stack of blocks. Each block contains an attention layer, which builds the contextual embeddings, and feed-forward layers that work much like the simple network in the last note. All blocks have the same structure but their own weights. The input text, as embeddings, flows up through the blocks, and the top produces the next token.
Training works the same way as before: predict the next (or a missing) word in a huge amount of text, often web-scale, measure the error, and backpropagate to revise the weights.
The course shows two popular families:
| GPT family | Llama family | |
|---|---|---|
| Developer | OpenAI | Meta |
| Best-known use | ChatGPT | Many models built on Llama, adapted to specific tasks and domains |
| Weights | Mostly closed: used through OpenAI's apps and API | Open: downloadable under Meta's license |
| Scale | Billions of weights and more | From about 1 billion to 405 billion weights (Llama 3 series) |
"Open" here means open weights: you can download the trained model and run or fine-tune it yourself. Llama is released under Meta's own license, which, for example, requires companies with more than 700 million monthly users to ask Meta for permission. OpenAI also released two open-weight models, gpt-oss, in 2025, though its flagship GPT models remain closed. Other well-known families include Claude, Gemini, Qwen and DeepSeek. Most share the same Transformer basis and differ in size, training data, training method and openness.
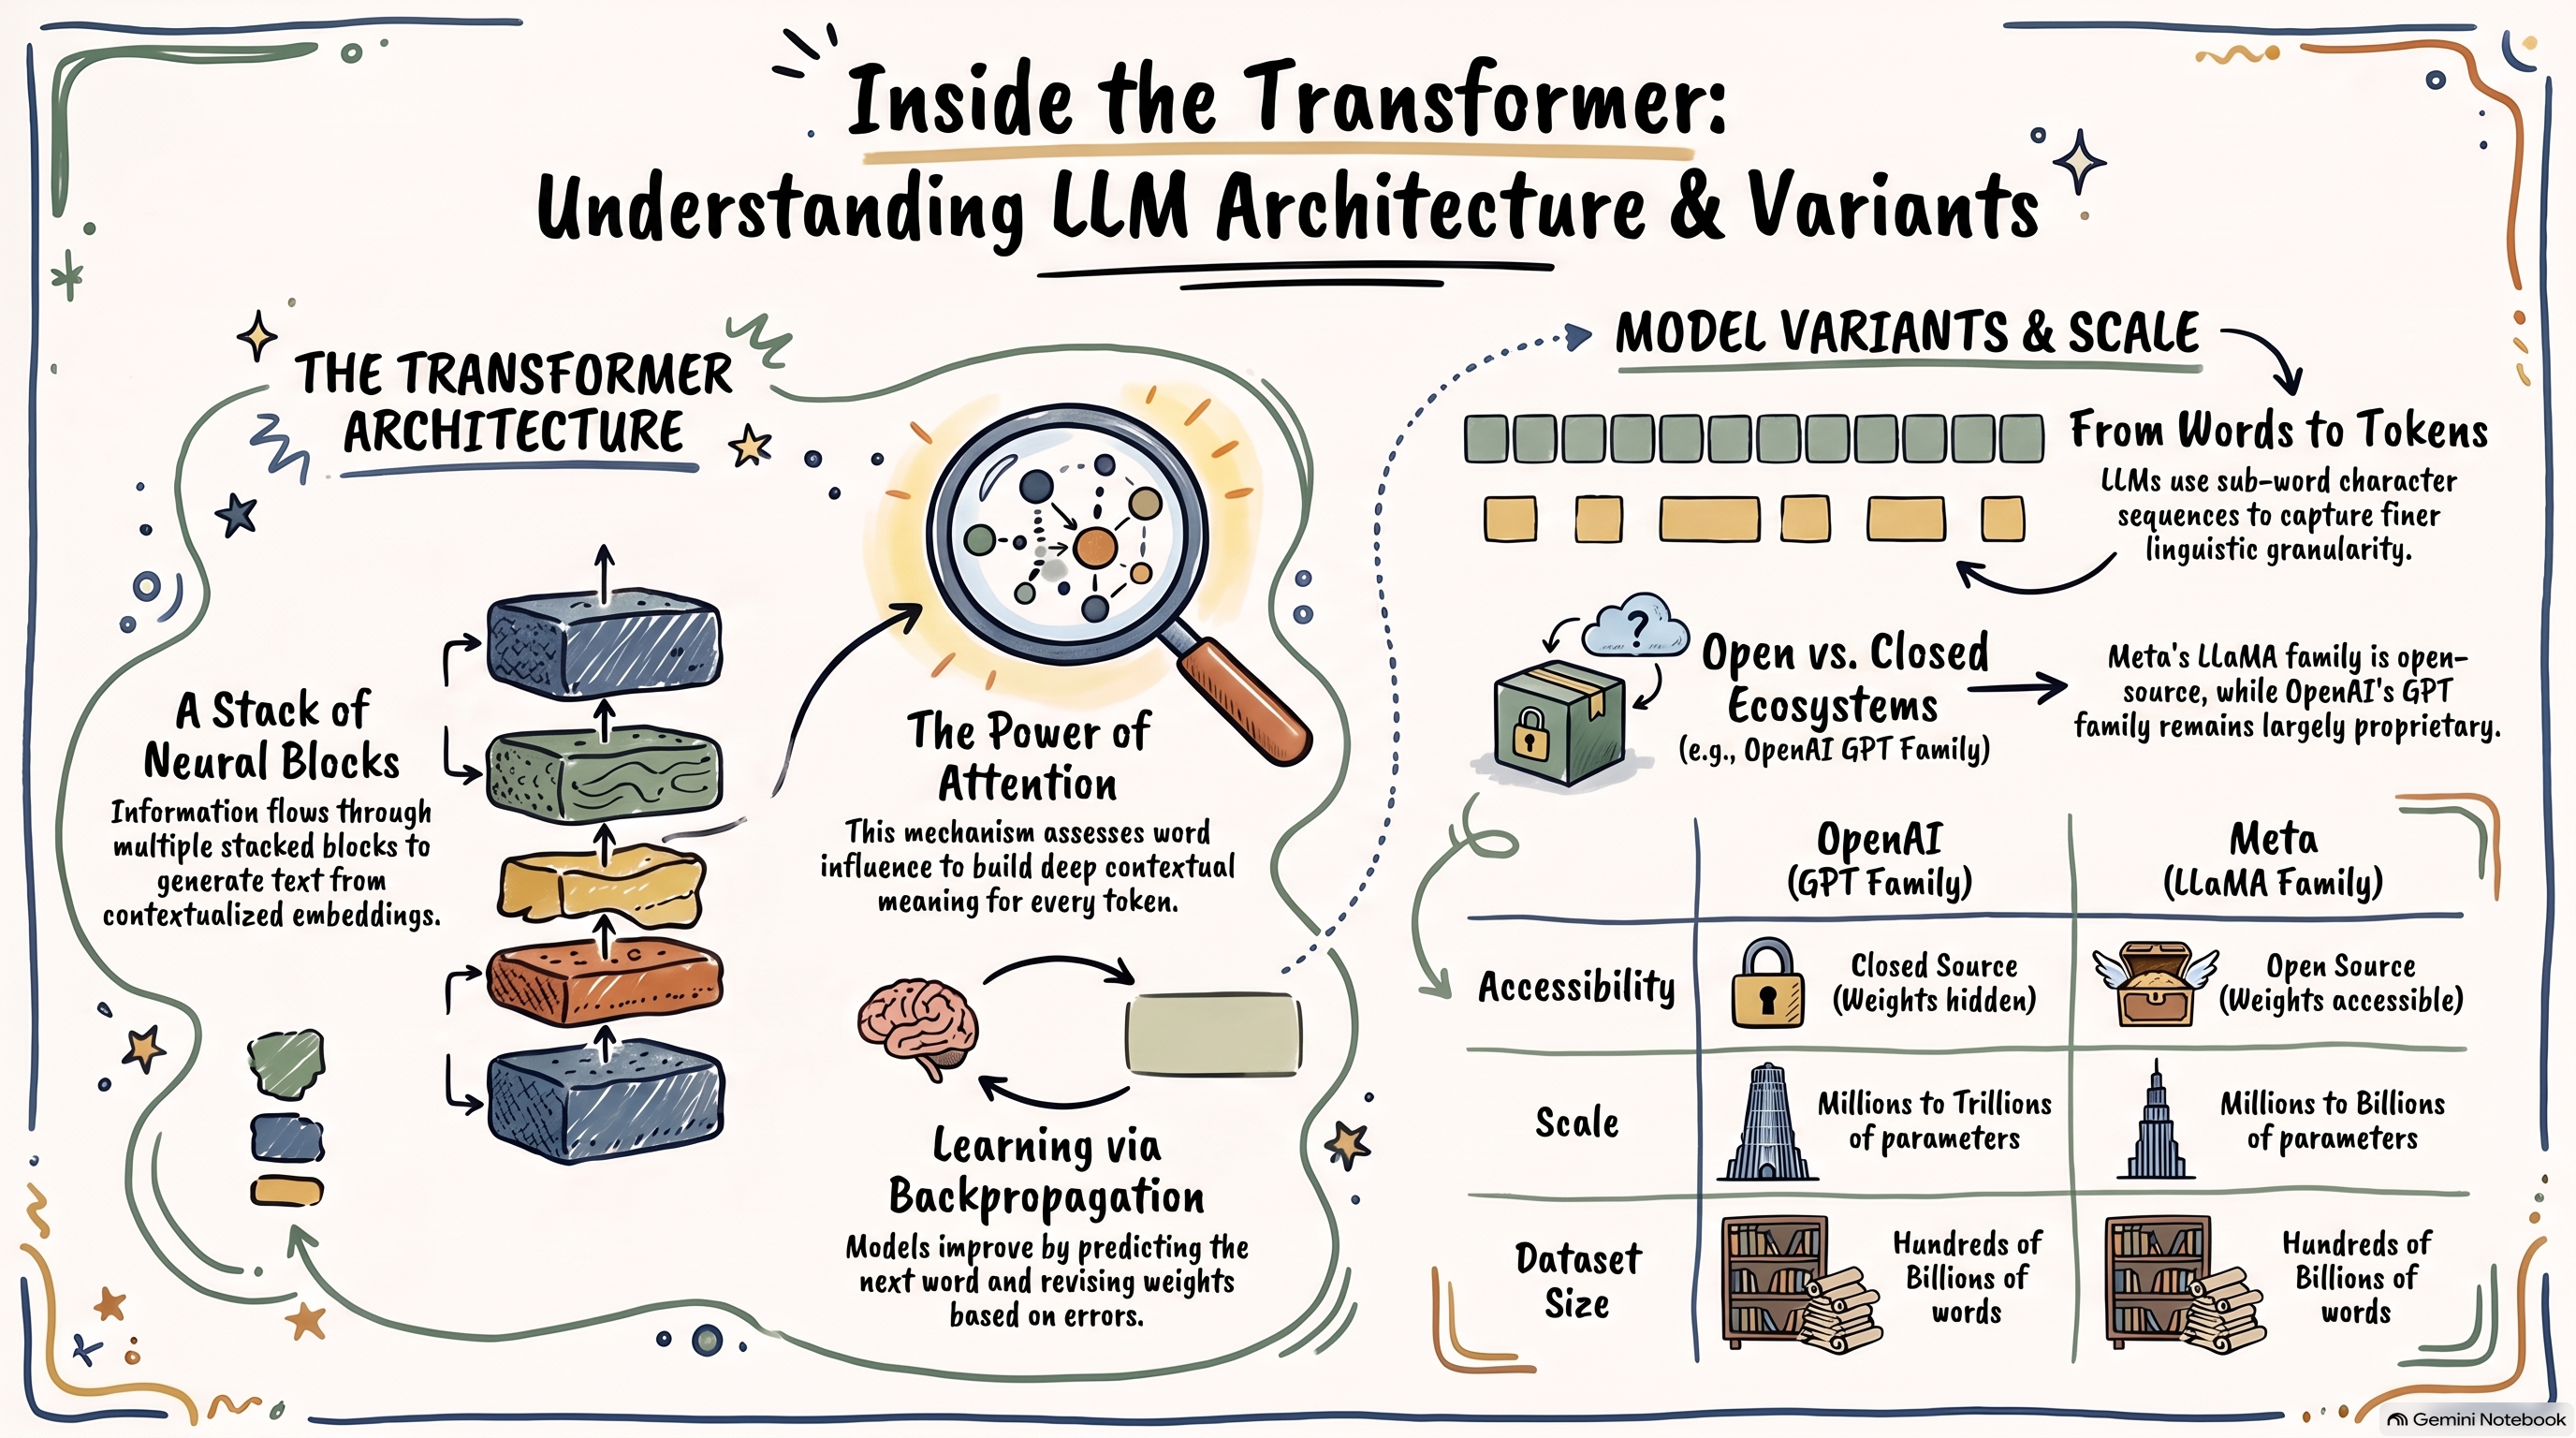
Reading note: the scale row is rough. Llama models range from about 1 billion to 405 billion weights, and OpenAI has not published the size of its recent GPT models. The current spelling is Llama.
提示与上下文学习
使用 LLM 最基本的方式,来自任何语言模型都在算的那件事。你给它一串 token,也就是提示(prompt);它预测下一个 token,接在后面,再预测下一个,直到生成结束标记为止。在 ChatGPT 里输入“我已经发烧四天了,该怎么办?”,发生的正是这个过程:回答是一个 token 一个 token 生成出来的。
提示也在划定范围。模型是用极其广泛的文本训练出来的,可以往很多方向回答;告诉它我们想要什么、要什么形式,就缩小了范围,回答通常也更好。
上下文学习(in-context learning,ICL) 再进一步:先在提示里放几个做好的示例,再放新的问题,模型从示例里看懂任务。
| 提示方式 | 提示里写什么 |
|---|---|
| 普通提示 | 评论“good meal”的情感是 |
| 上下文学习 | terrible dishes:负面 / great atmosphere:正面 / bland food:负面 / slow service:? |
关键在于:不重新训练,权重不变。模型只是在回答的过程中,凭语境适应了任务;提示一拿走,这份“学习”也就没了。所以说 LLM 是“学得很快”的模型。
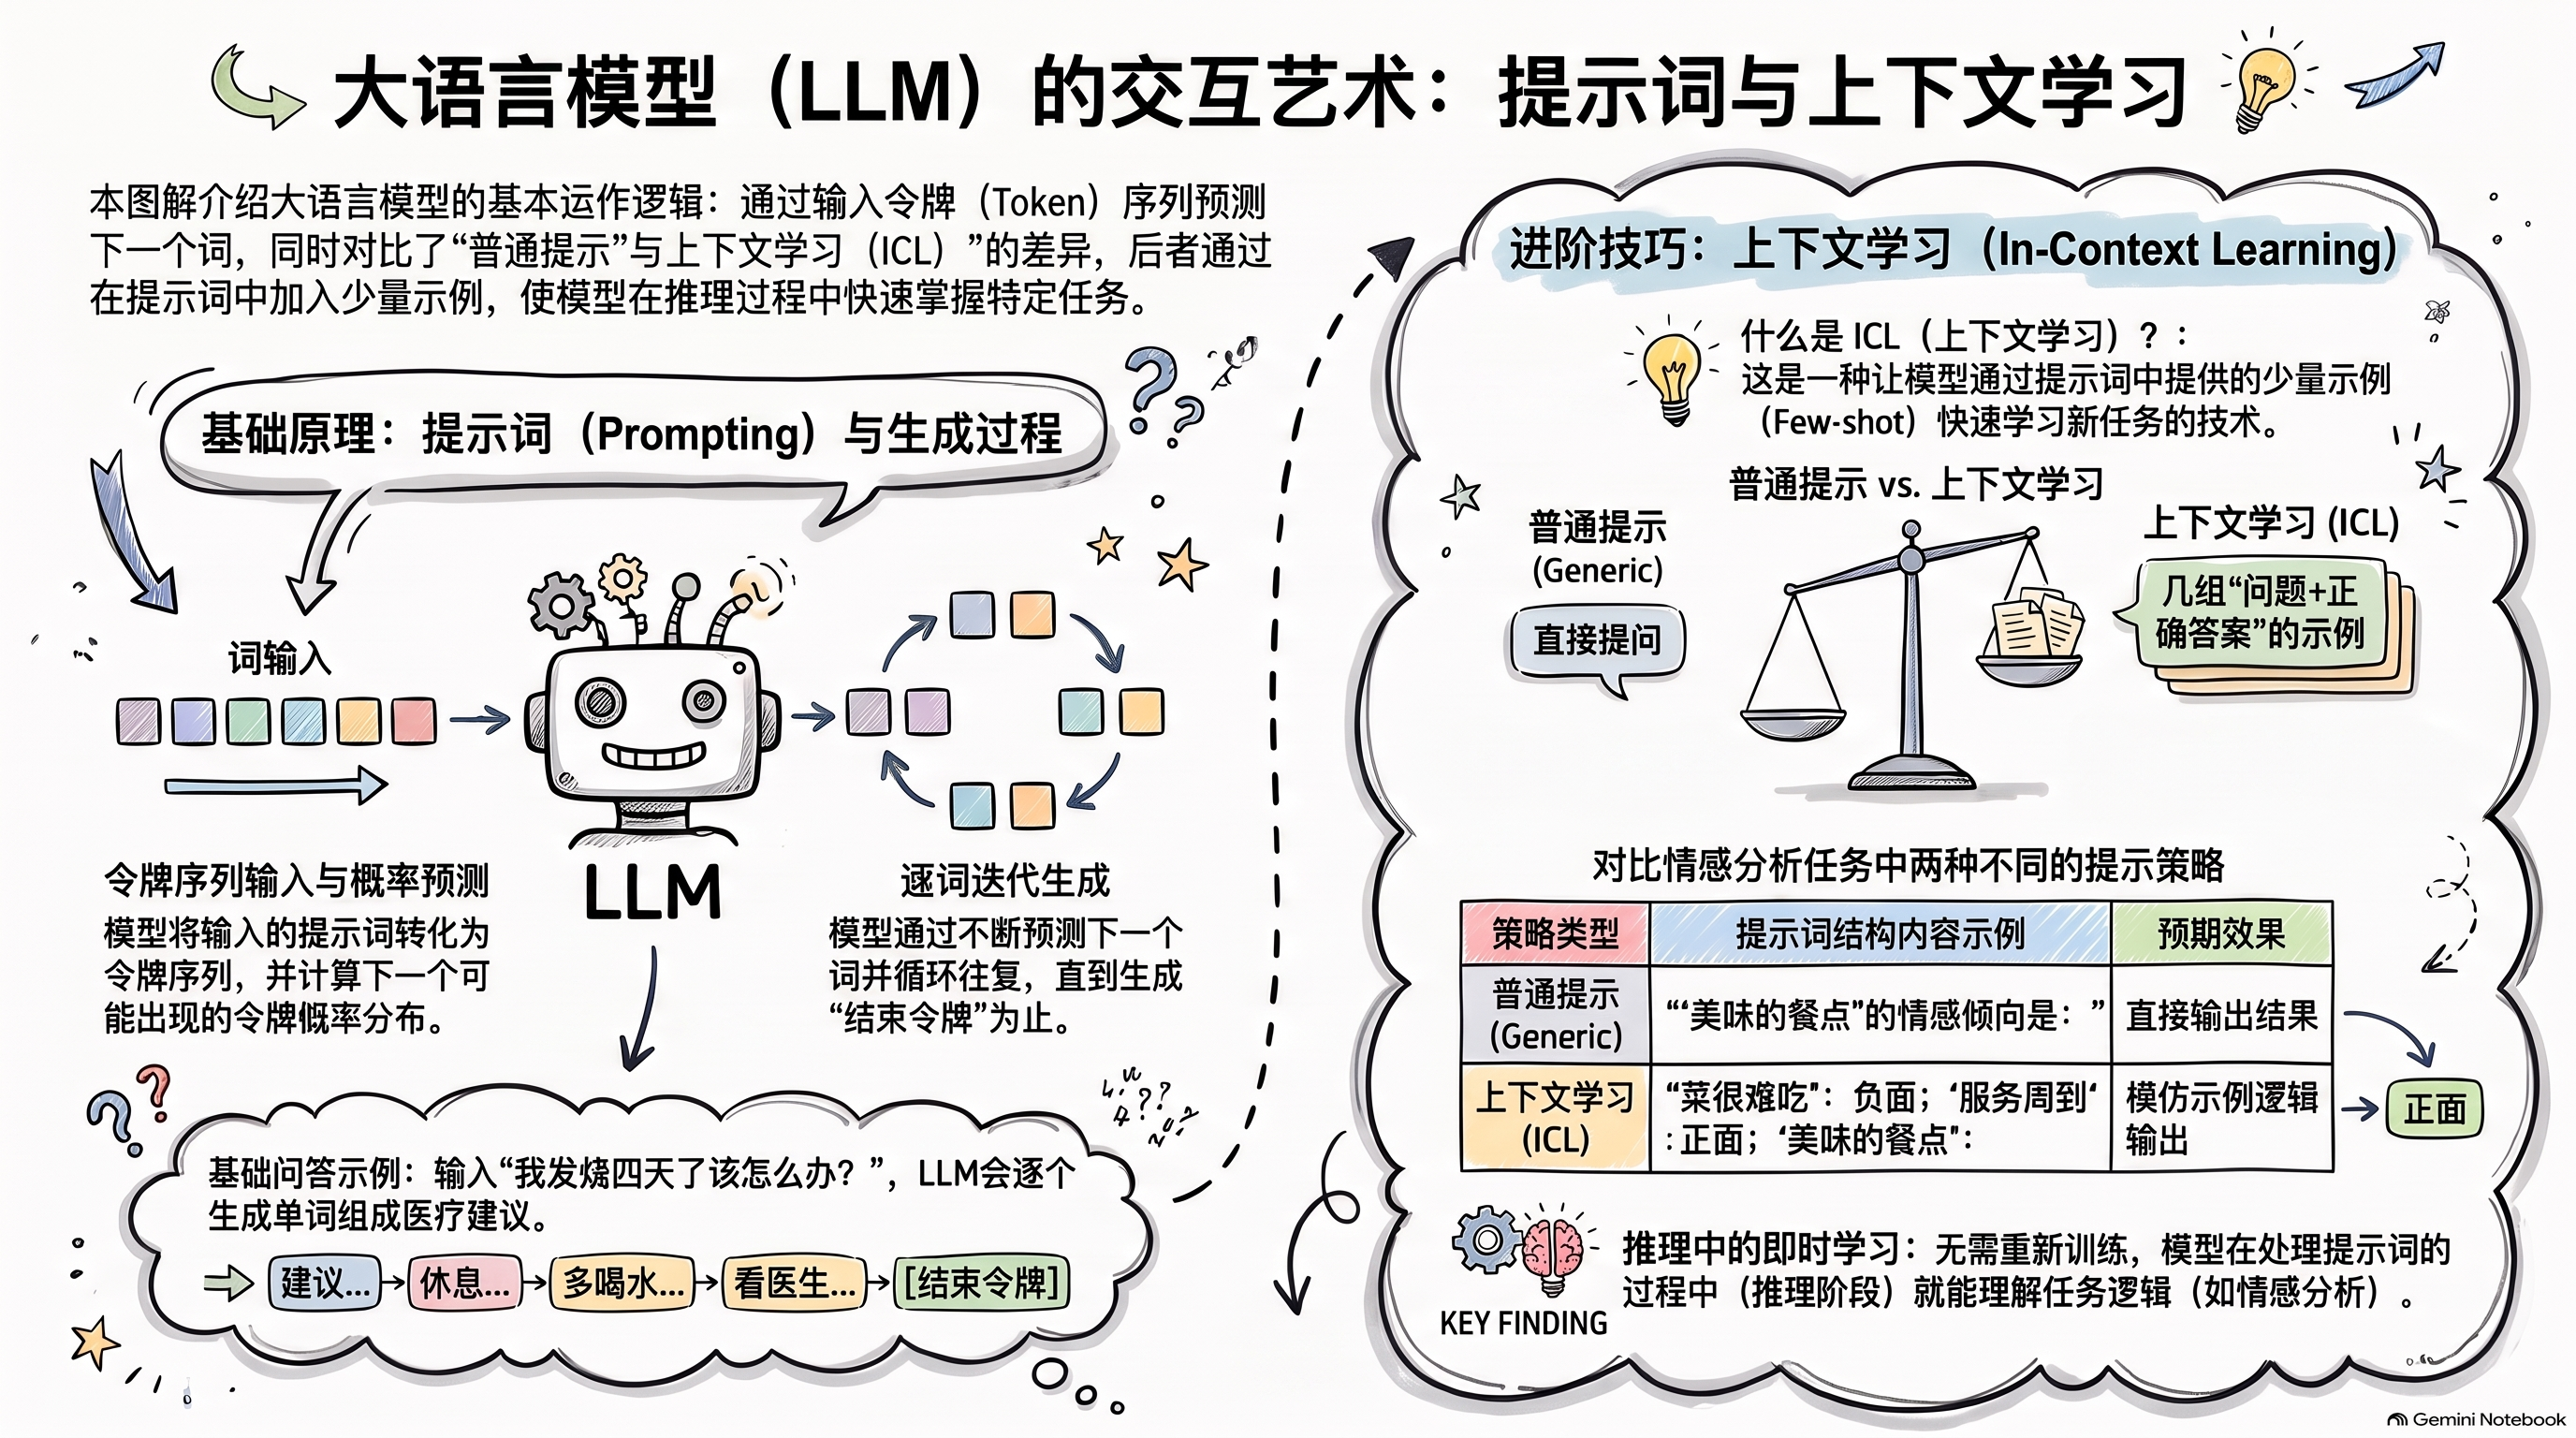
阅读提示:图中的“令牌”就是 token。
Prompting and in-context learning
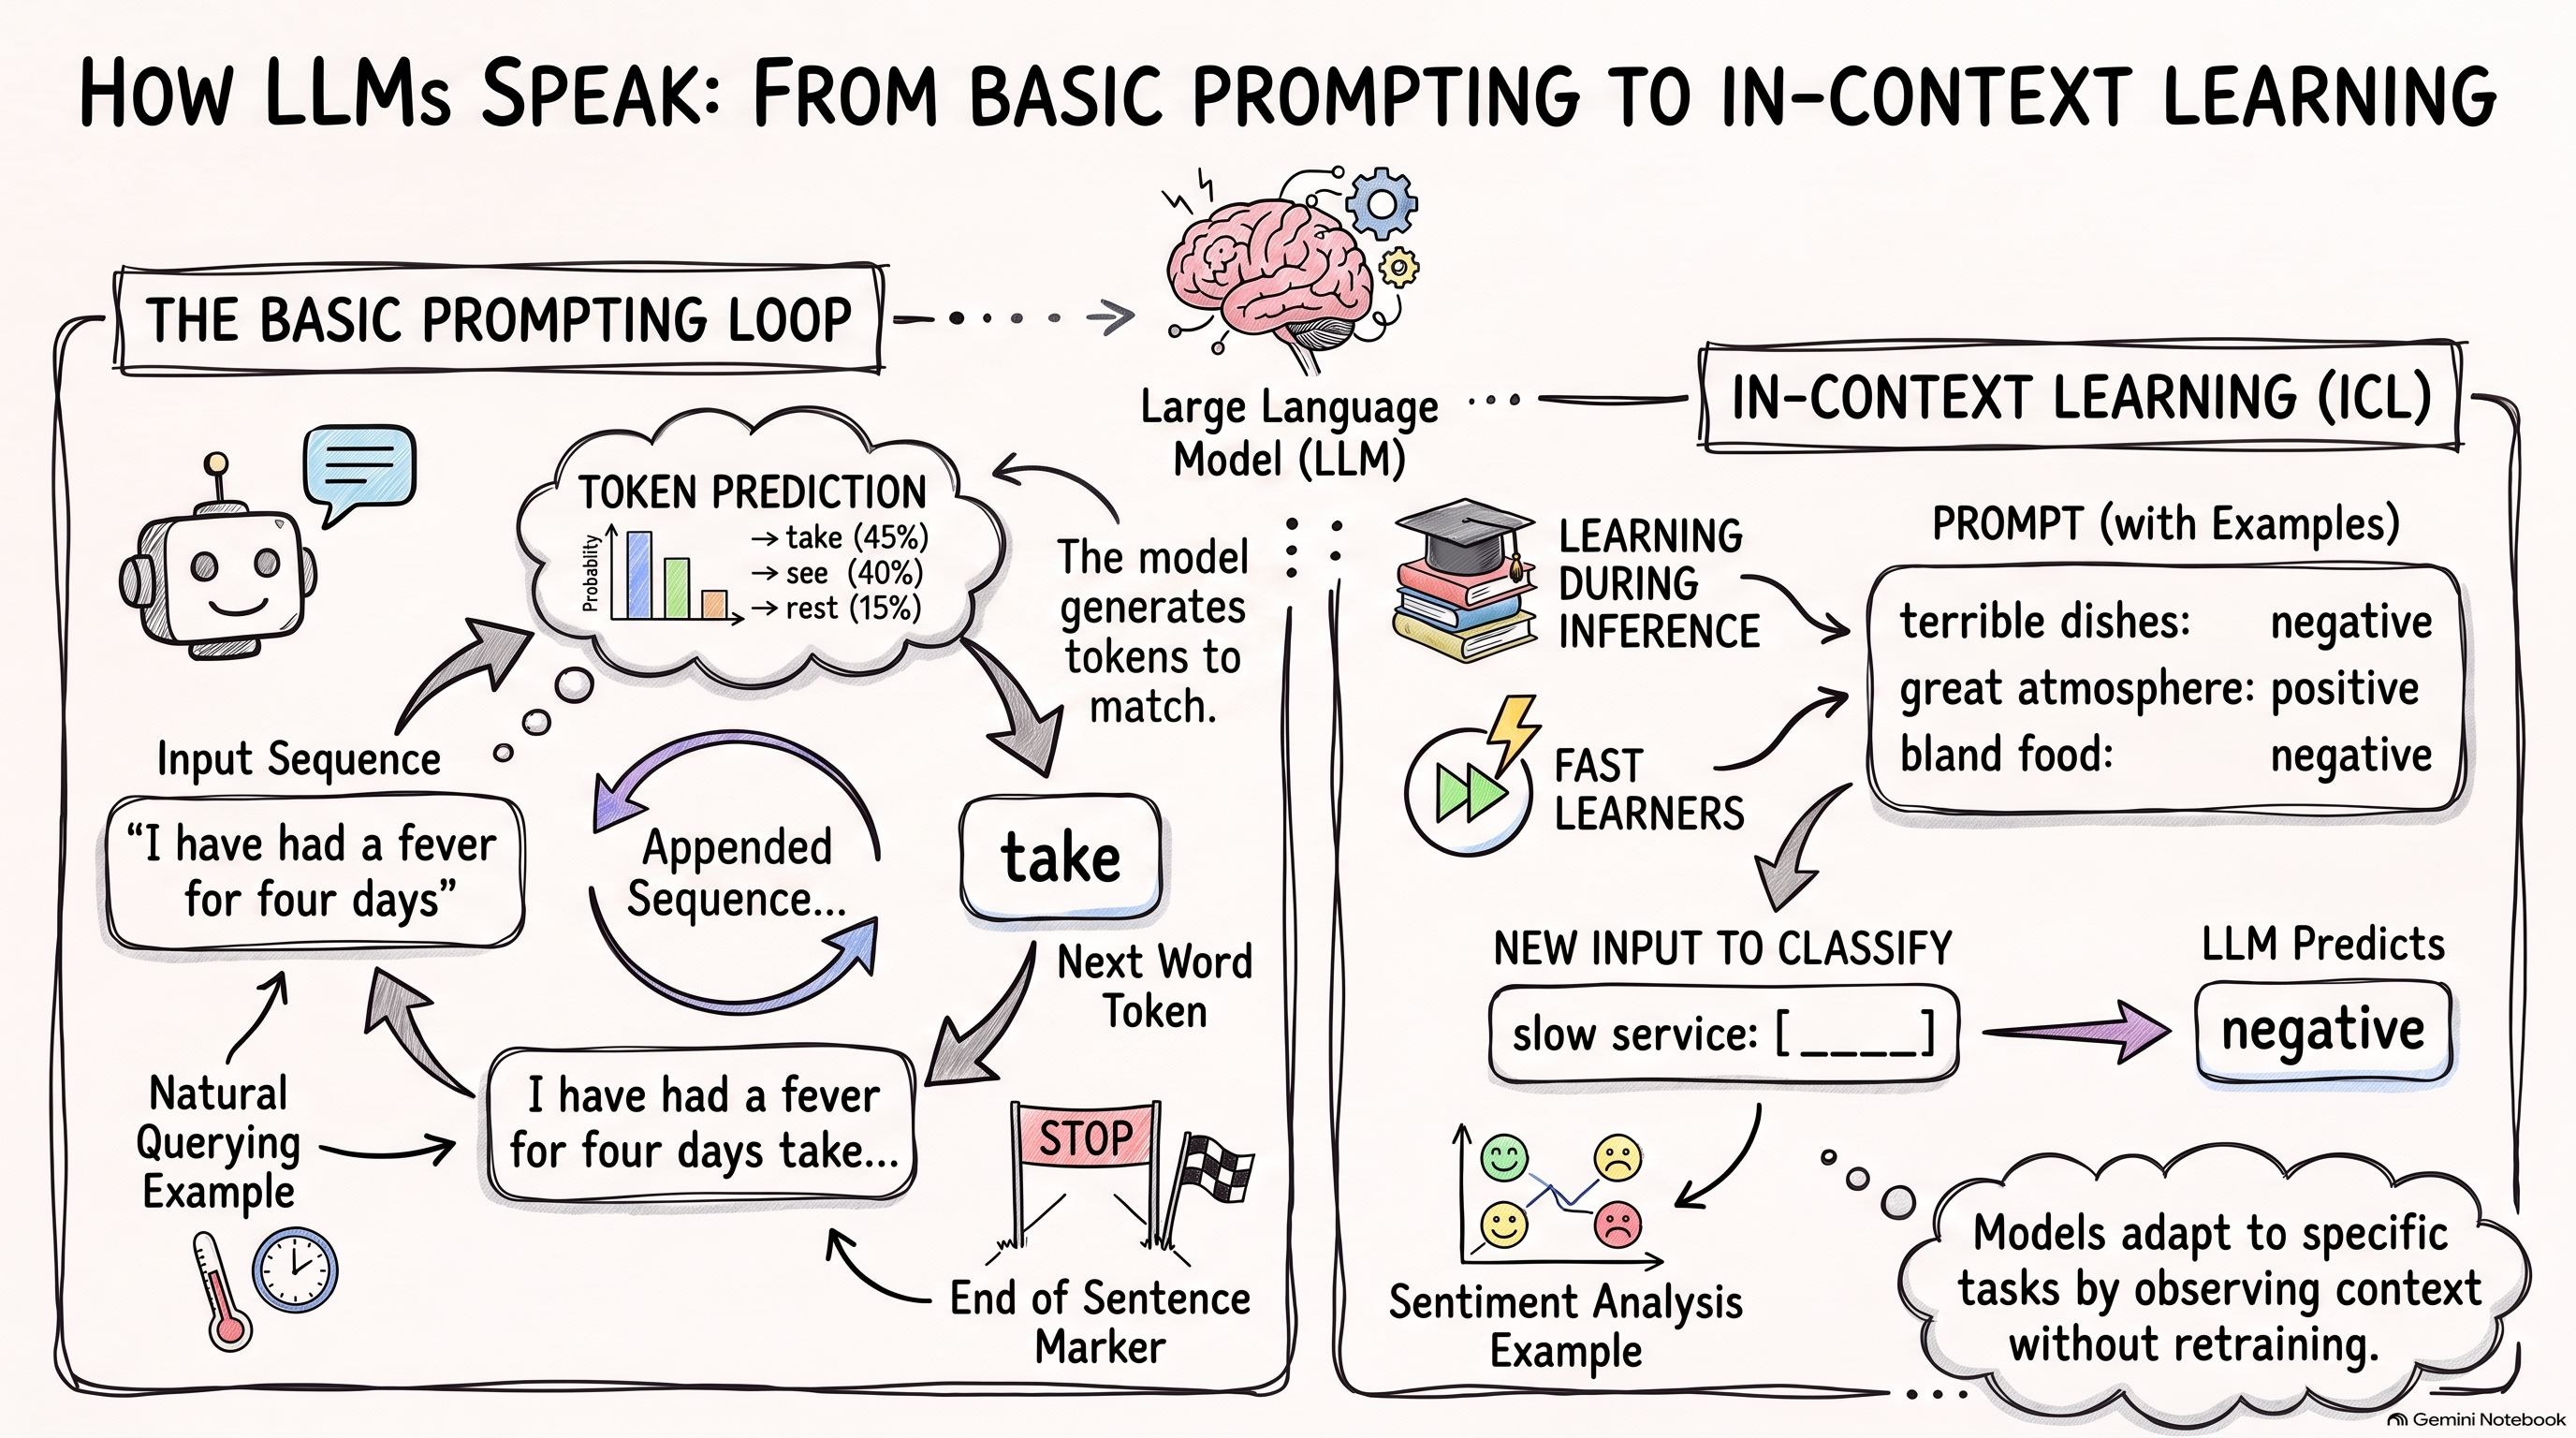
The basic way to use an LLM follows from what any language model computes. You give it a sequence of tokens, the prompt. It predicts the next token, appends it, predicts the next one, and continues until it produces an end-of-sequence token. Typing "I have been having a fever for four days, what should I do?" into ChatGPT does exactly this: the answer is generated one token at a time.
The prompt also sets the scope. A model trained on a huge range of text can go in many directions; telling it what we want, and in what form, narrows the space and usually improves the answer.
In-context learning (ICL) goes one step further: put a few solved examples in the prompt, then the new case. The model picks up the task from the examples.
| Prompt type | What the prompt contains |
|---|---|
| Regular prompt | The sentiment of the review "good meal" is |
| In-context learning | terrible dishes: negative / great atmosphere: positive / bland food: negative / slow service: ? |
The key point: no retraining, and no weights change. The model adapts while answering, from the context alone; once the prompt is gone, so is the "learning". This is why LLMs are called fast learners.
思维链:让模型写出步骤
推理是分析证据、组织论证、运用逻辑或概率得出结论的过程。早期的 LLM 不太擅长推理,而单纯把预训练做得更大,并不是提升推理能力的最好办法。思维链(chain-of-thought,CoT) 提示表明:只改提示、不做额外训练,就能引出一步一步的推理过程。
常见的有两种:
| 形式 | 在提示里加什么 | 出处 |
|---|---|---|
| 少样本思维链 | 示例里写出解题步骤,而不只是答案 | Wei 等,2022 |
| 零样本思维链 | 不给示例,只加一句 “Let's think step by step”(让我们一步一步地想) | Kojima 等,2022 |
课程里的应用题能看出差别。只给一个普通示例(Roger 有 5 个网球,又买了 2 罐、每罐 3 个,答案是 11),模型回答新的食堂问题时给出 27,答错了。示例里写出步骤(2 罐 × 3 = 6,5 + 6 = 11)之后,模型也为新问题写出自己的步骤,得到正确答案 9。另一个零样本例子是一道美国执业医师资格考试(USMLE)题:加上 “Let's think step by step” 后,模型先推理 HIV 感染的过程,再选出正确选项。
思维链在算术、常识和符号推理的多个基准上都提升了表现,它的成功也引发了大量关于 LLM 推理的研究。有两点要注意:这种提升主要出现在大模型上,规模仍然重要;写出来的步骤也可能有错,需要核对,不能直接相信。
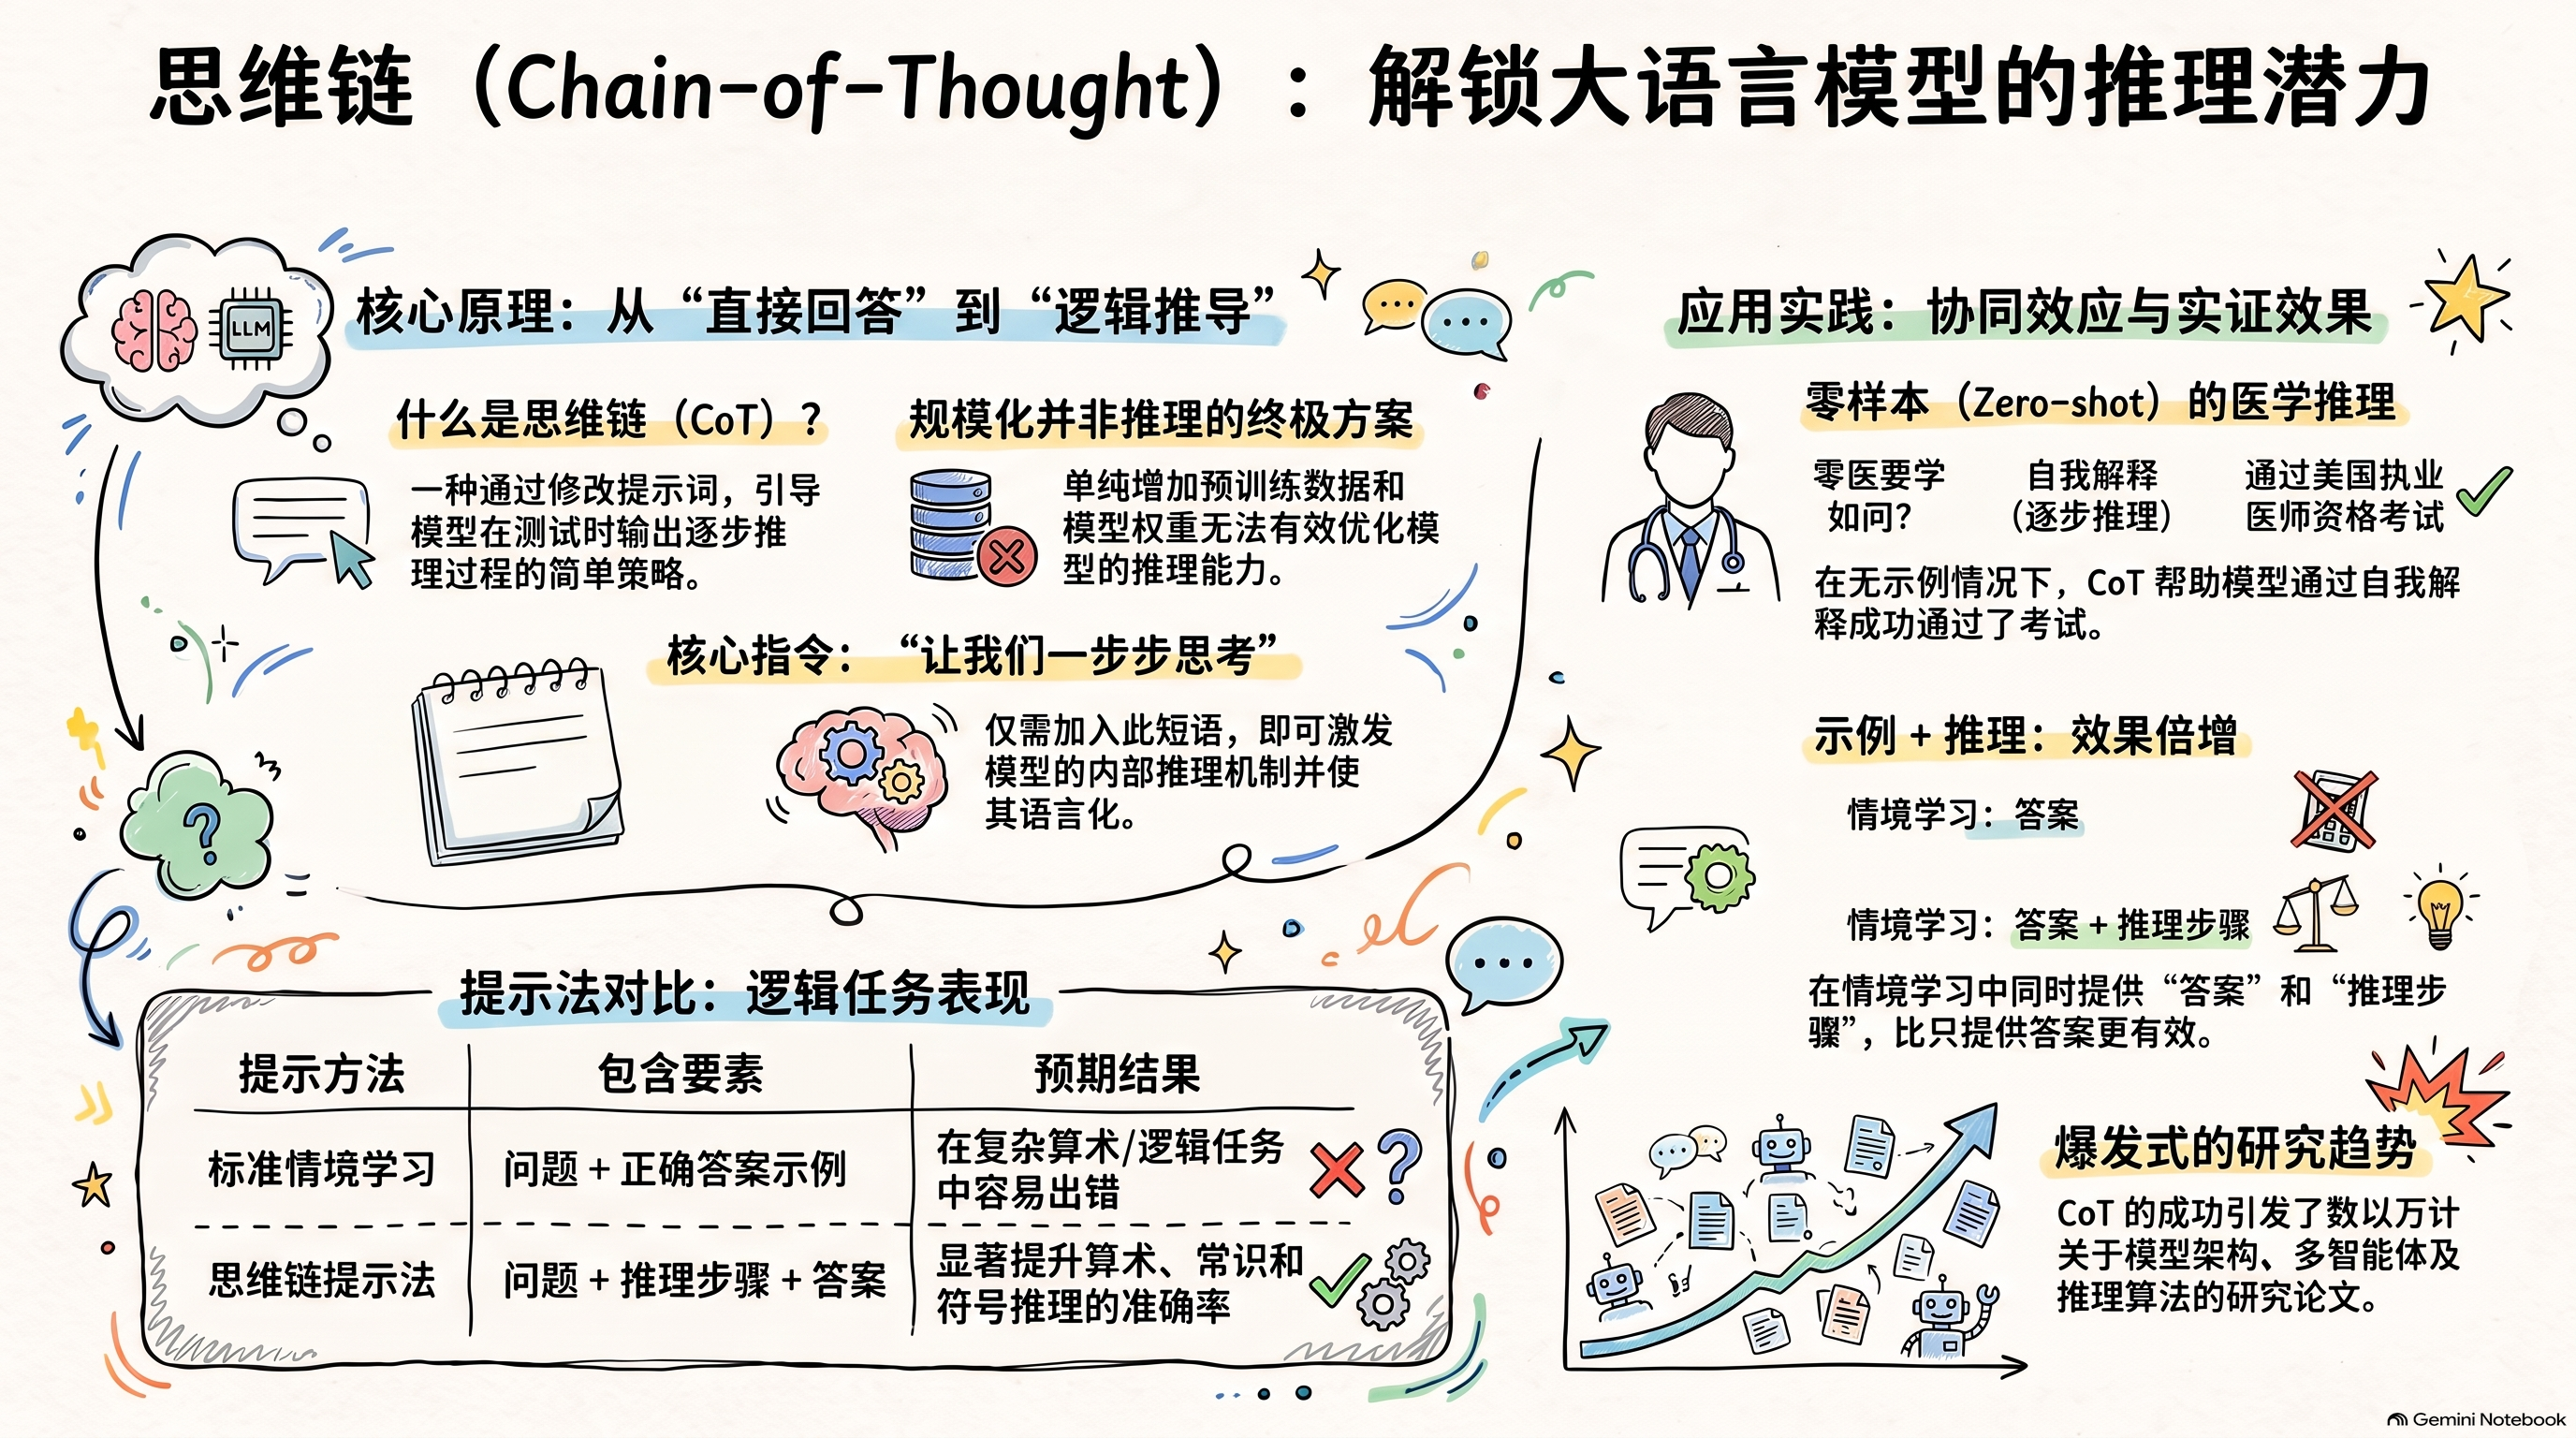
阅读提示:图中的“情境学习”就是上下文学习;右上角“零医要学 如何?”是生成时的乱码。课程的医学例子是模型答对了一道考试题,并不是“通过了考试”。“规模化并非推理的终极方案”指单纯扩大预训练不是提升推理的最好办法;思维链论文也发现,这种提升只在足够大的模型上才出现。
Chain-of-thought: asking for the steps
Reasoning means analysing evidence, building an argument and applying logic or probability to reach a conclusion. Early LLMs were weak at it, and simply making pre-training bigger was not the best way to improve it. Chain-of-thought (CoT) prompting showed that changing the prompt alone can draw out step-by-step reasoning, with no extra training.
There are two common forms:
| Form | What you add to the prompt | Source |
|---|---|---|
| Few-shot CoT | Examples that show the worked steps, not just the answer | Wei et al., 2022 |
| Zero-shot CoT | No examples; just the phrase "Let's think step by step" | Kojima et al., 2022 |
The course's word problem shows the difference. With a plain in-context example (Roger has 5 tennis balls and buys 2 cans of 3; answer: 11), the model answers a new cafeteria question with 27, which is wrong. When the example also shows the steps (2 cans × 3 = 6, 5 + 6 = 11), the model writes out its own steps for the new question and reaches the correct answer, 9. In a zero-shot example on a US Medical Licensing Examination question, "Let's think step by step" led the model to reason through how HIV infection works before choosing the correct option.
Chain-of-thought improves arithmetic, commonsense and symbolic reasoning across many benchmarks, and its success set off a large wave of research on LLM reasoning. Two cautions: the gains appear mainly in large models, so scale still matters, and a written chain of steps can still contain errors, so it needs checking rather than trusting.
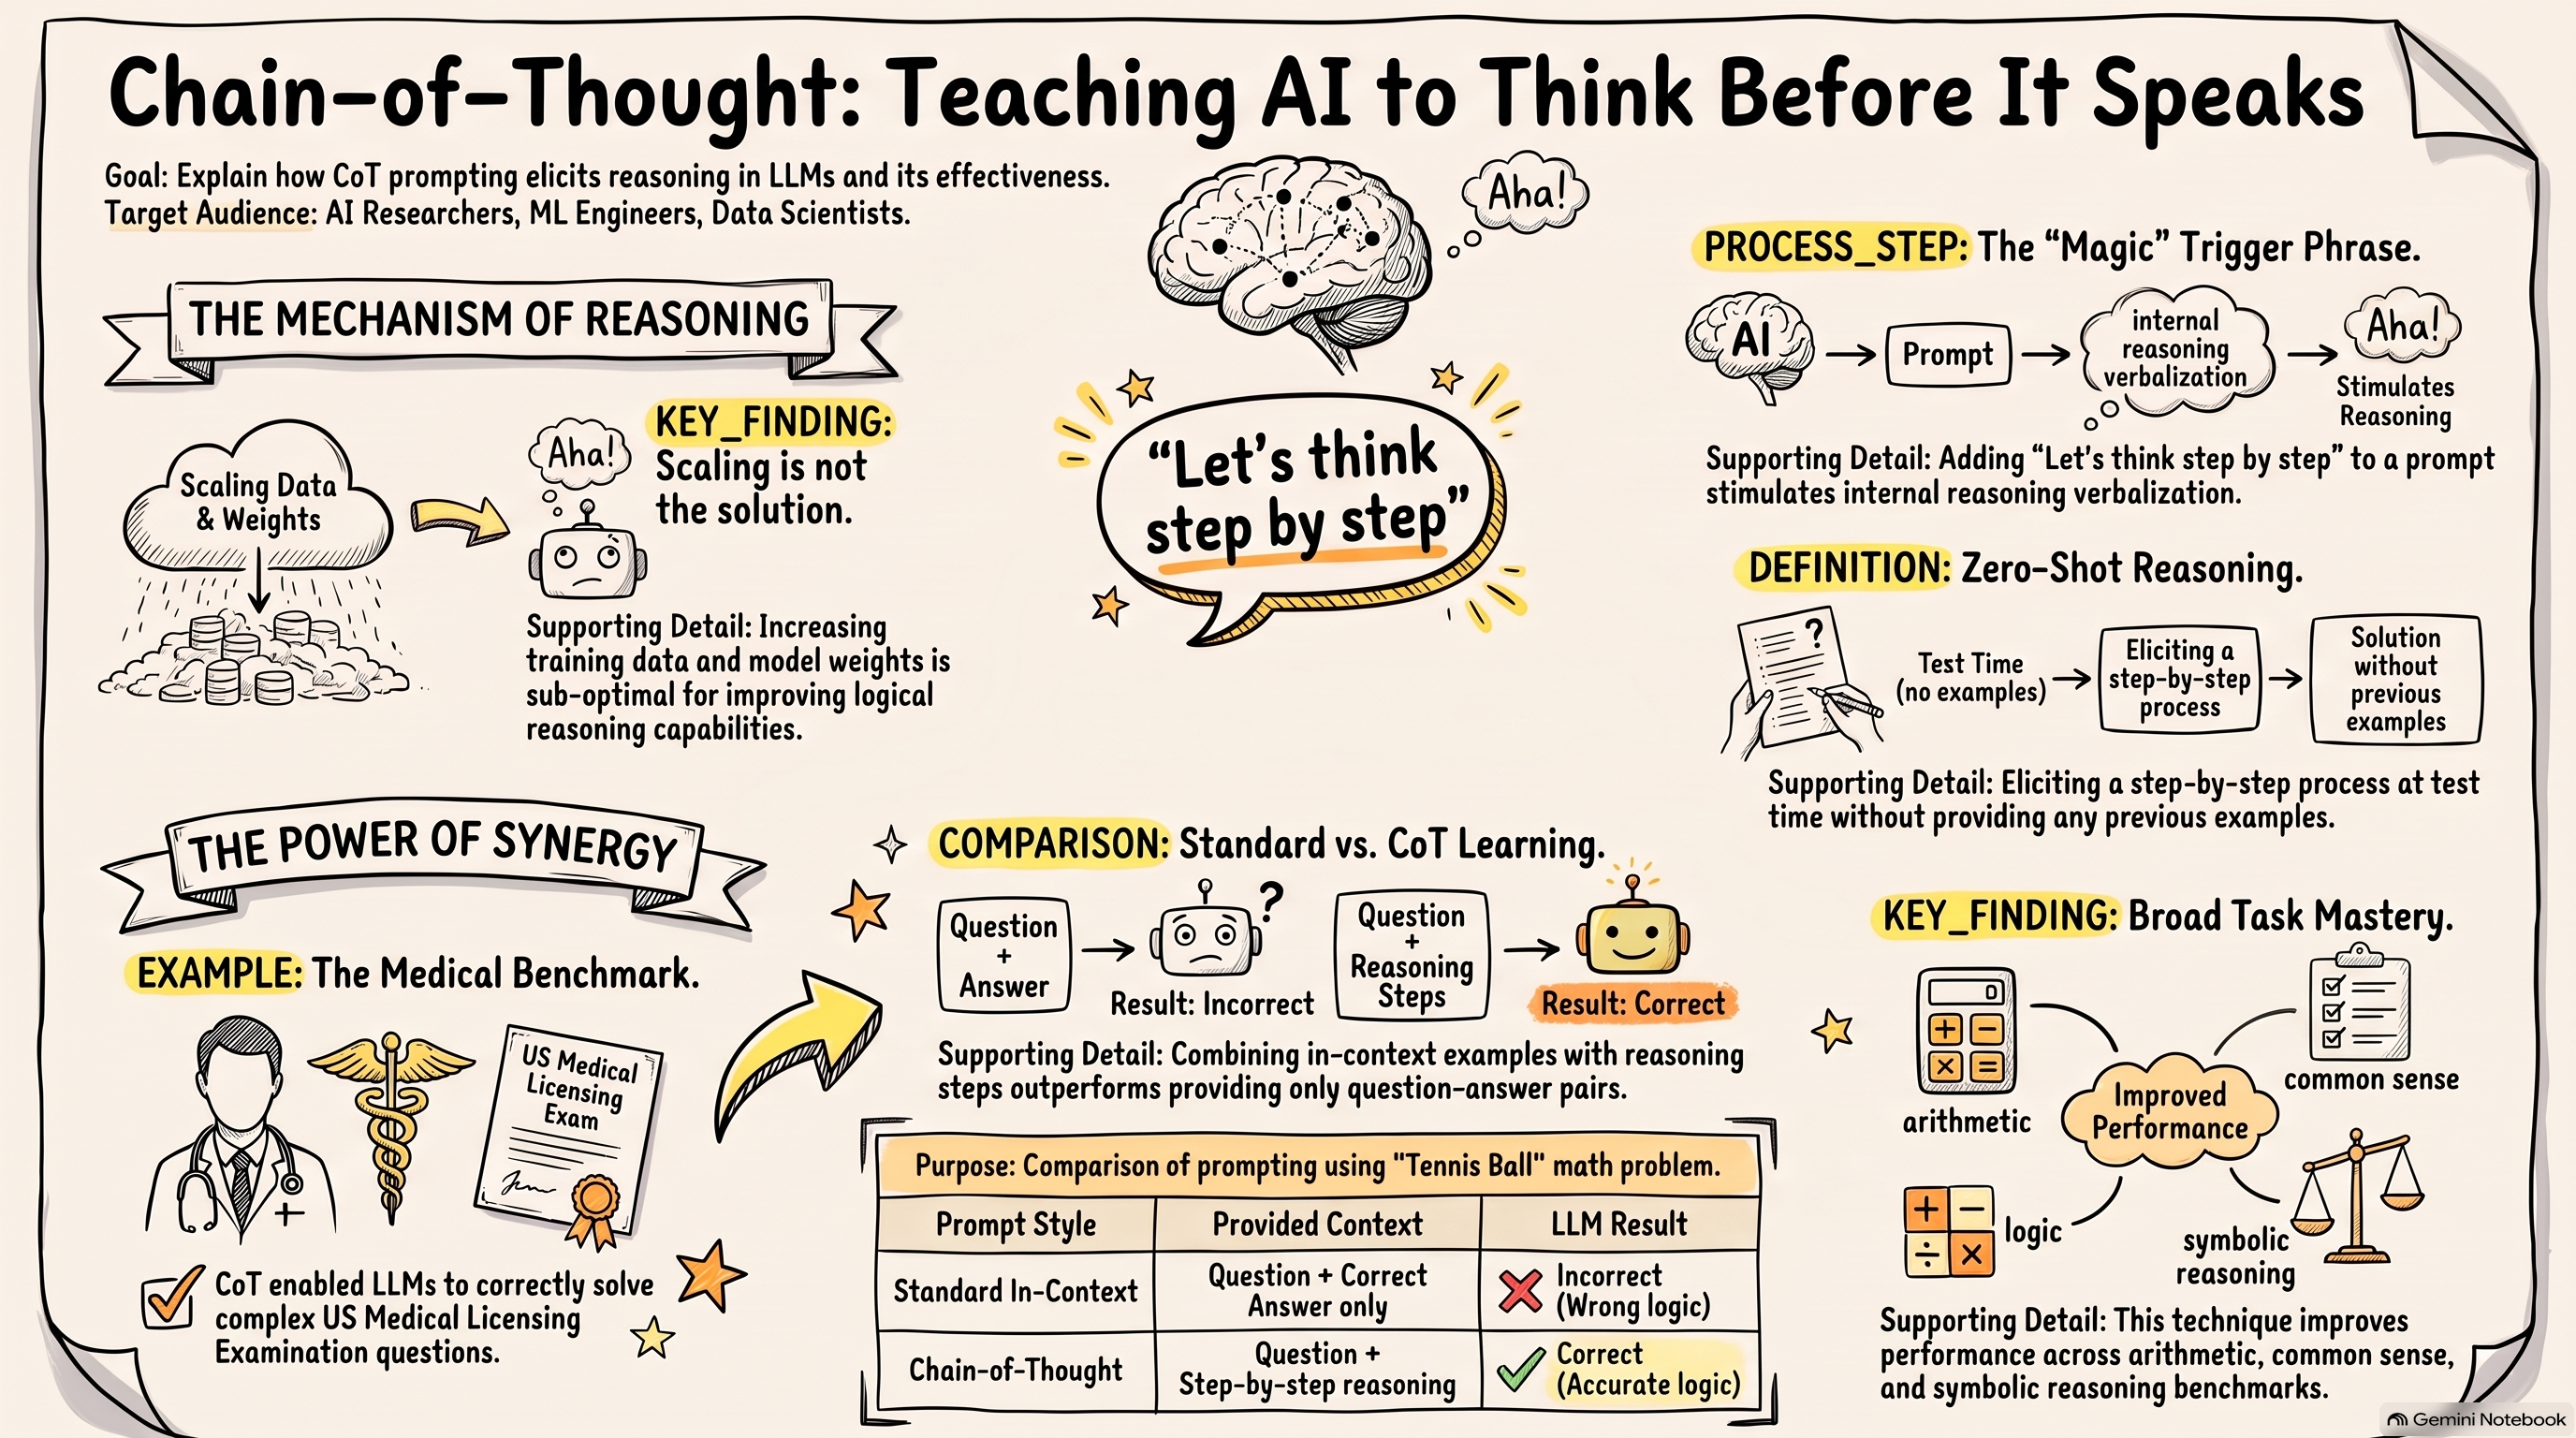
Reading note: the lines "Goal…" and "Target Audience…" at the top, and the labels KEY_FINDING, PROCESS_STEP and DEFINITION, are left over from the image's production brief, not content. "Scaling is not the solution" is too strong: the course says scaling pre-training is not the best way to improve reasoning, and the chain-of-thought paper found the benefit appears only in sufficiently large models. The medical example shows one exam question answered correctly, not a model passing the exam.
专门训练来推理的模型
思维链是靠提示把推理“引”出来。下一步,是直接把模型训练成会推理。课程的例子是 2025 年 1 月发布的 DeepSeek-R1。
| 我笔记里的特点 | 对 DeepSeek-R1 来说是什么意思 |
|---|---|
| 简化的推理结构 | 每次回答分两段:先是思考部分,再是答案;没有单独的反思或修改阶段 |
| 高效的学习算法 | 用 GRPO(组相对策略优化)做强化学习,省掉了其他方法要额外训练的“评论家”(critic)模型;奖励来自可以核对的答案,比如数学题的结果 |
| 专门训练来推理 | 它会自己先推理再回答,不需要再加 “let's think step by step” |
它的权重是开放的。总共有 6,710 亿个权重,但每个 token 只用到其中 370 亿个,所以运行成本比总规模看上去低;课程里说的“370 亿”指的就是这部分。常被引用的“约 600 万美元训练成本”只算了它的基础模型 DeepSeek-V3 最后一次正式训练,课程也提到这个数字受到了质疑。训练过程中,模型开始在思考部分里回头检查、修改自己的步骤,作者认为这是强化学习中自然出现的行为,而不是人为写进去的。我在描述思维链时想到的“自己发现问题、自己校正”,严格来说属于这类推理模型。
课程还列出了这类模型的几个未解之谜:训练细节只公开了一部分;小模型可能依赖从大模型蒸馏;基准测试的成绩可能因为数据污染而偏高。
Models trained to reason
Chain-of-thought gets reasoning out of a model by prompting. The next step was to train models to reason. The course's example is DeepSeek-R1, released in January 2025.
| Feature in my notes | What it means for DeepSeek-R1 |
|---|---|
| Simplified reasoning structure | Each answer has two parts: a thinking section, then the answer. There is no separate reflection or revision stage. |
| Efficient learning algorithm | Reinforcement learning with GRPO (group relative policy optimization), which drops the extra "critic" model that other methods train alongside. Rewards come from checkable answers, such as maths results. |
| Trained explicitly to reason | It reasons before answering on its own, so no "let's think step by step" is needed. |
Its weights are open. It has 671 billion weights in total, but only 37 billion are active for each token, so it is cheaper to run than its total size suggests; the course's "37 billion" refers to this active part. The widely quoted training cost of about 6 million US dollars covers only the final training run of its base model (DeepSeek-V3), and the course notes that such estimates have been questioned. During training, the model started to re-check and revise its own steps inside its thinking section, a behaviour the authors describe as emerging from reinforcement learning rather than being programmed. That is the self-correction I had in mind when I described chain-of-thought; strictly, it belongs to reasoning models like this one.
The course also lists open questions about such models: training details are only partly published; smaller models may depend on distilling bigger ones; and benchmark results may be inflated by data contamination.
两个挑战:数据污染与幻觉
| 挑战 | 是什么 | 为什么重要 |
|---|---|---|
| 数据污染(data contamination) | 基准测试的题目或答案,出现在了模型的训练数据里 | 分数虚高:模型可能只是“背过题”,真实场景里的表现会比报告的低 |
| 幻觉(hallucination) | 输出读起来流畅、自信,内容却是错的、没有依据的或前后矛盾的 | 在医疗场景里,自信的错误答案很危险,输出需要对照来源核实 |
这两个问题都容易被忽略,因为模型写出来的文字看起来没毛病。数据污染在整个机器学习里都存在,但对 LLM 更严重:它的训练数据几乎覆盖整个网络,公开的基准题很容易混进去。另一个问题是训练数据质量差或有偏差,也会导致错误或有偏向的回答。下一讲会进一步讨论幻觉、信息过时、训练数据和偏见。
Two challenges: data contamination and hallucination
| Challenge | What it is | Why it matters |
|---|---|---|
| Data contamination | Benchmark test questions, or their answers, were part of the model's training data | Scores are inflated: the model may have memorized the test, so real-world performance can be lower than reported |
| Hallucination | Output that sounds fluent and confident but is false, unsupported or inconsistent | In health settings a confident wrong answer is risky, so outputs need checking against sources |
Both are easy to miss because the model's text looks fine. Contamination is a problem in all of machine learning, but more serious for LLMs, which are trained on so much of the web that public benchmarks are easily included. A separate issue is poor-quality or biased training data, which can also lead to wrong or skewed answers. The next lecture covers hallucination, stale information, training data and bias in more detail.
我的思考
LLM 是在神经语言模型的基础上进化来的。第一个大的进化,是从单词变成 token。前面介绍语言模型时,我们一直说“词”,因为我们是从自己学习语言的经验出发的,平时用的就是一个个单词。但在教机器学习语言时,我们会把句子拆开,也会把单词拆开,比如拆成词根和词缀;拆解之后,再建立它们之间的联系。这是前面几期学过的内容。现在的大语言模型本质上也是神经语言模型,它同样建立在这个最早的基础概念上,也就是分词。这里再回顾一下:token 不一定是一个完整的单词,可以是一个短语一样的片段,也可以是单词的一部分。这样切分,一来机器学得更有效率,二来能用更长的语境,预测得更准。
第二个进化是对上下文的理解:不再只看一个词静态的意思,而是根据上下文分析这个词在当前语境下代表什么。这里要特别提到注意力机制,它是改进 LLM 时特别重要、具有里程碑意义的机制:通过计算 token 之间的相互影响并加权,影响最后的输出。其实说到底,又回到了很基础的一点:之前我们学的是词和词、句子和句子之间的关系,现在是用一些机制去处理 token 和 token 之间的关系。
提示词工程,就是我在和大语言模型交互时给它一些提示。大语言模型是基于非常广泛的信息建立起来的,怎样让这些信息更精确?给它限定一个范围,或者告诉它我们想做什么,它就能给出更好的回答。这个过程并不是重新训练模型,而是给它划定范围、给出明确的指示。指示越细,它越能从中看出要完成什么样的任务,也就越能适应这个任务。
有时候模型的回答还是不够好。于是开发人员让它在回答时做一个拆解:展示出自己是怎样推理、怎样得出答案的,就像我们解题一样一步一步来。把每一步都写出来,能让最后的答案更准确。专门训练来推理的模型更进一步,还会在展示步骤时发现自己的逻辑问题并加以校正。
现在仍有一些常见的挑战,比如数据污染和幻觉,这里先不展开,留到下一期。至于模型家族,现阶段知道 GPT 和 Llama 是最常见的两类、它们在权重是否开放等方面有区别,就够用了。
My thoughts
An LLM builds on the neural language model and evolves it. The first big step is from words to tokens. In the earlier notes on language models we kept saying "words", because we started from how we ourselves learn language, and in daily life we use whole words. But to teach a machine language, we break sentences apart, and break words apart too, for example into roots and affixes; then we build connections between the pieces. That is what the earlier notes covered. A large language model is still a neural language model, and it rests on that same early idea: tokenization. As a quick recap, a token doesn't have to be a whole word; it can be a phrase-like chunk or part of a word. Splitting text this way makes learning more efficient, and it lets the model use a longer context and predict more precisely.
The second step is understanding context. A word no longer has one fixed meaning; the model works out what it means in this particular context. The attention mechanism is the milestone here: it calculates how much tokens influence each other and weights them accordingly, which shapes the output. In the end, it comes back to the same basic point as the earlier notes. We first learned relationships between words and between sentences; now the model uses mechanisms to handle the relationships between tokens.
Prompting means giving the model instructions when I interact with it. The model was built from a very broad range of information; a prompt makes that information more precise by setting a scope and saying what I want. This does not retrain the model. The more detailed the instructions, the more the model can tell what kind of task it is facing, and the better it adapts.
Sometimes the answers are still not good enough. So developers ask the model to break its answer down and show how it reasoned, step by step, the way we solve a problem. Writing out each step makes the final answer more accurate. Models trained to reason go further, noticing problems in their own steps and correcting them.
Common challenges remain, such as data contamination and hallucination; I will leave them for the next note. For model families, it is enough for now to know that GPT and Llama are two of the most common, and that they differ in things such as whether their weights are open.
手写原稿
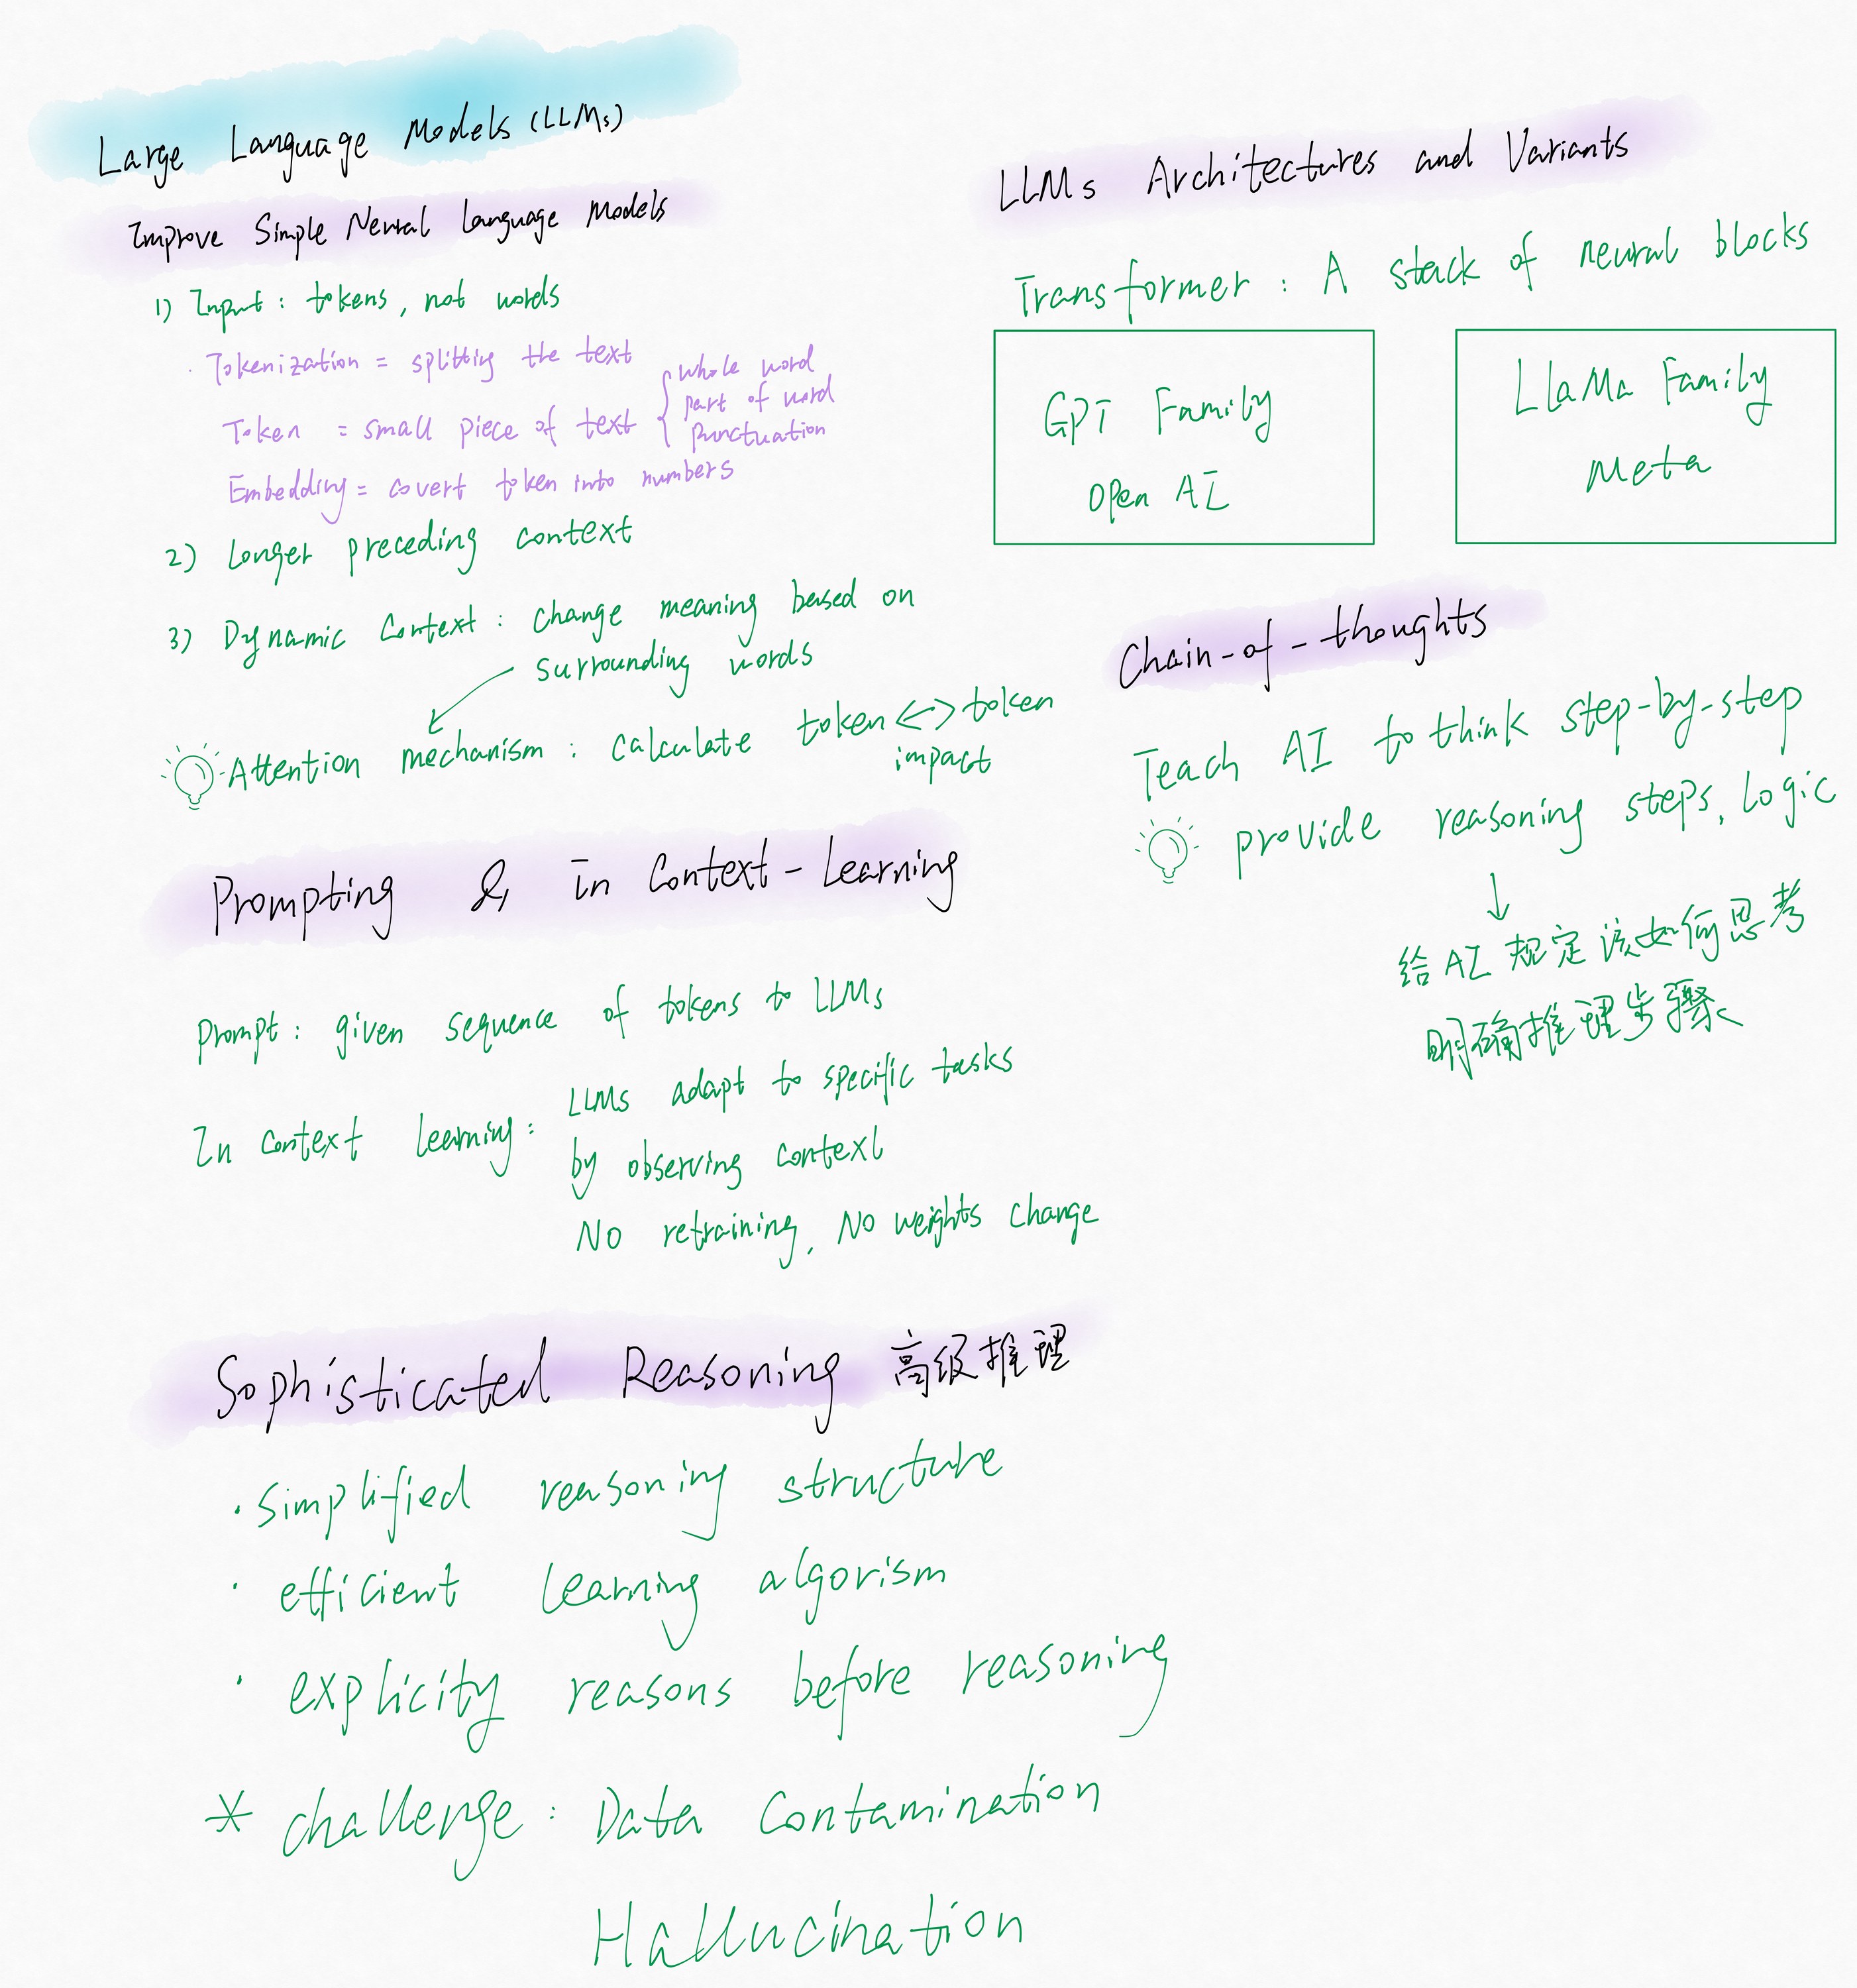
整理后的版本改了这些地方:拼写 covert 改为 convert、algorism 改为 algorithm;Chain-of-thoughts 改为 Chain-of-Thought;LlaMa 统一写作 Llama,并补上两个家族的开放程度(GPT 多为闭源权重,Llama 开放权重);“explicity reasons before reasoning” 改为“专门训练:回答之前先显式推理”;“高级推理”一块标明了例子 DeepSeek-R1;数据污染改为“测试题混进了训练数据”,并补上幻觉的定义;更长前文、注意力和上下文学习各补了一个短例子。
Original handwritten notes
What changed in the tidied version: "covert" is now convert and "algorism" is algorithm; Chain-of-thoughts is now chain-of-thought; LlaMa is written Llama, with each family's openness added (GPT mostly closed weights, Llama open weights); "explicity reasons before reasoning" now says the model is trained to reason before it answers; the Sophisticated Reasoning block names its example, DeepSeek-R1; data contamination is defined as test questions leaking into training data, with hallucination defined next to it; and the context, attention and in-context learning lines each gained a short example.
学习来源与资源
本文基于我在英属哥伦比亚大学(UBC)微证书项目“Natural Language Processing to Improve Patient Care”中,“Overview of NLP and Large Language Models”课程(Giuseppe Carenini 主讲的 Large Language Models 一讲)的学习笔记。技术细节核对了以下资料:
- Jurafsky 与 Martin,《Speech and Language Processing》第 3 版草稿:第 7 章 Transformers and Pretraining。
- Vaswani 等(2017),Attention Is All You Need。
- Brown 等(2020),Language Models are Few-Shot Learners(GPT-3 与上下文学习)。
- Wei 等(2022),Chain-of-Thought Prompting Elicits Reasoning in Large Language Models;Kojima 等(2022),Large Language Models are Zero-Shot Reasoners。
- DeepSeek-AI(2025),DeepSeek-R1 与 DeepSeek-V3 技术报告。
- Meta,Llama 3.1 许可协议;OpenAI,gpt-oss-120b 模型卡。
动手试一试
- Tiktokenizer:粘贴任意句子,看 GPT 的分词器怎样把它切成 token、一共多少个。可以试试 unhappy、一个药名,或者一句中文。
- Transformer Explainer:在浏览器里运行一个小型 GPT-2,输入提示,观察注意力和下一个 token 的概率。
- The Illustrated Transformer:Jay Alammar 用图一步步讲解注意力和 Transformer 的各个块(英文)。
Learning sources and resources
This note is based on my study notes from the University of British Columbia (UBC) micro-certificate program "Natural Language Processing to Improve Patient Care," in the course "Overview of NLP and Large Language Models" (the Large Language Models lecture by Giuseppe Carenini). Technical details were checked against:
- Jurafsky and Martin, Speech and Language Processing (3rd edition draft): Chapter 7, Transformers and Pretraining.
- Vaswani et al. (2017), Attention Is All You Need.
- Brown et al. (2020), Language Models are Few-Shot Learners (GPT-3, in-context learning).
- Wei et al. (2022), Chain-of-Thought Prompting Elicits Reasoning in Large Language Models; Kojima et al. (2022), Large Language Models are Zero-Shot Reasoners.
- DeepSeek-AI (2025), DeepSeek-R1 and the DeepSeek-V3 technical report.
- Meta, Llama 3.1 license; OpenAI, gpt-oss-120b model card.
Try it yourself
- Tiktokenizer: paste any sentence and see how a GPT tokenizer splits it into tokens, with the token count. Try unhappy, a drug name, or a sentence in Chinese.
- Transformer Explainer: runs a small GPT-2 in your browser; type a prompt and watch the attention and the next-token probabilities.
- The Illustrated Transformer: Jay Alammar's step-by-step visual walk-through of attention and the Transformer blocks.