
NLP Learning Notes / NLP002
Basic Text Processing: From Word Structure to Pattern Matching
Natural language processing (NLP) begins with a practical problem: how can continuous, varied text become material we can analyze? Word structure, text patterns, and normalization offer a starting point. They help computers process text, but do not by themselves amount to understanding everything it means.
- section
- key term
- reading note
 ELLE · READING COMPANION
Take a moment to connect the ideas
A few foundations, with Elle
Tap a concept to explore it, then try three short questions. You can change any answer.
Morpheme and token
A morpheme carries meaning or grammar: cats contains cat and -s. A token is a unit chosen by a tokenizer, and need not be a morpheme.
Stemming and lemmatization
Stemming rewrites forms using rules and may produce a nonword. Lemmatization uses lexical and morphological information to find a base form.
Regex and meaning
Regex finds text patterns. Matching pain alone cannot distinguish I have pain from I have no pain.
Corpus and vocabulary
A corpus is a collection of texts. A vocabulary contains distinct items produced under chosen tokenization and normalization rules.
The big picture
Start with text patterns on the left and word structure on the right. Compare the two word-form methods in the middle, then follow the bottom row from a corpus to a vocabulary under chosen rules.
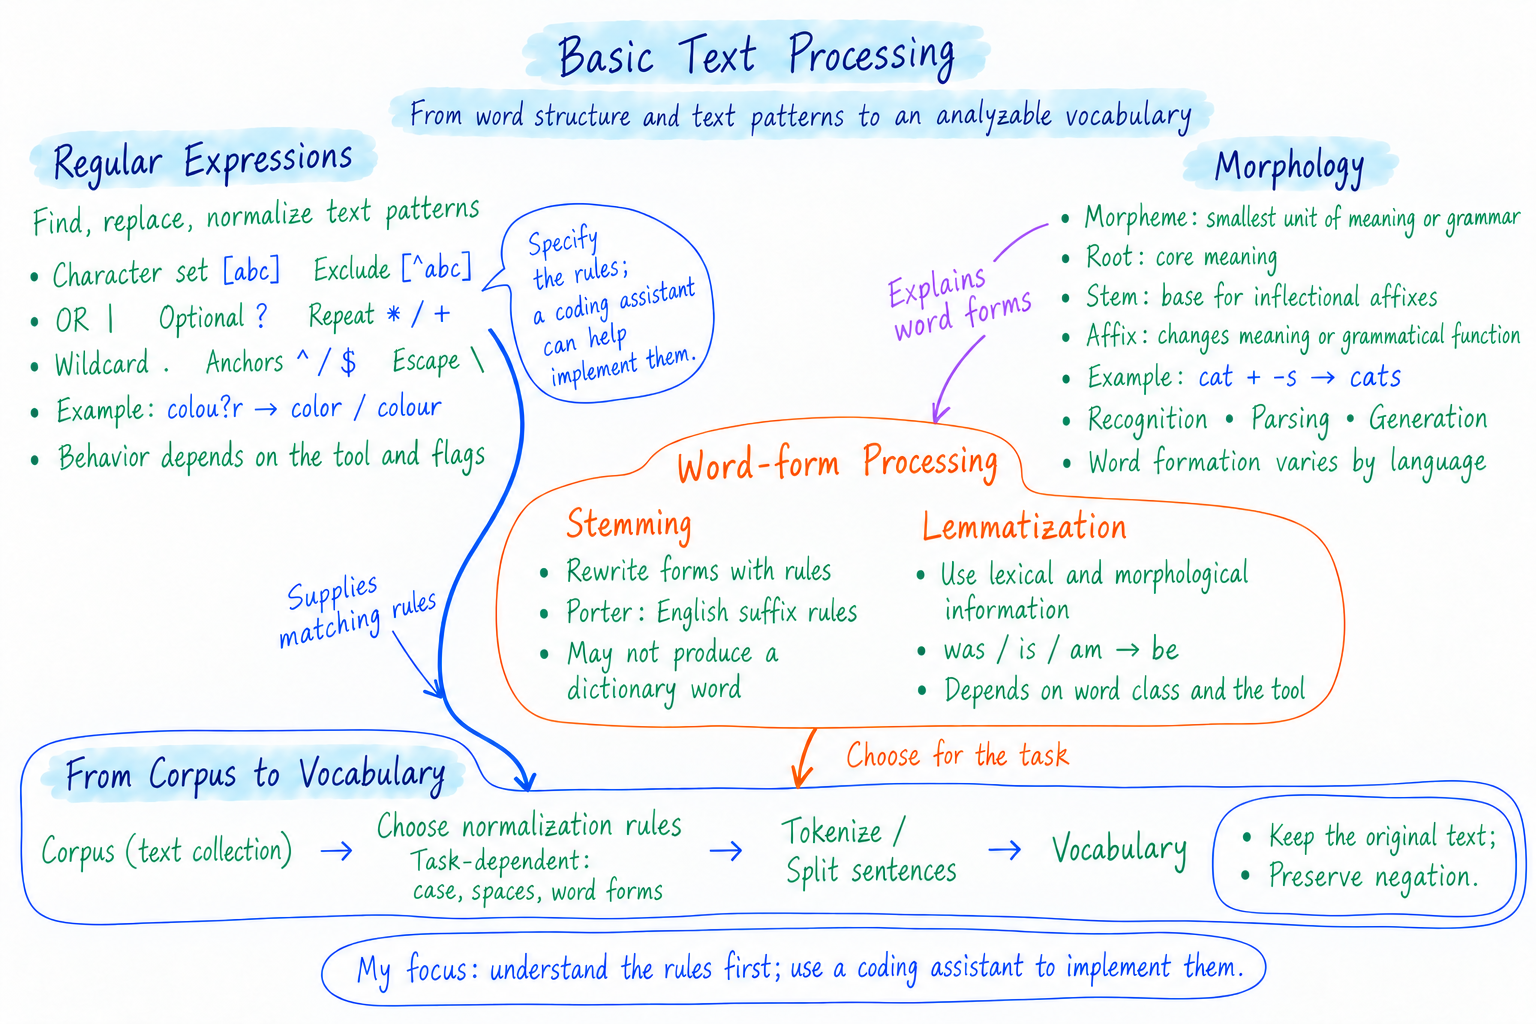
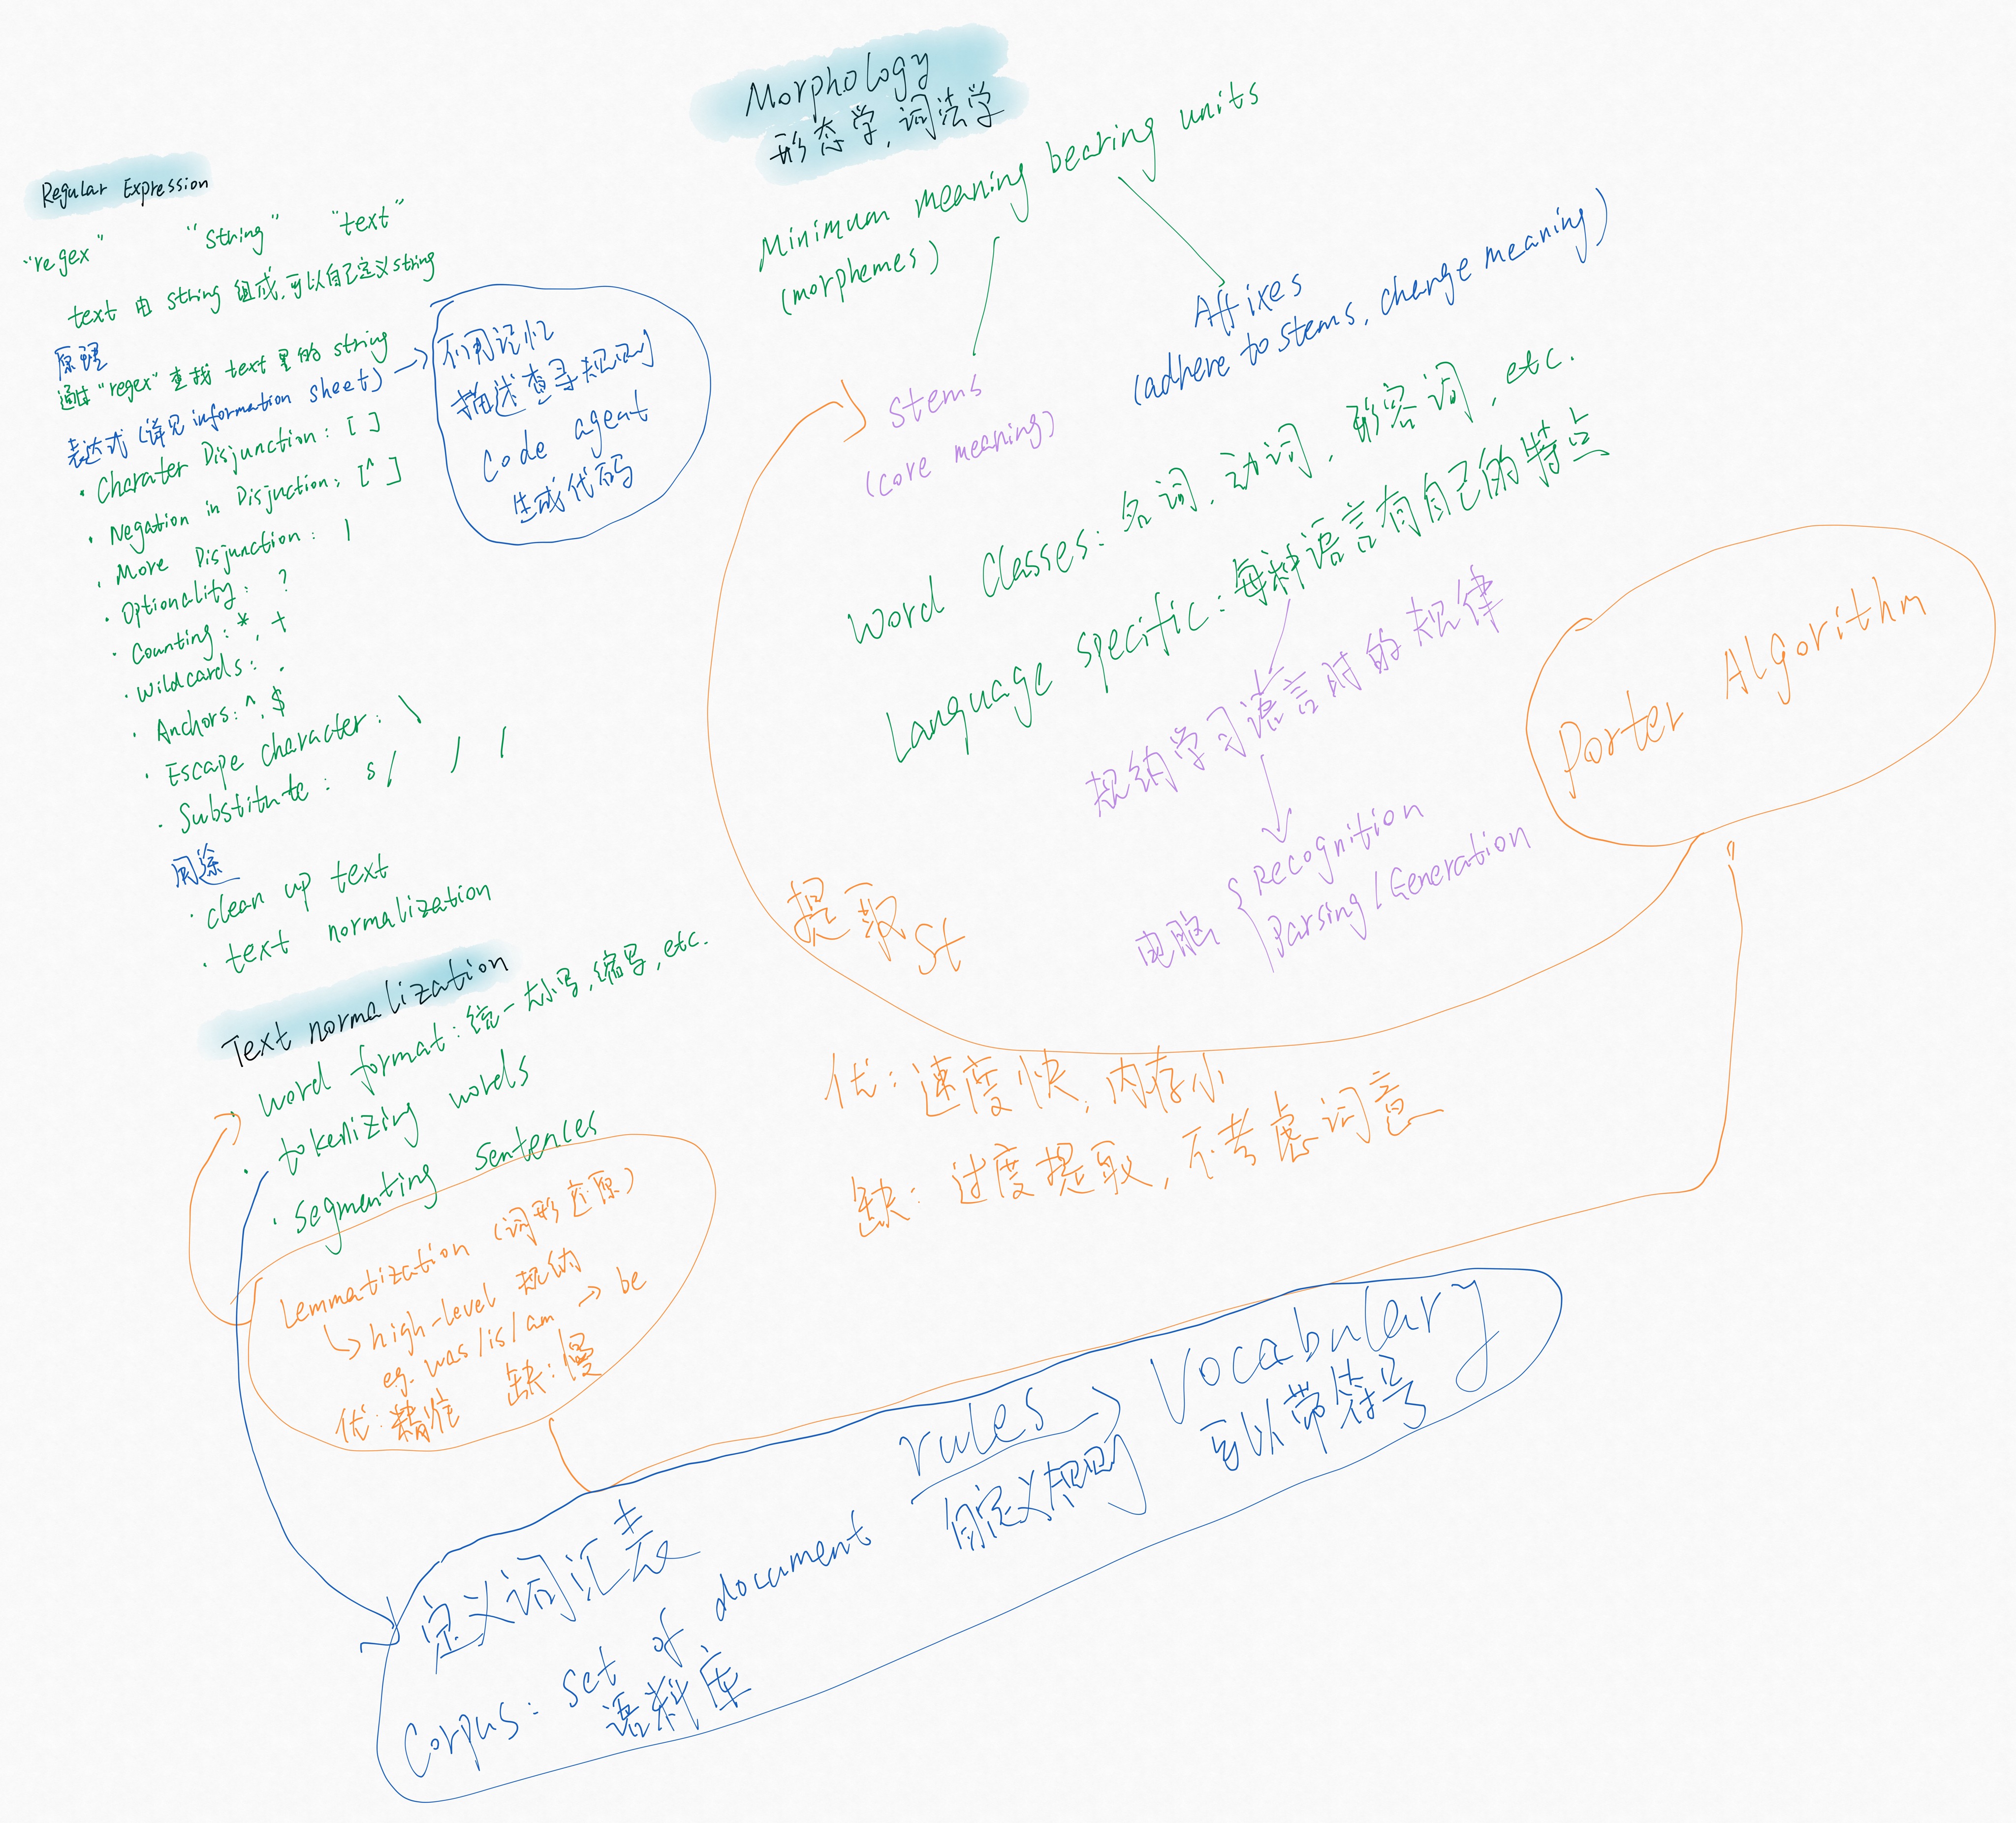
Tidied up from my handwritten page; arrows show links between ideas, not a fixed sequence of steps.
Tap a region to jump to that part of the note; use ⤢ Enlarge to see the full picture.
From word structure to context
When learning a language, we notice how words form, how sentences fit together, and what a speaker intends. These questions also provide a useful map for approaching NLP.
| Level | Question | Example |
|---|---|---|
| Morphology | How are words built internally? | walk plus -ed becomes walked |
| Syntax | How do words form phrases and sentences? | The subject and predicate in The cat sat on the mat. |
| Semantics | What do words and sentences mean? | Who did what, and what was involved? |
| Pragmatics | What is the speaker trying to do here? | “Can you pass the salt?” is usually a request |
| Discourse | How do sentences connect? | Which previously mentioned person does “she” refer to? |
Natural language understanding (NLU) concerns interpreting language; natural language generation (NLG) concerns producing it. Moving from words toward meaning, or from an intention toward an expression, is a useful introductory picture. It is not a fixed pipeline followed by every system, nor evidence that computers learn language in the same way people do.
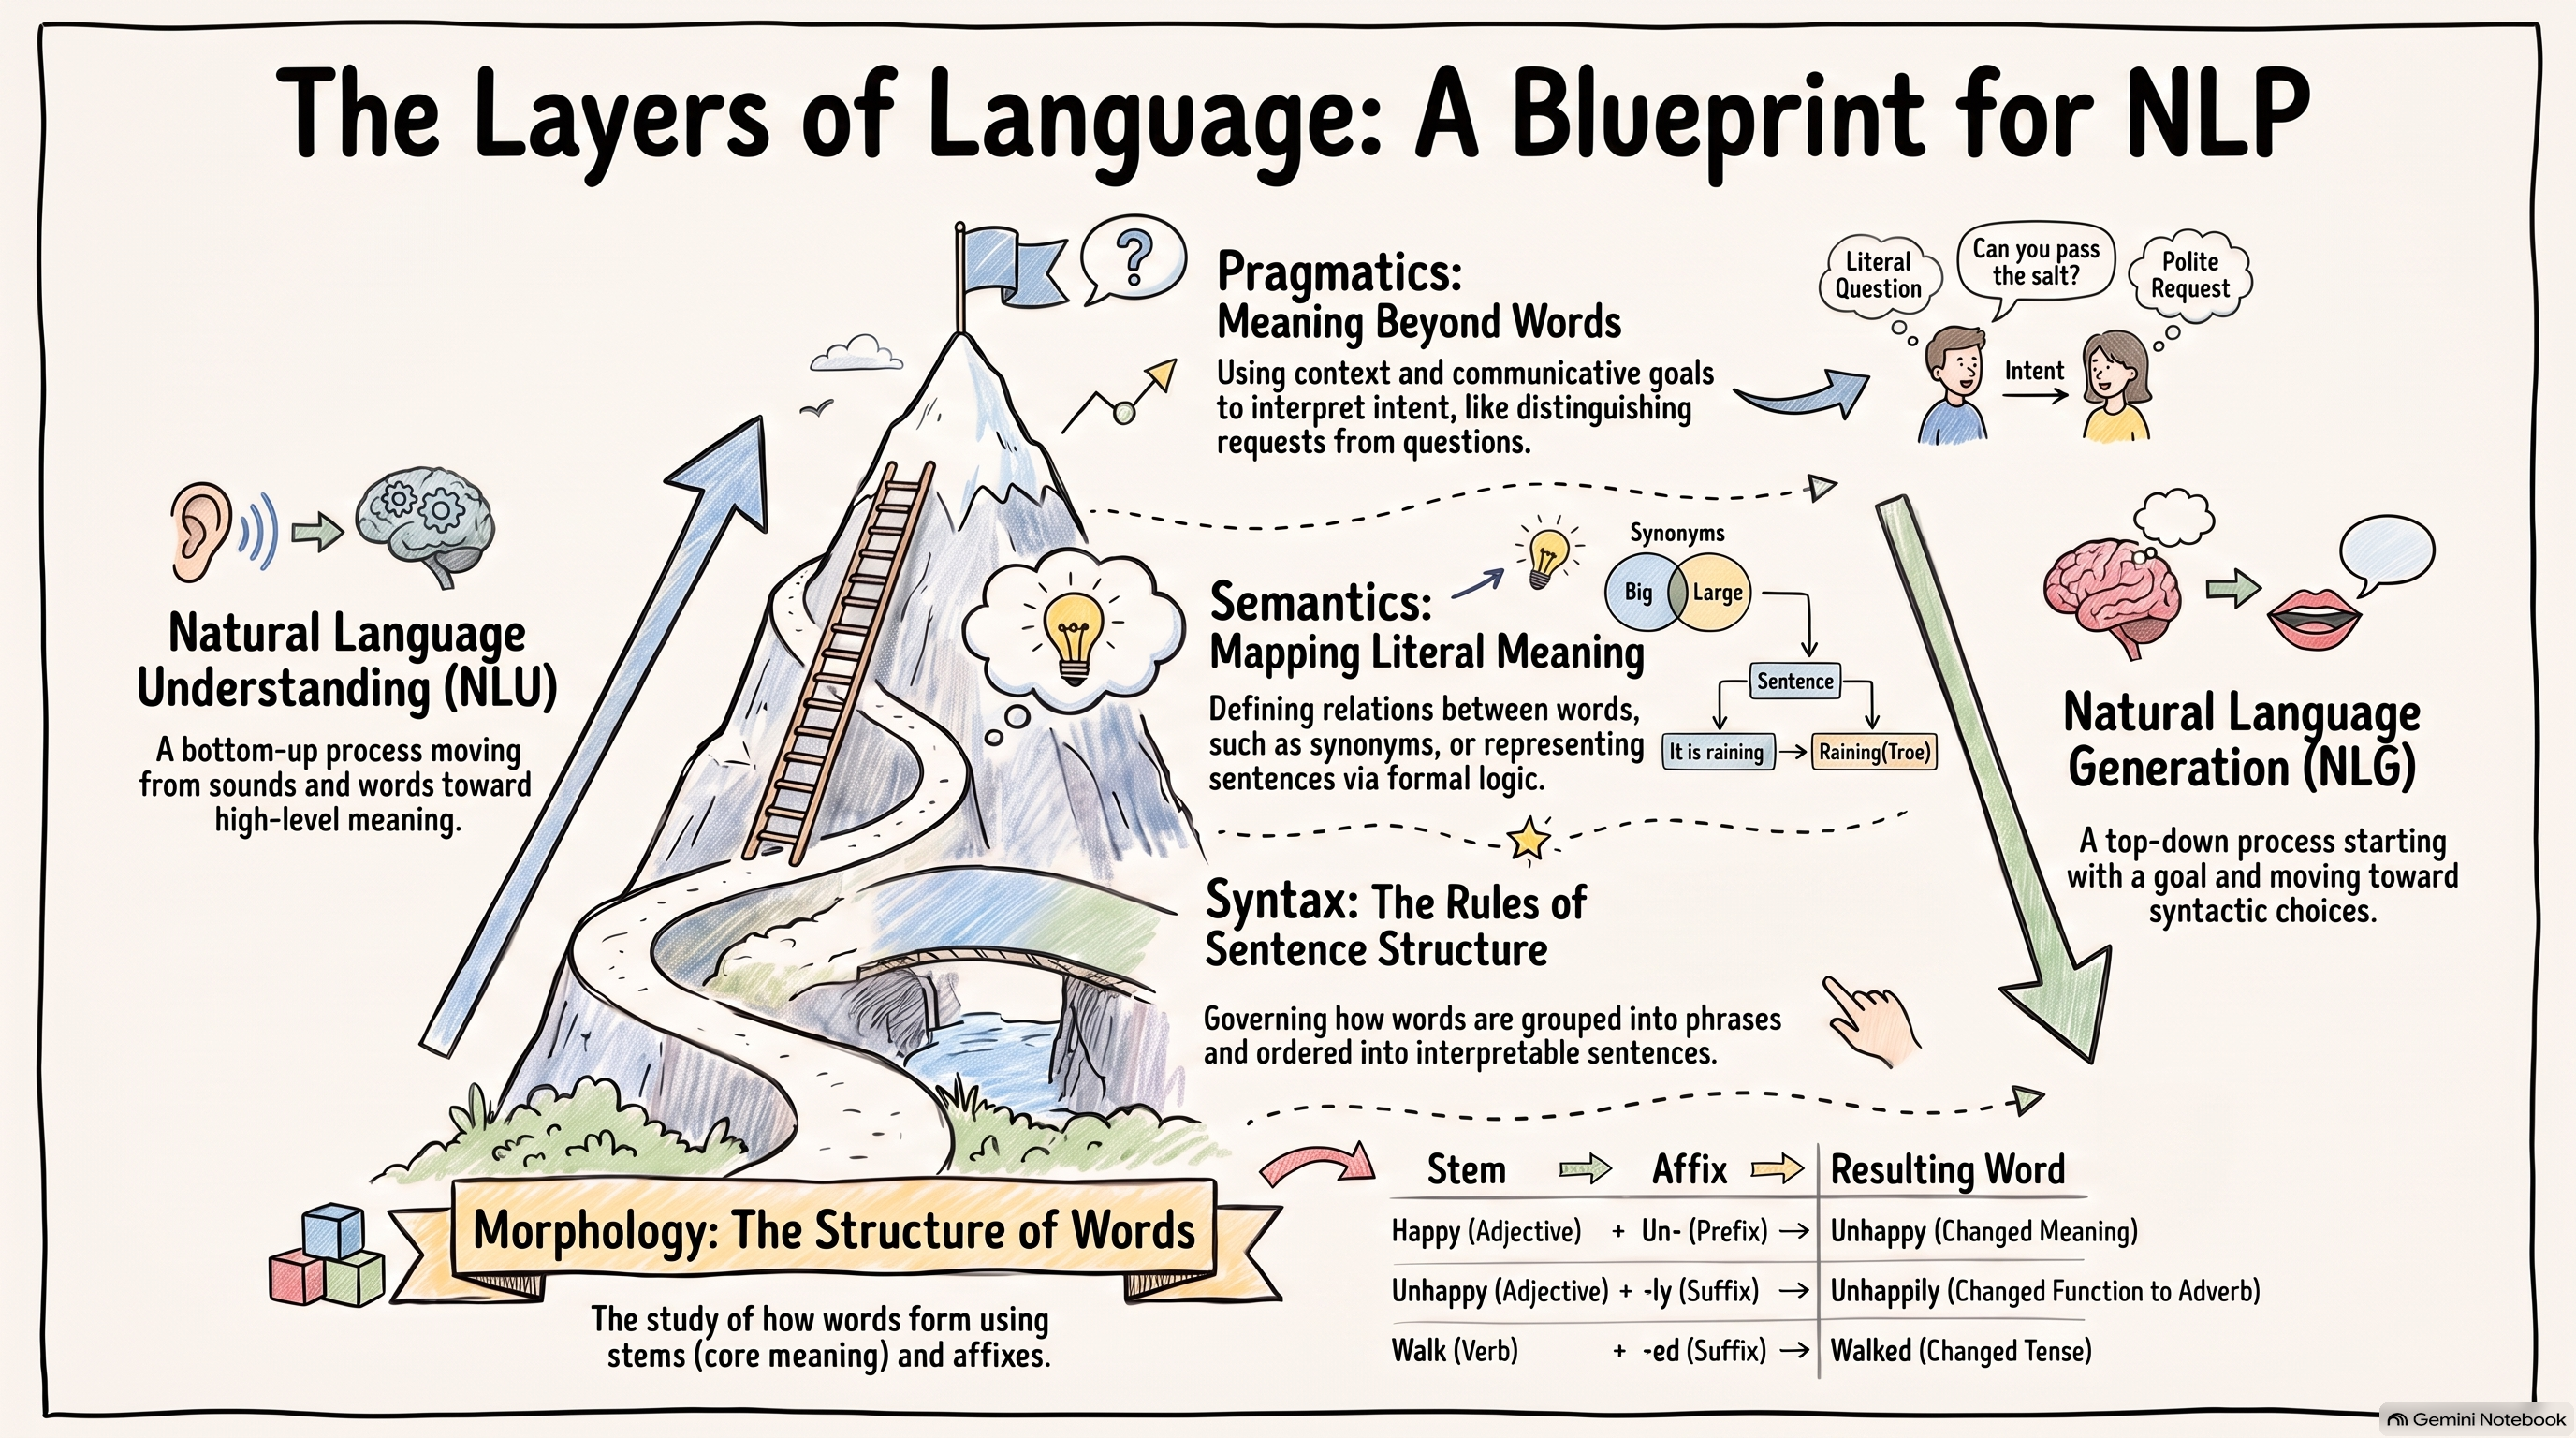
Reading note: the arrows show conceptual relationships. Pragmatics and discourse can be discussed separately. Understanding and generation are not strictly inverse computational procedures.
Morphemes, roots, and affixes
A morpheme is a minimal unit carrying meaning or grammatical function. A root carries a word's central meaning; an affix attaches to another element and changes meaning or grammatical function. Cats contains cat and the plural affix -s. A stem is the base to which an inflectional affix can be added, and need not be identical to a root. Words and Tokens
Inflection expresses grammatical information such as number or tense: cat → cats. Derivation creates a new word: happy → unhappy. Derivation may change word class, but does not always do so. Chinese radicals help us recognize written character structure; they are not equivalent to morphemes. English root-and-affix analysis cannot simply be transferred to Chinese character components.
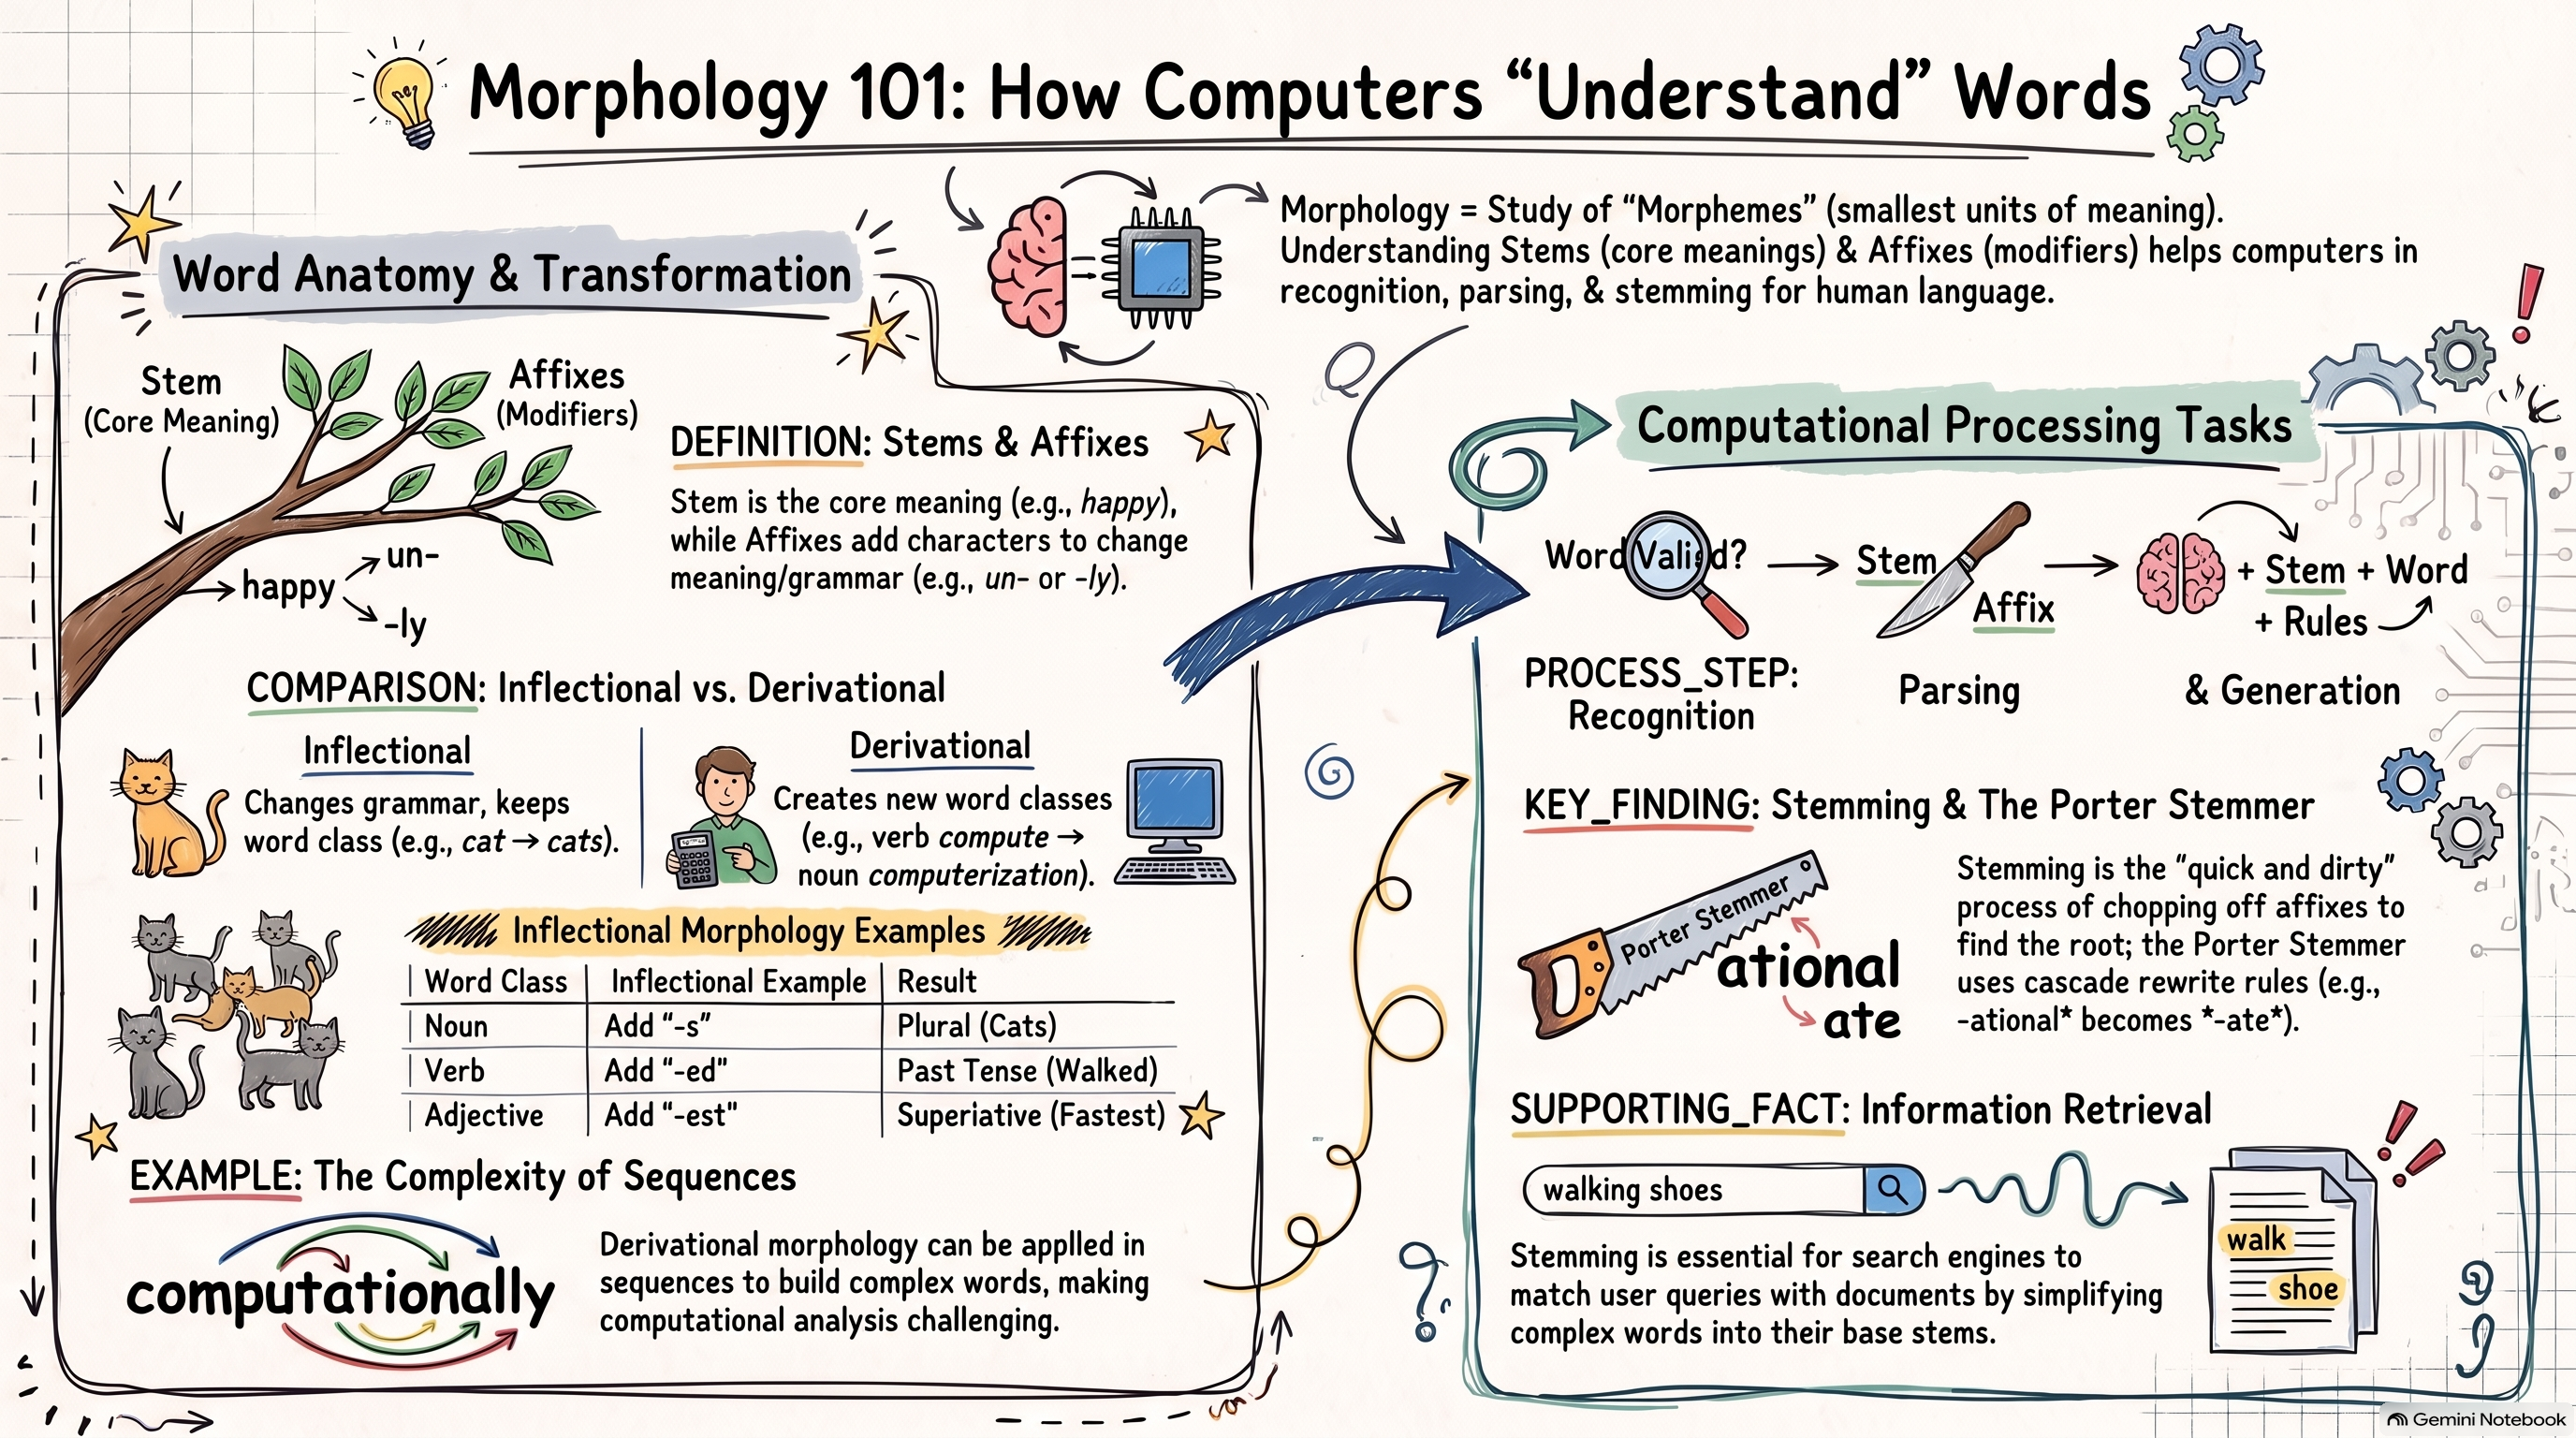
Reading note: lies can be a plural noun or a verb form, depending on context. Derivation does not always change word class. Stemming need not recover a true root, is not required by every search system, and does not guarantee better retrieval. The Chinese figure's unhappy → happy illustration is not a general Porter rule.
Turning running text into units
Tokenization divides text into processing units, which may be words, subwords, or characters. Tokens need not correspond to linguistic morphemes. Sentence segmentation identifies sentence boundaries. Normalization standardizes selected forms, such as excess spaces or capitalization. Words and Tokens
These choices should serve the research question. More aggressive cleaning is not automatically better. In interview analysis, deleting a negation can change what a participant said; merging word forms can remove a tense distinction that matters. Keep the original text and make each transformation explicit.
A corpus is a collection of texts assembled for analysis. A vocabulary records the distinct items obtained under chosen processing rules. Different tokenization and normalization choices can produce different vocabularies from the same material.
Stemming and lemmatization
| Method | Approach | Interpreting the output |
|---|---|---|
| Stemming | Apply rules that remove or rewrite parts of word forms | The result may not be a dictionary word |
| Lemmatization | Use lexical and morphological information to find a base form | Results depend on the tool and available part-of-speech information |
Porter is a classic English stemming algorithm that applies ordered suffix rules with conditions. It does not simply remove every affix and is not a solution for every language. Lemmatization can map the verb was to be, although tools may behave differently without part-of-speech information. Porter algorithm; NLTK examples
Both approaches can group related forms. Neither name alone tells us which will be more accurate or faster in a particular workflow. Check whether the method merges expressions that the research needs to distinguish.
Regular expressions turn patterns into rules
A regular expression, or regex, describes a string pattern for searching, replacement, or format checking. Matching a pattern does not establish what an entire sentence means.
This example uses Python syntax. [wW] selects one character, s? allows an optional s, and \b marks a word boundary. Python re documentation
import re

text = "Woodchuck woodchucks woodchuckish"
matches = re.findall(r"\b[wW]oodchucks?\b", text)
print(matches)  # ['Woodchuck', 'woodchucks']

print(re.sub(r" +", " ", "follow   up"))  # follow up
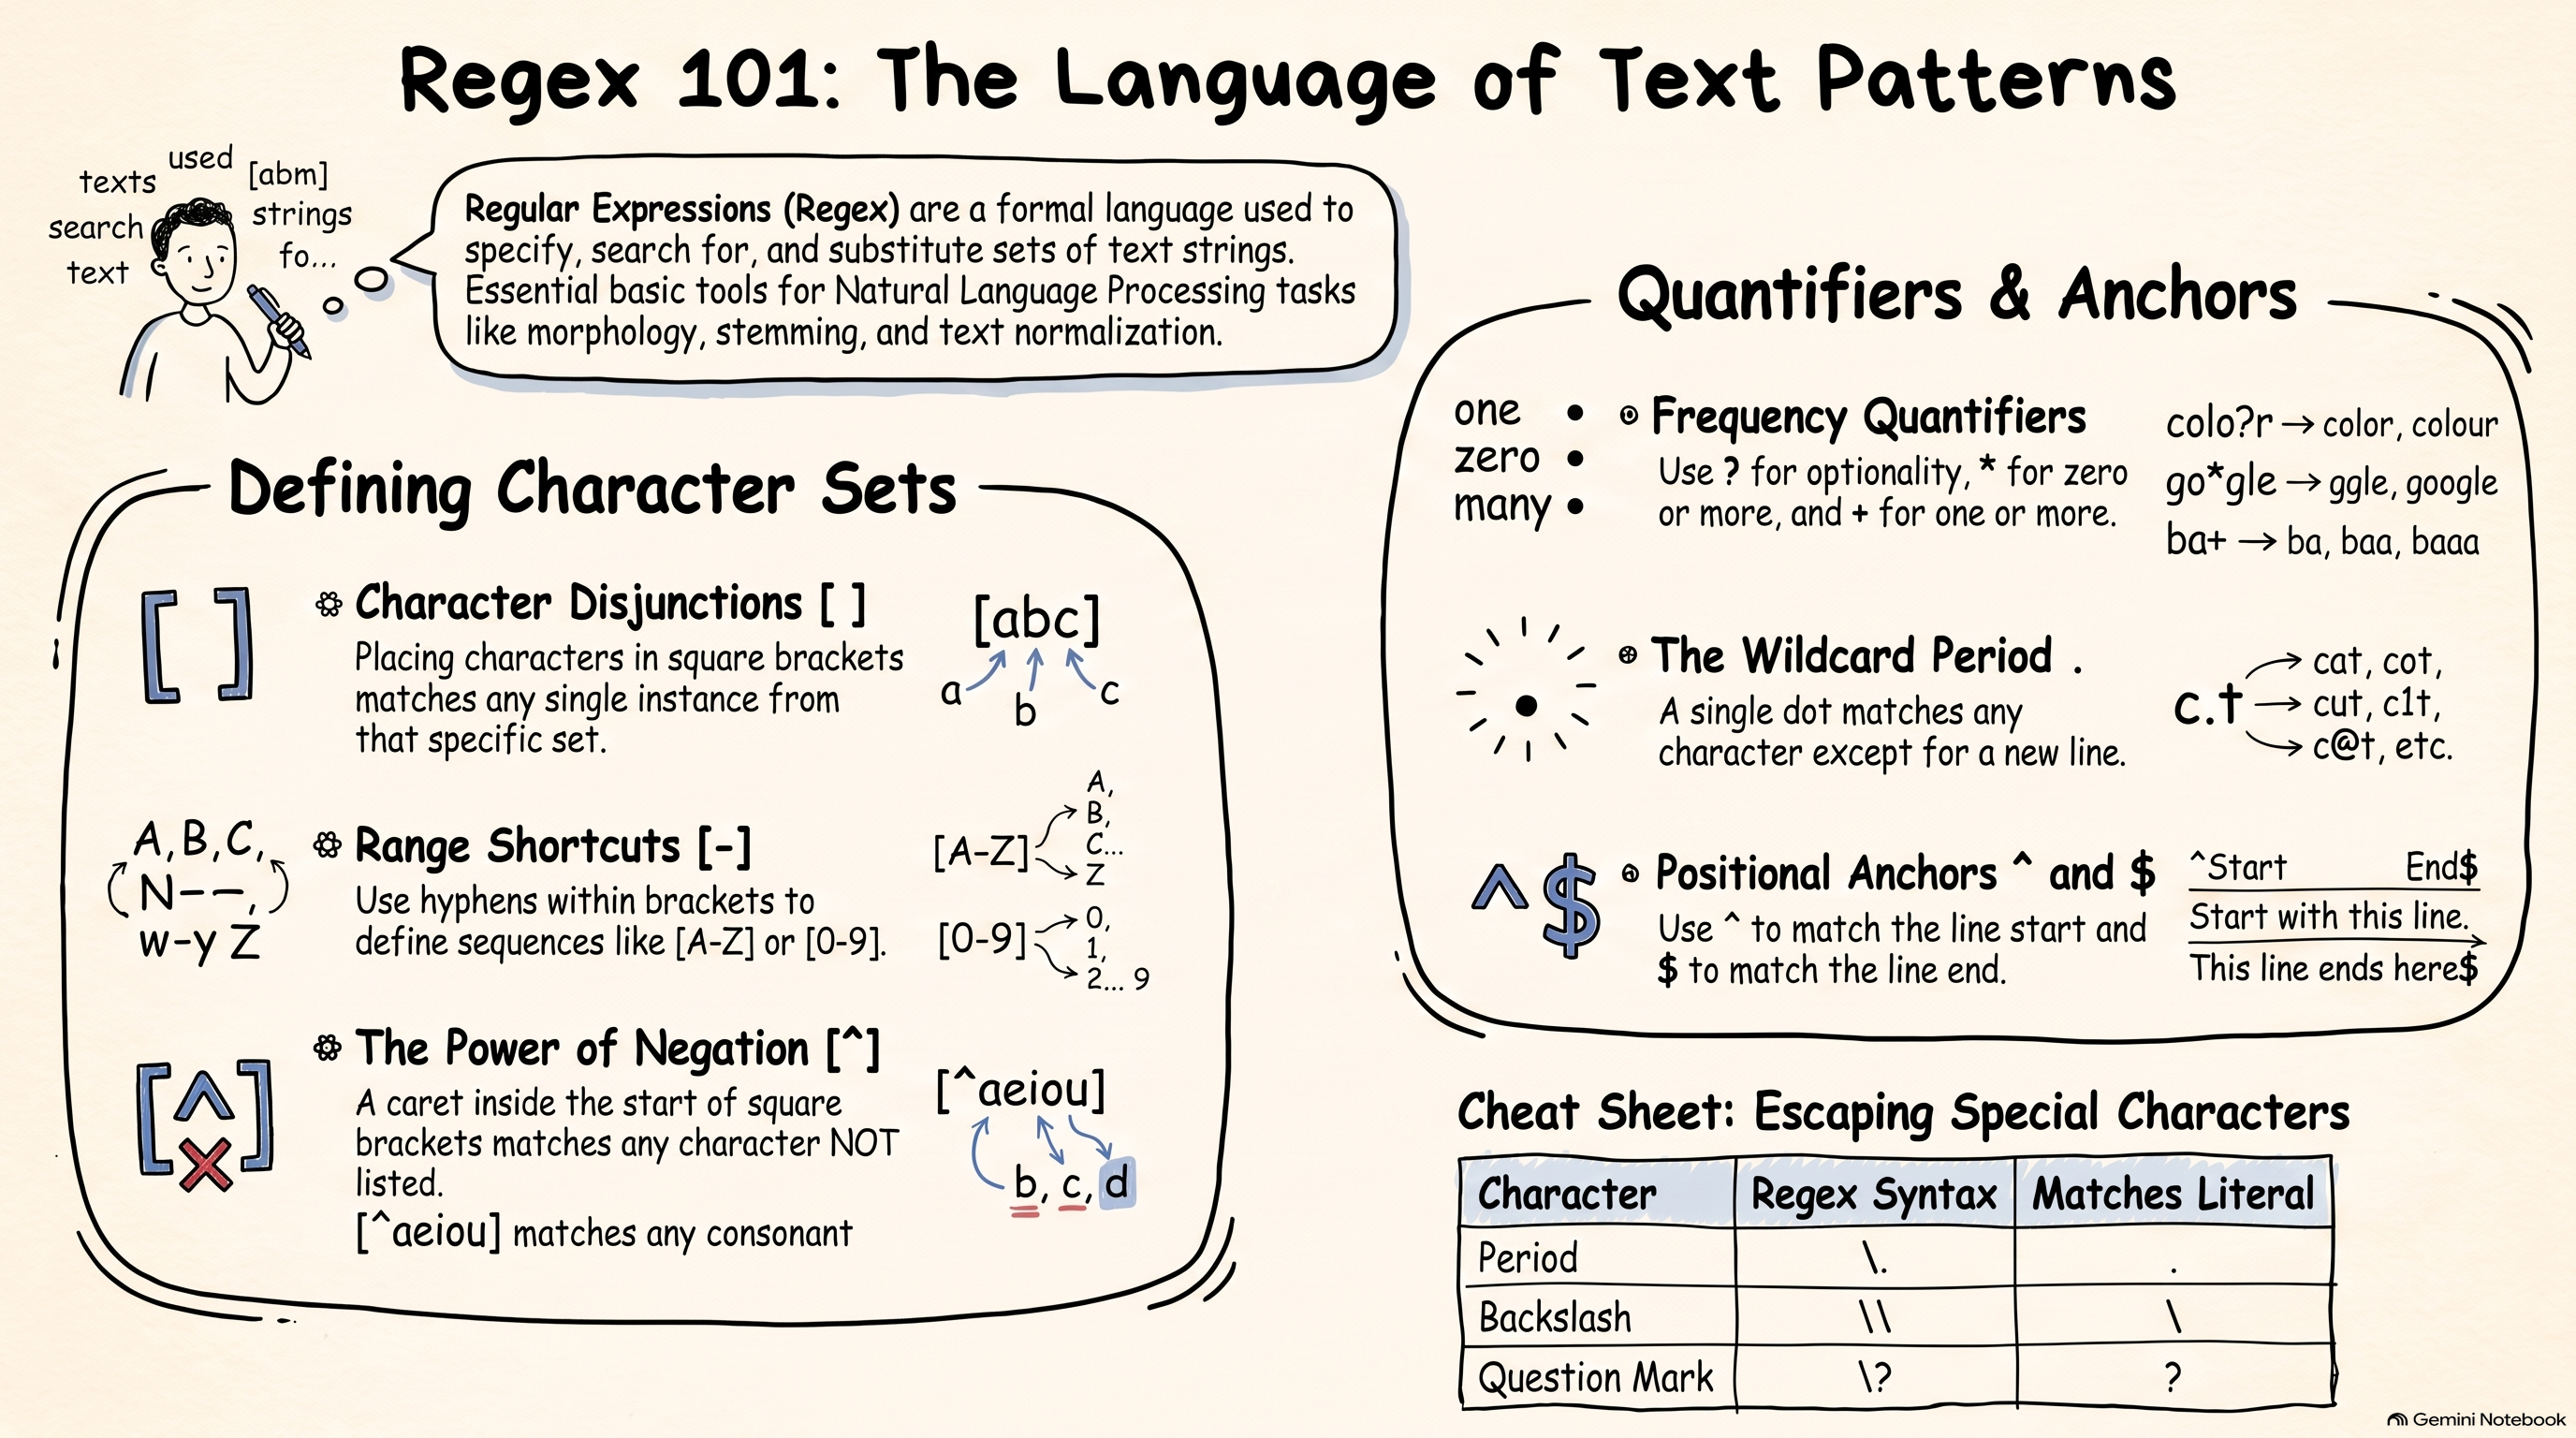
Reading note: the color/colour pattern should be colou?r, not colo?r. [^aeiou] also matches digits and other non-vowel characters. In the Chinese figure, [wW] matches only w or W, woodchunks should be woodchucks, and [^A-Z] matches a single character outside ASCII uppercase letters. \. matches a period, not all of 1.5. Anchor behavior depends on multiline mode; a dot excludes newlines by default.
Searching an English interview for pain finds both “I have pain” and “I have no pain.” A rule can locate passages for review. Determining whether a passage describes an experience or viewpoint still requires context.
My thoughts
I started studying this topic because I wanted to understand how NLP works. Its methods used to feel complicated. Seeing the relationships between word structure, sentence organization, and meaning makes the field more approachable. Comparing it with learning a language helps me get started, although that analogy does not explain all the mechanisms of modern models.
For this stage, memorizing every method is not my priority. A coding assistant can help implement simple rules. I want to understand why those rules are designed as they are, and which judgments still belong to the person using them.
Understanding the basic logic of text processing helps me break a research question into explicit steps and have a computer process health-related text or notes according to rules I define. I need to decide what to look for, what to preserve, and how to check the results.
For example: organizing accounts of appointment waits in patient interviews
Suppose I want to explore patients' experiences of waiting to get an appointment. These three fictional interview excerpts illustrate distinctions that a human reader would need to preserve:
| Interview excerpt | Information to preserve |
|---|---|
| "I waited three weeks to get an appointment with a doctor." | An appointment wait of three weeks is reported. Classifying it as excessive would require an explicit research criterion. |
| "I didn't wait long this time. I got an appointment quickly." | A long wait is explicitly negated. The word "wait" alone should not trigger a label of difficulty. |
| "I used to wait a long time, but things are better now." | A long wait in the past and improvement now are distinct pieces of information. |
I could design the process in a few steps:
- Define the target: specify which accounts of appointment waits fall within the research question.
- Normalize selected forms and keep the original: record "three weeks" and "3 weeks" as the same duration while retaining the source sentence.
- Find candidate passages: use keywords or regular expressions to locate expressions about appointments, waiting, and duration.
- Check negation and time: use context to distinguish "didn't wait long" from "waited a long time," and past experiences from current ones.
- Organize and review: output the original sentence, waiting duration, negation, and temporal information, then compare a small sample with manual reading to identify missed and incorrectly selected passages.
This example clarifies my role: define the processing goal, design the rules, and check the output. Regex can help locate text patterns, but deciding what "things are better now" refers to may require more complex methods or human judgment. This is an application I would like to explore; I have not yet tested it in practice.
My remaining question is which foundations I need to use NLP effectively. Next, I can explore tokenization and context handling, and examine where simple rules stop being sufficient.
Learning sources
This article grew out of notes for UBC's Natural Language Processing to Improve Patient Care micro-certificate. The source draft names the course Overview of NLP and Large Language Models. Technical checks used the Stanford textbook, official Python documentation, Porter algorithm description, and NLTK examples linked above.
Explore it yourself
To explore regular expressions interactively, try regex101. Enter a pattern and sample text to inspect matches and explanations. For the examples in this note, choose the Python flavor to match the code syntax.