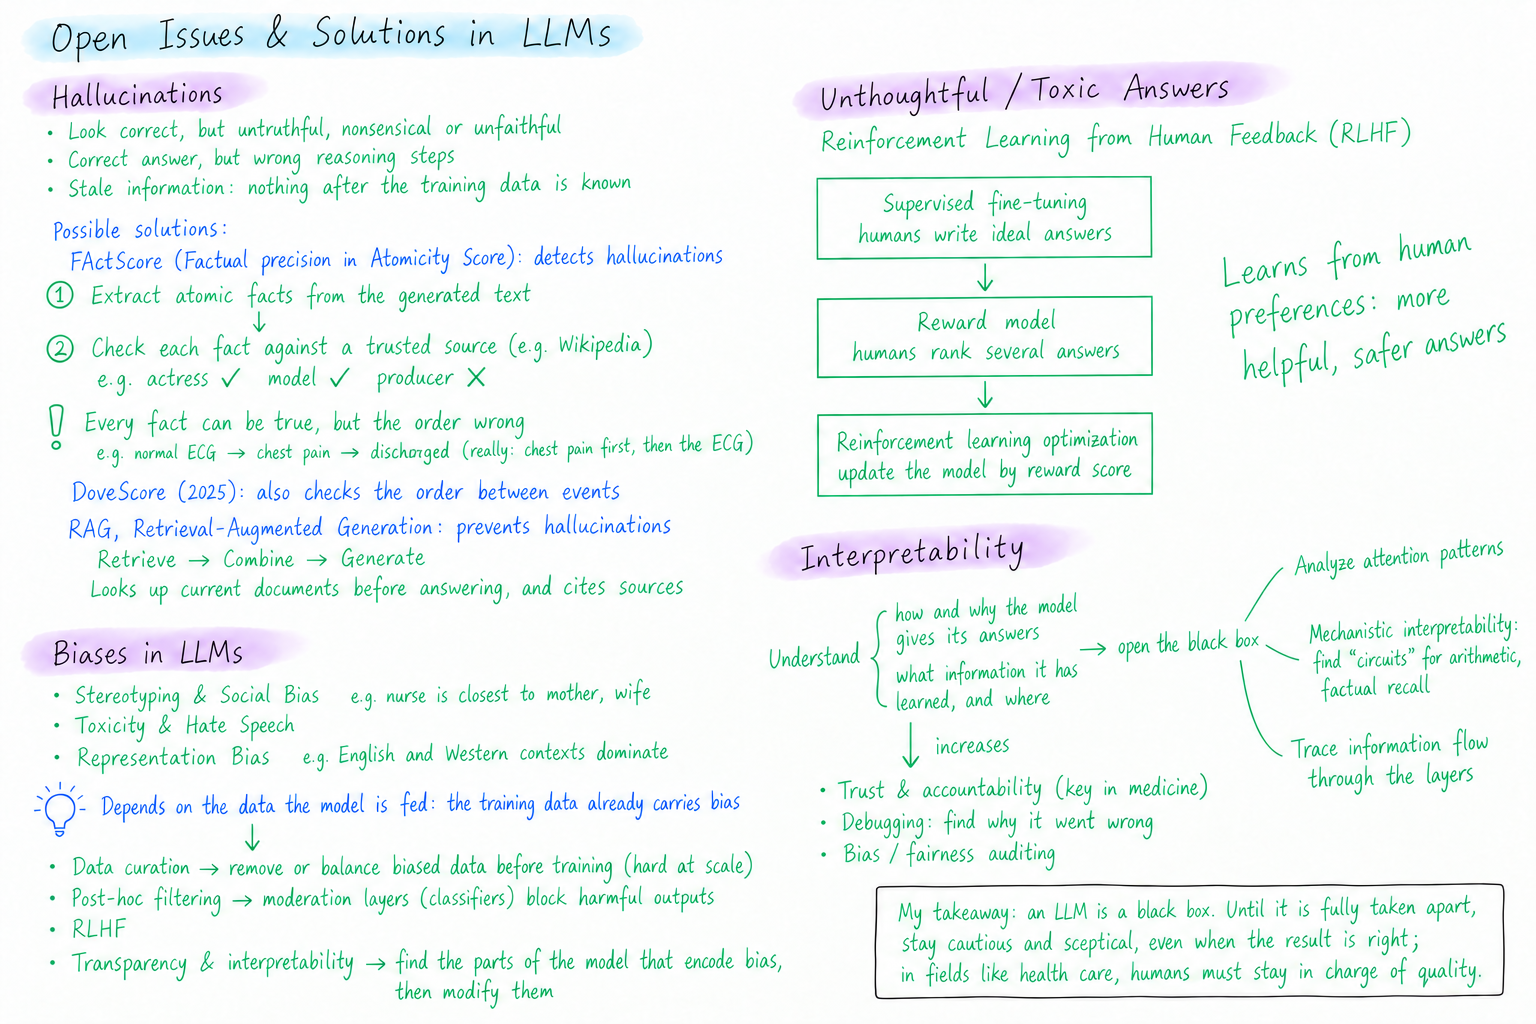
From hallucination and stale information through FActScore, DoveScore and RAG to RLHF, bias mitigation and interpretability: where the problems of large language models come from and how they can be reduced.
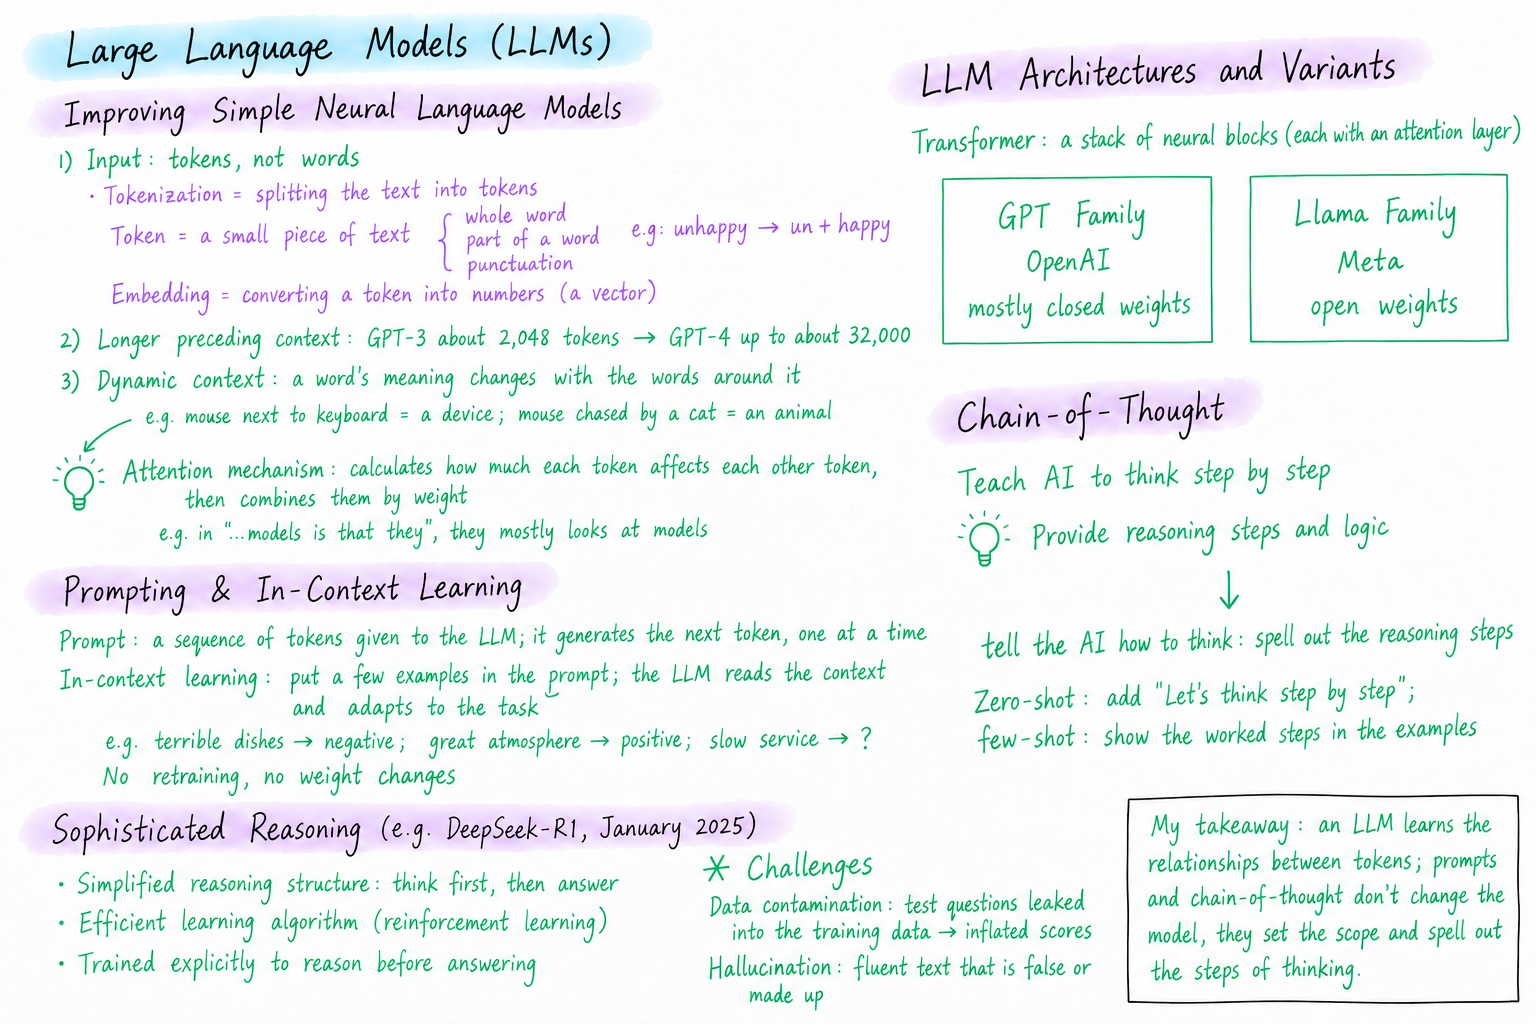
From three improvements on neural language models (tokens, longer context and attention) through the Transformer and the GPT and Llama families: prompting, in-context learning, chain-of-thought and models trained to reason.
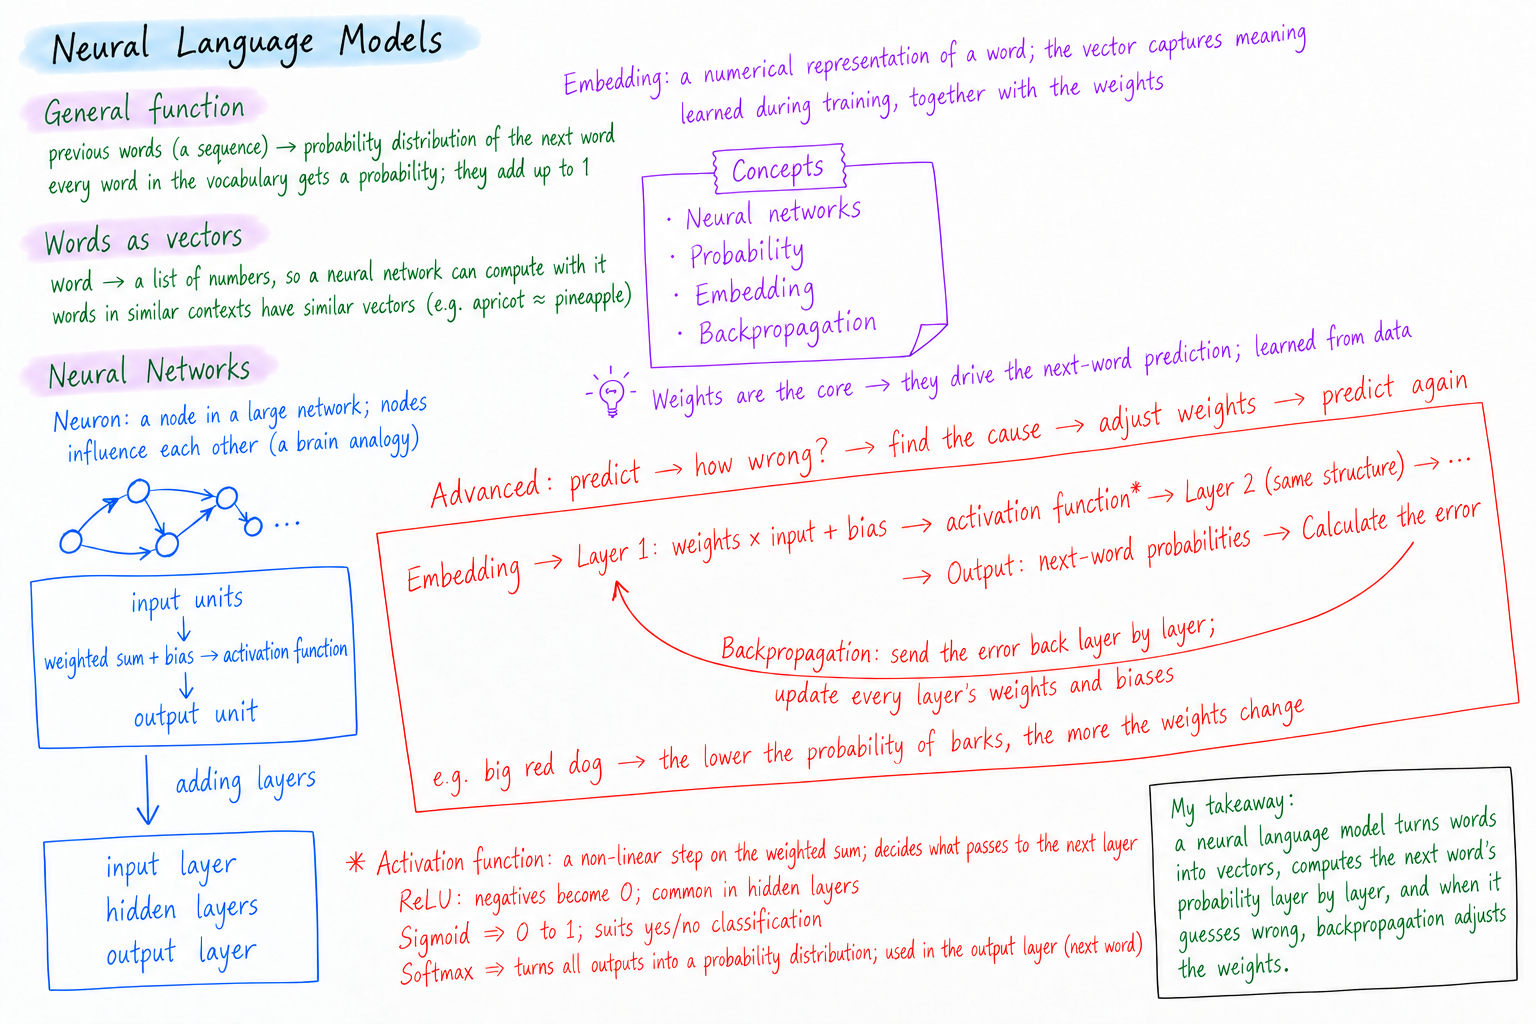
From what every language model computes through embeddings, neurons, activation functions and backpropagation: how a neural network learns to predict the next word.
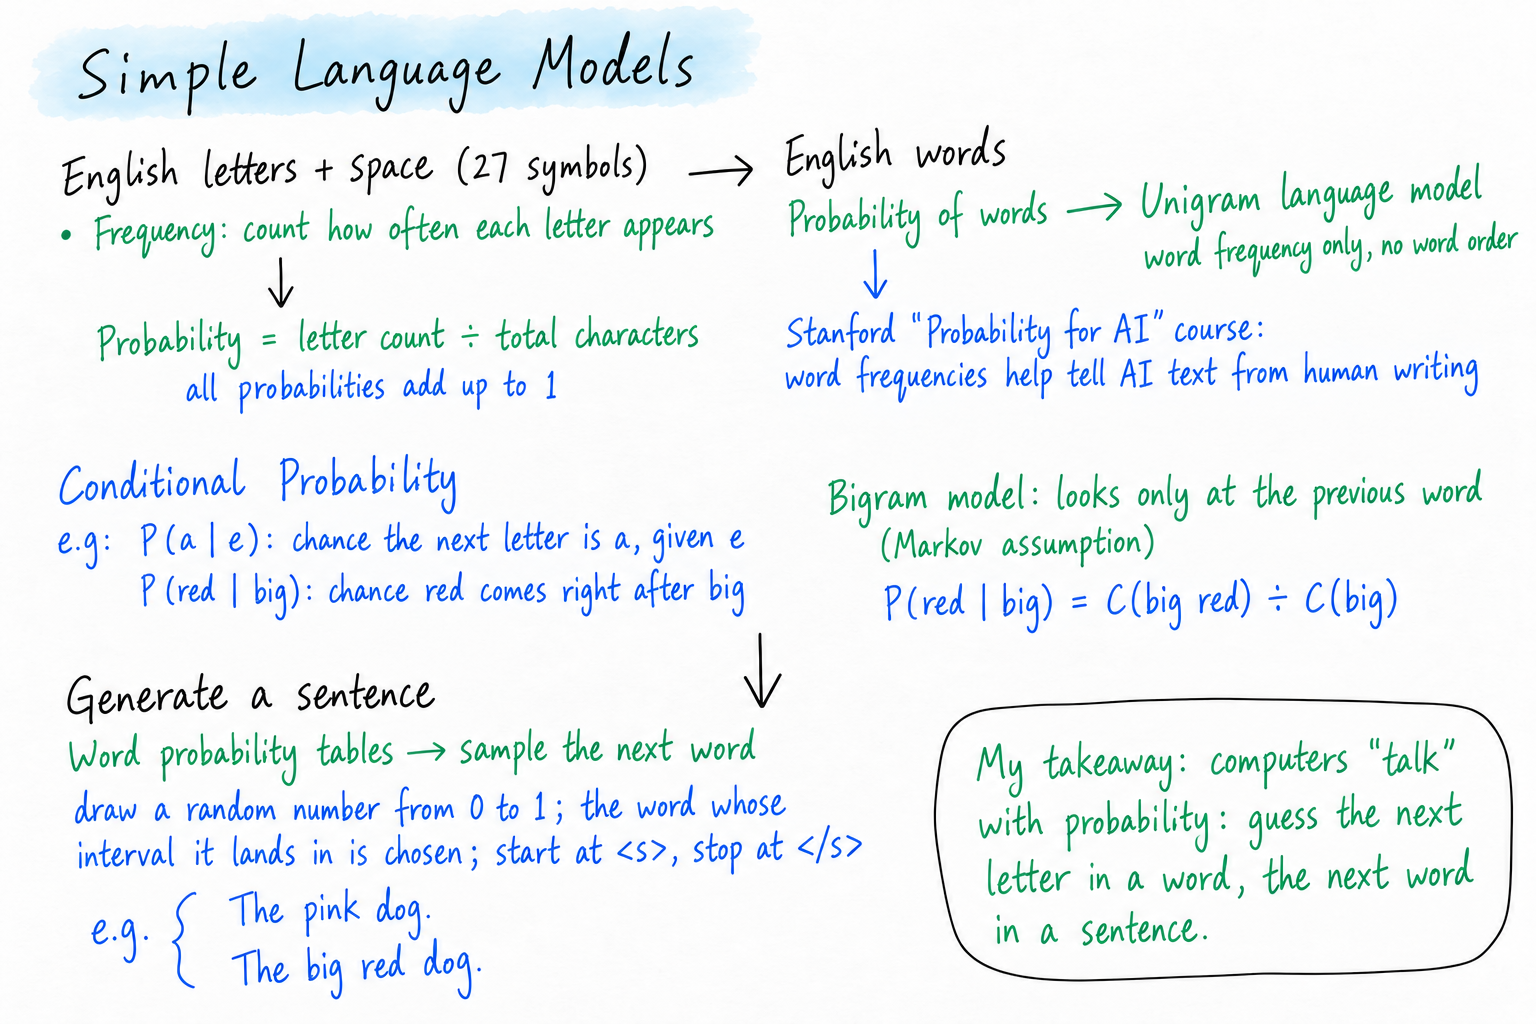
From letter and word frequencies through conditional probability and bigrams: how a simple language model scores a sentence and writes one word at a time.